


1. Introduction
1.1 Combinatorial refinement and canonization of random graphs
As is well known, the graph isomorphism problem is very efficiently solvable in the average case by a simple combinatorial method known as colour refinement (also degree refinement or naive vertex classification). When a random graph
 $\mathbf{G}_n$
on
 $n$
vertices is taken as an input, this algorithm produces a canonical labelling of all vertices in
 $\mathbf{G}_n$
by colouring them initially by their degrees and then by refining the colour classes as follows: Two equally coloured vertices
 $u$
and
 $v$
get new distinct colours if one of the initial colours occurs in the neighbourhoods of
 $u$
and
 $v$
with different multiplicity. In this way, every vertex gets a unique colour with probability
 $1-O(n^{-1/7})$
(Babai, Erdős, and Selkow [Reference Babai, Erdős and Selkow5]). Thus, the method produces a canonical labelling for almost all graphs on a fixed set of
 $n$
vertices.
This approach is not applicable to regular graphs, even with many refinement rounds, because if all vertices have the same degree, then the refinement step makes obviously no further vertex separation. Weisfeiler and Leman [Reference Weisfeiler and Leman46] came up with a more powerful refinement algorithm which colours pairs of vertices instead of single vertices (see Section 7.1 for a formal description). The idea can be lifted to
 $k$
-tuples of vertices, for each integer parameter
 $k$
, and the general approach is referred to as the
 $k$
-dimensional Weisfeiler–Leman algorithm, abbreviated as
 $k\text{-}\textrm{WL}$
. Thus,
 $2\text{-}\textrm{WL}$
is the original algorithm in [Reference Weisfeiler and Leman46], and
 $1\text{-}\textrm{WL}$
corresponds to colour refinement. Remarkably,
 $2\text{-}\textrm{WL}$
is powerful enough to produce a canonical labelling for almost all regular graphs of a given vertex degree (Bollobás [Reference Bollobás9]; see also [Reference Kucera31]).
Further restriction of regular input graphs to vertex-transitive graphs is challenging for combinatorial refinement because no vertex classification is at all possible in this case. Indeed,
 $2\text{-}\textrm{WL}$
assigns the same colour to any two vertices
 $u$
and
 $v$
(or, more precisely, to the pairs
 $(u,u)$
and
 $(v,v)$
) because
 $u$
is mapped to
 $v$
by an automorphism of the graph. The same holds for any dimension
 $k$
.
Moreover, the graph isomorphism problem for vertex-transitive graphs is provably unsolvable by
 $k\text{-}\textrm{WL}$
for any fixed dimension
 $k$
. Indeed, the Cai–Fürer–Immerman (CFI) construction [Reference Cai, Fürer and Immerman11] of non-isomorphic graphs
 $X_k$
and
 $Y_k$
indistinguishable by
 $k\text{-}\textrm{WL}$
can be modified so that these graphs become vertex-transitive [Reference Fuhlbrück, Köbler, Ponomarenko and Verbitsky23]. A natural way to enhance combinatorial refinement is to combine it with vertex individualization – that is, assigning a special colour to one vertex in the graph [Reference McKay and Piperno33]. While this algorithmic approach proves advantageous in many contexts (see, e.g., [Reference Babai, Chen, Sun, Teng and Wilmes4]), it nevertheless fails to overcome the obstacle posed by the CFI graphs. To see this, note that
 $(k+k')\text{-}\textrm{WL}$
is more powerful than any combination of
 $k\text{-}\textrm{WL}$
with prior individualization of
 $k'$
vertices. As a consequence, for any pair of arbitrarily large integers
 $k$
and
 $k'$
, isomorphism of vertex-transitive graphs cannot be solved by
 $k\text{-}\textrm{WL}$
even under individualization of
 $k'$
vertices.
Motivated by the question of whether or not these basic obstacles persist in the average case setting, we focus in this paper on Cayley graphs and, more specifically, on circulant graphs, that is, Cayley graphs of a cyclic group. While the canonization problem for this class of graphs is known to be solvable in polynomial time [Reference Evdokimov and Ponomarenko19] by advanced algebraic methods, it is an open question whether this can be done by using
 $k\text{-}\textrm{WL}$
for some fixed dimension
 $k$
; see [Reference Ponomarenko38, Reference Wu and Ponomarenko47]. This poses an ongoing challenge for the combinatorial refinement method, especially because the research on isomorphism of circulant graphs has a long history with many deep results (see [Reference Babai3, Reference Evdokimov and Ponomarenko19, Reference Muzychuk35, Reference Muzychuk, Klin and Pöschel36] and the references therein) and because
 $k\text{-}\textrm{WL}$
with small dimension
 $k$
is known to be applicable to many other natural graph classes (e.g., planar graphs [Reference Kiefer, Ponomarenko and Schweitzer28]). The recent paper [Reference Kluge29] investigates the round complexity of
 $2\text{-}\textrm{WL}$
on circulant graphs, exploiting the close connections of the subject with intricate mathematical concepts. Circulant graphs are also interesting on their own right as they naturally appear and are intensively investigated in many other theoretical and applied areas; see, e.g., the books [Reference Bose and Saha10, Reference Davis14, Reference Dobson, Malnič and Marušič16]. After all, our primary motivation for the study of circulant graphs is that this is the most natural first choice of a graph class for benchmarking of combinatorial refinement in the realm of vertex-transitive graphs.
1.2 Our contribution: random circulant graphs
We begin by fixing the basic notation and terminology. Throughout the paper, the isomorphism relation
 $X\cong Y$
for graphs
 $X$
and
 $Y$
refers to the standard combinatorial notion of graph isomorphism, regardless of any underlying algebraic structure on the vertex sets of
 $X$
and
 $Y$
. In particular, when speaking of isomorphisms and automorphisms of graphs, we always mean the standard graph-theoretic concepts.
For a bijective vertex labelling
 $\lambda \, : \, V(X) \rightarrow \{0,1,\ldots ,n-1\}$
of an
 $n$
-vertex digraph
 $X$
, let
 $X^\lambda$
denote the relabelled version of
 $X$
, that is, the digraph on vertex set
 $\{0,1,\ldots ,n-1\}$
containing an edge from
 $x$
to
 $y$
whenever
 $X$
contains an edge from
 $\lambda ^{-1}(x)$
to
 $\lambda ^{-1}(y)$
. Given an input digraph
 $X$
, a canonical labelling algorithm produces a canonical labelling
 $\lambda _X$
of
 $X$
, which satisfies the following properties:
-
• a labelling
 $\lambda _Y$
is computed by the algorithm also for every
$Y\cong X$
, and
-
•
$X^{\lambda _X}=Y^{\lambda _Y}$
for all such
$Y$
.


When applied to a randomly chosen
 $X$
, such an algorithm may occasionally fail, i.e., terminate without producing any output (this failure occurs simultaneously for all isomorphic inputs). We say that the algorithms succeeds with probability at least
 $1-\varepsilon (n)$
, if the failure probability on the inputs with
 $n$
vertices does not exceed
 $\varepsilon (n)$
.
Canonical labelling of a random circulant
Our goal is to show that the individualization-refinement approach can be used to canonize almost all circulants at minimal computational costs. Our treatment covers also circulant directed graphs, which is advantageous for expository purposes as the case of digraphs is technically somewhat simpler. We show that the individualization of a single vertex suffices for random circulant digraphs, and that two individualized vertices are enough in the undirected case (in fact, we just perform colour refinement twice, each time with a single individualized vertex). In both the directed and undirected cases, we maintain an overall running time of
 $O(n^2\log n)$
, which is the standard running time of colour refinement [Reference Cardon and Crochemore12]. This is possible because our input graphs are vertex-transitive, and hence, it does not actually matter which vertex is individualized – even though, in the undirected case, the choice of the second vertex to be individualized is not arbitrary. Here,
 $n$
denotes the number of vertices. Thus, our time bound is actually linearithmic, that is, it is
 $O(N\log N)$
for the input length
 $N$
where the input (di)graph is presented by the adjacency matrix and the cyclic structure is not explicitly given (see below the discussion of different representation concepts). Note also that, as one might expect, our average-case bound of
 $O(n^2 \log n)$
is substantially better than the worst-case bound resulting from [Reference Evdokimov and Ponomarenko19].Footnote
1
We summarize our main result in a somewhat condensed form as follows.
Theorem 1.1 (Main theorem). A uniformly random circulant (di)graph with
 $n$
vertices is with probability at least
 $1-n^{-1/2+o(1)}$
canonizable by colour refinement combined with vertex individualization in running time
 $O(n^2\log n)$
.
Theorem1.1 includes two statements, one for undirected graphs (where all undirected circulant graphs are equiprobable) and the similar statement for directed graphs. Note that the concept of a uniform distribution of
 $n$
-vertex circulants is somewhat ambiguous as the notion of an
 $n$
-vertex circulant alone can be defined in three different natural ways:
-
• as a Cayley (di)graph of the cyclic group
$\mathbb{Z}_n$
, -
• as an isomorphism class of Cayley (di)graphs of
$\mathbb{Z}_n$
(which we call an unlabelled circulant), -
• as a (di)graph on the vertex set
$\{0,1,\ldots ,n-1\}$
isomorphic to a Cayley (di)graph of
$\mathbb{Z}_n$
(which we call a labelled circulant).


More formally, a connection set
 $S \subseteq \mathbb{Z}_n \! \setminus \! \{0\}$
defines the Cayley digraph
 $\textrm {Cay}(\mathbb{Z}_n, S)$
, where two vertices
 $x, y \in \mathbb{Z}_n$
form a directed edge
 $(x, y)$
if
 $y - x \in S$
. If
 $S$
is inverse-closed, that is,
 $S = -S$
, then
 $\textrm {Cay}(\mathbb{Z}_n, S)$
is undirected. When referring to a random Cayley (di)graph, we assume that all connection sets (with
 $S = -S$
in the undirected case) are equally likely. Detailed definitions of the other two distributions are provided in Section 6.
We first prove Theorem1.1 for random Cayley digraphs and graphs (see the proof outline in Section 2), and then extend the result to the other two concepts. The transition from one distribution to another is quite general and is based on known results in algebraic graph theory [Reference Bhoumik, Dobson and Morris8, Reference Dobson, Spiga and Verret15, Reference Muzychuk35].
Canonical Cayley representation
Our canonical labelling algorithm in Theorem1.1 is based on individualization of a single vertex in the input digraph followed by colour refinement (or
 $1\text{-}\textrm{WL}$
in other terminology). The aforementioned 2-dimensional Weisfeiler–Leman algorithm (
 $2\text{-}\textrm{WL}$
) is strictly stronger than the combination of
 $1\text{-}\textrm{WL}$
with one-vertex individualization (cf. [Reference Rattan and Seppelt40, Theorem 3.2]). It turns out that
 $2\text{-}\textrm{WL}$
can be used to solve an even more challenging algorithmic problem than computing a canonical labelling, which we describe below.
Theorem1.1 provides an algorithm for producing a canonical labelling
 $\lambda _X$
of a random circulant
 $X$
. Note, however, that the proof does not guarantee that the canonical form
 $X^{\lambda _X}$
is a Cayley digraph of
 $\mathbb{Z}_n -$
or, equivalently, that the cycle
 $(\lambda _X^{-1}(0),\lambda _X^{-1}(1),\ldots ,\lambda _X^{-1}(n-1))$
is an automorphism of
 $X$
. In cases where this condition holds, i.e., when
 $X^{\lambda _X}=\textrm {Cay}(\mathbb{Z}_n,S)$
for some connection set
 $S$
, we say that the map
 $\lambda _X$
is a Cayley representation of
 $X$
. We are interested in an algorithm which, with high probability, succeeds in computing a map
 $\lambda _X$
that is both a canonical labelling and a Cayley representation of
 $X$
.
Theorem 1.2. A uniformly random labelled circulant admits a canonical Cayley representation computable by means of
 $2\text{-}\textrm{WL}$
in time
 $O(n^3\log n)$
with success probability
 $1-O(n^22^{-n/8})$
.
Compared to Theorem1.1, the proof of Theorem1.2 requires less technical effort, primarily due to the greater expressive power of the
 $2\text{-}\textrm{WL}$
algorithm. Moreover, this algorithm is closely related to the notion of a coherent configuration in algebraic combinatorics [Reference Chen and Ponomarenko13]. This connection enables us to leverage strong results from algebraic graph theory [Reference Bhoumik, Dobson and Morris8, Reference Dobson, Spiga and Verret15, Reference Evdokimov and Ponomarenko21], whose algorithmic interpretation is the core of Theorem1.2.
2. Proof strategy and further implications
2.1 Proof overview of the main theorem: the power of walk counts
Remarkably, we show that canonization of a random circulant does not even need the full power of colour refinement and can actually be accomplished by a weaker algorithmic tool. Let
 $G$
be an arbitrary (di)graph on the vertex set
 $V=\{0,1,\ldots ,n-1\}$
, and let
 $T\subseteq V$
. The walk matrix
 $W_T=(w_{ik})_{i,k\in V}$
is defined by setting
 $w_{ik}$
to be the number of walks of length
 $k$
from the vertex
 $i$
to a vertex in
 $T$
. That is,
 $w_{ik}$
is the number of vertex sequences
 $x_0,x_1,\ldots ,x_k$
in
 $G$
such that
 $x_0=i$
,
 $x_k\in T$
, and the pair
 $(x_j,x_{j+1})$
is an edge of
 $G$
for every
 $j\lt k$
. If
 $A$
is the adjacency matrix of
 $G$
and
 $\chi _T$
denotes the characteristic vector of the subset
 $T$
, then
 $W_T$
is formed by the columns
 $\chi _T,A\chi _T,A^2\chi _T,\ldots ,A^{n-1}\chi _T$
. The theory of walk matrices, including their applicability to isomorphism testing, has been developed by Godsil [Reference Godsil24] and by Liu and Siemons [Reference Liu and Siemons32]. Let
 $G_T$
be obtained from
 $G$
by colouring all vertices in
 $T$
by the same colour. We call
 $G_T$
walk-discrete if the rows of
 $W_T$
are pairwise different. For any walk-discrete
 $G_T$
, the walk matrix
 $W_T$
yields a canonical labelling of the vertices of
 $G_T$
. This purely algebraic canonization method can be superseded by the purely combinatorial method of colour refinement because if
 $w_{uk}\ne w_{vk}$
for some
 $k$
, then colour refinement assigns distinct colours to the vertices
 $u$
and
 $v$
in
 $G_T$
(see Section 3.1 for details).
Let
 $W=W_V$
be the standard walk matrix of
 $G=G_V$
. Obviously,
 $G$
is walk-discrete whenever
 $W$
is non-singular. Noteworthy, the rank of
 $W$
for an undirected graph
 $G$
is equal to the number of different main eigenvalues of the adjacency matrix
 $A$
; see [Reference Hagos25]. As shown by O’Rourke and Touri [Reference O’Rourke and Touri37], a random undirected graph
 $\mathbf{G}_n$
has non-singular walk matrix with high probability. As a consequence,
 $\mathbf{G}_n$
is, with high probability, canonizable by computing its standard walk matrix.Footnote
2
The above theory essentially exploits the fact that the adjacency matrices of undirected graphs are symmetric and, by this reason, does not apply to directed graphs. Nevertheless, we obtain the following spectral criterion for circulant digraphs.
Lemma 2.1. Let
 $X$
be a Cayley digraph of a cyclic group and
 $X_0=X_{\{0\}}$
be its version with one individualized vertex. Let
 $W_0$
be the walk matrix of
 $X_0$
. Then
 $W_0$
is non-singular (implying that
 $X_0$
is walk-discrete) if and only if
 $X$
has simple spectrum, that is, all eigenvalues of
 $X$
are pairwise distinct.
Suppose now that
 $X$
is an undirected Cayley graph of
 $\mathbb{Z}_n$
. In this case, the map
 $x\mapsto (\! -x)\bmod n$
is an automorphism of
 $X_0$
, which implies that the walk matrix of
 $X_0$
has at most
 $\lceil (n+1)/2\rceil$
different rows. If this bound is achieved, we call
 $X_0$
walk-saturated. On the other hand, the spectrum of
 $X$
has at most
 $\lceil (n+1)/2\rceil$
different eigenvalues. If there are exactly so many eigenvalues, we say that
 $X$
has saturated spectrum. We have the following analogue of Lemma 2.1 for the undirected case.
Lemma 2.2. Let
 $X$
be a Cayley graph of the cyclic group
 $\mathbb{Z}_n$
. Then
 $W_0$
has the maximum possible rank
 $\lceil (n+1)/2\rceil$
(implying that
 $X_0$
is walk-saturated) if and only if
 $X$
has saturated spectrum.
As an immediate consequence of Lemma 2.1, the rows of the walk matrix yield a canonical labelling of a circulant digraph whenever it has a simple spectrum. With only a small amount of additional technical effort (see Lemma 3.2 in the next section), Lemma 2.2 implies that the walk matrix can also be used to canonize a circulant graph whenever it has a saturated spectrum. The following theorem therefore estimates the success probability of these canonization methods on random circulants.
Theorem 2.3.
-
1. If
$S\subseteq \mathbb{Z}_n\setminus \{0\}$
is chosen uniformly at random, then the Cayley digraph
$\textrm {Cay}(\mathbb{Z}_n,S)$
has simple spectrum with probability at least
$1-n^{-1/2+o(1)}$
. -
2. If
$S\subseteq \mathbb{Z}_n\setminus \{0\}$
is chosen uniformly at random among all inverse-closed sets, then the Cayley graph
$\textrm {Cay}(\mathbb{Z}_n,S)$
has saturated spectrum with probability at least
$1-n^{-1/2+o(1)}$
.


Thus, Theorem1.1 for Cayley (di)graphs follows from Theorem2.3 in view of Lemma 2.1 and 2.2. Theorem2.3
 $-$
and hence, as already noted, also Theorem1.1
 $-$
extends to the other two models of a random circulant discussed in Section 1, namely, the random labelled and unlabelled circulants.
Theorem2.3 is our main technical contribution and may be of independent interest in the context of research on random circulant matrices [Reference Bose and Saha10, Reference Meckes34]. Moreover, this result has further noteworthy consequences for properties of random circulant graphs, which we discuss in the next subsection.
2.2 Compactness and naïve canonization
Note that two
 $n$
-vertex graphs
 $G$
and
 $H$
with adjacency matrices
 $A$
and
 $B$
, respectively, are isomorphic if and only if there is an
 $n\times n$
permutation matrix
 $P$
such that
 $AP=PB$
. This observation leads to a natural linear programming relaxation for the graph isomorphism problem. Recall that an
 $n\times n$
real matrix
 $S$
is doubly stochastic if its elements are nonnegative and all its rows and columns sum up to
 $1$
. A doubly stochastic matrix
 $S$
satisfying the equation
 $AS=SB$
is called a fractional isomorphism from
 $G$
to
 $H$
. In particular, if
 $AS=SA$
, then
 $S$
is a fractional automorphism of
 $G$
.
Tinhofer [Reference Tinhofer42] calls a graph
 $G$
compact if the polytope formed in
 $\mathbb{R}^{n^2}$
by the fractional automorphisms of
 $G$
is integral, that is, the extreme points of this polytope have integer coordinates. If a compact graph
 $G$
is isomorphic to another graph
 $H$
, then the polytope of fractional isomorphisms from
 $G$
to
 $H$
is also integral. On the other hand, this polytope contains no integral point at all if
 $G$
and
 $H$
are non-isomorphic. This has an algorithmic consequence. If we know that a graph
 $G$
is compact, then we can decide whether or not
 $G$
is isomorphic to any other given graph
 $H$
in polynomial time by using linear programming. It suffices to compute an extreme point of the polytope of fractional isomorphisms from
 $G$
to
 $H$
and check if it has integer coordinates.
While no efficient method is known in general for determining whether a graph
 $G$
is compact, Schreck and Tinhofer [Reference Schreck and Tinhofer41] established a sufficient condition for the compactness of circulant graphs. In our terminology, they showed that circulant graphs with saturated spectrum are compact. Consequently, Part 2 of our Theorem2.3 immediately implies the following result.
Corollary 2.4. Almost all circulant graphs are compact. More precisely, for all three notions of a circulant graph, if
 $X$
is a uniformly random circulant graph on
 $n$
vertices, then
 $X$
is compact with probability at least
 $1-n^{-1/2+o(1)}$
.
In [Reference Tinhofer43], Tinhofer presented another, fairly surprising combinatorial approach to testing whether two graphs are isomorphic provided one of them is compact. The approach can be recast as a canonization algorithm and was considered as such also by Immerman and Lander [Reference Immerman and Lander26]. Specifically, they consider the following algorithmic procedure.
NAïVE CANONIZATION
INPUT: a graph
 $X$
.
-
1. Set
$\widetilde X=X$
. -
2. Run colour refinement on
$\widetilde X$
and denote the resulting coloured graph by
$\widehat X$
. -
3. If the vertex colours in
$\widehat X$
are pairwise distinct, then output this colouring as a canonical labelling of
$X$
. -
4. Otherwise
-
(a) choose an arbitrary vertex
$v$
in the non-singleton colour class of
$\widehat X$
with leastFootnote
3
colour; -
(b) reset
$\widetilde X$
to be
$\widehat X$
with the vertex
$v$
individualized; -
(c) repeat Step 2 again.
-


We say that the above procedure works correctly on input
 $X$
if it produces a canonical labelling of
 $X$
irrespectively of which vertex
 $v$
is chosen in any execution of Step 4(a). Note that naïve canonization works correctly whenever it terminates after the first execution of Step 3, which occurs for almost all graphs
 $X$
by [Reference Babai, Erdős and Selkow5]. In the general case, when Step 4 is executed at least once, it is clear that a non-backtracking refinement-individualization procedure like this cannot be expected to be correct. Indeed, naïve canonization obviously fails on any regular but non-vertex-transitive graph
 $X$
. All the more surprising, then, is the result established in [Reference Tinhofer43] that the approach still works correctly on such a broad and naturally defined class of graphs as the class of compact graphs.
Combining this fact with Corollary 2.4, we obtain the following result.
Corollary 2.5. Naïve canonization works correctly for almost all circulant graphs. More precisely, this holds for all but a fraction of
 $n^{-1/2+o(1)}$
of circulant graphs on
 $n$
vertices, under any of the three models of circulant graphs.
Note that the class of graphs on which naïve canonization succeeds is strictly larger than the class of compact graphs; see [Reference Arvind, Köbler, Rattan and Verbitsky2]. This remains true also when we focus on circulant graphs. Indeed, Schreck and Tinhofer [Reference Schreck and Tinhofer41] proved that a non-empty and non-complete circulant graph with a prime number of vertices is compact if and only if it has saturated spectrum. Remarkably, Kluge [Reference Kluge29] showed that naïve canonization works correctly on every circulant graph with a prime number of vertices.
Finally, we remark that naïve canonization makes sense only if we are a priori confident in its correctness. Corollary 2.5 is quite constructive in this regard, as the sufficient condition of Schreck and Tinhofer [Reference Schreck and Tinhofer41] – having a saturated spectrum – is verifiable in polynomial time. Moreover, it can be shown by a direct argument that naïve canonization works correctly on every walk-saturated circulant graph.
2.3 Organization of the rest of the paper
The proof of our Main Theorem (Theorem1.1) spans Sections 3–6. Section 3 begins with preliminaries and then provides a detailed description of our canonical labelling algorithm for circulant graphs with saturated spectrum. Lemma 2.1 and 2.2 are proved in Section 4, as special cases of a more general result stated there as Lemma 4.1. Theorem2.3 is proved in Section 5. This establishes Theorem1.1 for Cayley (di)graphs over
 $\mathbb{Z}_n$
.
The proof of Theorem1.1 is completed in Section 6, which is devoted to the other two models of a random circulant. In this section, we establish two “transition” lemmas. Specifically, Lemma 6.4 allows us to extend the probability bound of Theorem2.3 from random Cayley (di)graphs to random unlabelled circulants, while Lemma 6.6 further extends this bound to random labelled circulants.
3. The walk matrix and colour refinement
3.1 Definitions and a relationship
Speaking of a directed graph or, for short, digraph
 $G=(V,E)$
, we always assume that
 $G$
is loopless, that is, the adjacency relation
 $E\subset V^2$
is irreflexive. Without loss of generality we suppose that
 $G$
is defined on the vertex set
 $V=\{0,1,\ldots ,n-1\}$
. If
 $E$
is symmetric,
 $G$
is referred to as an (undirected) graph. The definitions given below for digraphs apply, as a special case, also to graphs.
For
 $t\in V$
, we write
 $G_t$
to denote the digraph
 $G$
with distinguished vertex
 $t$
. The vertex
 $t$
is called terminal or individualized. We consider
 $G_t$
to be a vertex-coloured digraph where all vertices are equally coloured with the exception of
 $t$
which has a special colour. An isomorphism from
 $G_t$
to another vertex-individualized digraph
 $H_u$
is defined as a digraph isomorphism from
 $G$
to
 $H$
taking
 $t$
to
 $u$
.
A walk in
 $G$
is a sequence of vertices
 $x_0x_1\ldots x_k$
such that
 $(x_i,x_{i+1})\in E$
for every
 $0\le i\lt k$
. We say that
 $x_0x_1\ldots x_k$
is a walk of length
 $k$
from
 $x_0$
to
 $x_k$
. Note that a one-element sequence
 $x_0$
is a walk of length
 $0$
. Given a digraph
 $G_t$
with terminal vertex
 $t$
, we define its walk matrix
 $W_t=(w_{x,k})_{0\le x,k\lt n}$
by setting
 $w_{x,k}$
to be the number of walks of length
 $k$
from
 $x$
to
 $t$
. Let
 \begin{equation*} W_t(x)=(w_{x,0},w_{x,1},\ldots w_{x,n-1}) \end{equation*}
be the row of
 $W_t$
corresponding to the vertex
 $x$
. If
 $\phi$
is an isomorphism from
 $G_t$
to
 $H_u$
, then clearly
 $W_u(\phi (x))=W_t(x)$
. This means that
 $W_t(x)$
can be used as a canonical label for a vertex
 $x$
in
 $G_t$
. We call
 $G_t$
walk-discrete if
 $W_t(x)\ne W_t(x')$
for all
 $x\ne x'$
. Thus, the walk matrix yields a canonical labelling for the class of walk-discrete digraphs with an individualized vertex.
As it was mentioned in Section 2, the walk matrix is efficiently computable by linear algebraic operations. For walk-discrete digraphs, the corresponding canonical labelling can also be obtained combinatorially via the colour refinement algorithm (CR), which we now describe formally.
Given a vertex-coloured digraph
 $G$
with initial colouring
 $C_0$
, CR iteratively computes new colourings
 \begin{equation} C_{i+1}(x)={\left ( C_i(x),\{\!\{C_i(y)\}\!\}_{y\in N(x)} \right )}, \end{equation}
where
 $\{\!\{\ \}\!\}$
denotes a multiset and
 $N(x)=\{y\; :\; (x,y)\in E\}$
is the out-neighbourhood of
 $x$
. For each
 $i$
, the colouring
 $C_i$
is canonical, i.e., isomorphism-invariant. Indeed, an easy induction on
 $i$
shows that if
 $\phi$
is a (colour-preserving) isomorphism from
 $G$
to a vertex-coloured graph
 $H$
, then
 \begin{equation} C_i(\phi (x))=C_i(x). \end{equation}
The colour classes of
 $C_{i+1}$
refine the colour classes of
 $C_i$
: if
 $C_i(x)\ne C_i(x')$
, then
 $C_{i+1}(x)\ne C_{i+1}(x')$
. The algorithm terminates after performing
 $n$
refinement rounds, where
 $n$
is the number of vertices in
 $G$
, and outputs the colouring
 $C_n$
. Note that the colour partition becomes stable by this point.
A relationship between CR and the walk counts was observed in [Reference Powers and Sulaiman39]. We use the following adaptation of this result for our purposes.
Lemma 3.1. Let
 $t\in V(G)$
and
 $C_0$
be the vertex colouring associated with
 $G_t$
, that is,
 $C_0(x)=C_0(x')$
and
 $C_0(x)\ne C_0(t)$
for all
 $x\ne t$
and
 $x'\ne t$
. If
 $w_{x,k}\ne w_{x',k}$
, then
 $C_k(x)\ne C_k(x')$
.
Proof. Using the induction on
 $k$
, we prove that
 $w_{x,k}=w_{x',k}$
whenever
 $C_k(x)=C_k(x')$
. In the base case of
 $k=0$
, the equalities
 $w_{x,0}=w_{x',0}$
and
 $C_0(x)=C_0(x')$
are equivalent by definition. Assume that
 $C_k(y)=C_k(y')$
implies
 $w_{y,k}=w_{y',k}$
for all
 $y$
and
 $y'$
. Let
 $C_{k+1}(x)=C_{k+1}(x')$
. By the definition of the refinement step, we have
 $\{\!\{C_k(y)\}\!\}_{y\in N(x)}=\{\!\{C_k(y)\}\!\}_{y\in N(x')}$
. Using the induction assumption, from here we derive the equality
 $\{\!\{w_{y,k}\}\!\}_{y\in N(x)}=\{\!\{w_{y,k}\}\!\}_{y\in N(x')}$
. The equality
 $w_{x,k+1}=w_{x',k+1}$
now follows by noting that
 $w_{x,k+1}=\sum _{y\in N(x)}w_{y,k}$
.
Lemma 3.1 shows that a canonical labelling of a walk-discrete digraph
 $G_t$
can be obtained by running CR on
 $G_t$
rather than by directly computing the walk matrix, and we conclude this subsection by commenting on the efficiency of CR.
The inductive definition (1) leads to an exponential increase in the size of the colour encoding. To prevent this, colours are renamed after each refinement step. In this way, we never need more than
 $n$
distinct colour names. To encode the colours after each refinement round, we can use, for example, the first
 $n$
non-negative integers in binary. This allows us, in the next subsection, to refer to the least colour having a certain property. Note that, once the renaming rule is fixed, the modified colouring remains canonical in the sense of Equality (2).
Finally, recall that CR can be implemented in time
 $O(n^2\log n)$
[Reference Berkholz, Bonsma and Grohe7, Reference Cardon and Crochemore12, Reference Immerman and Lander26], while preserving the canonicity of the final colouring with respect to graph isomorphism; see [Reference Berkholz, Bonsma and Grohe7].
3.2 Cayley graphs of a cyclic group
Let
 $\mathbb{Z}_n$
denote a cyclic group of order
 $n$
. More specifically, we let
 $\mathbb{Z}_n=\{0,1,\ldots ,n-1\}$
and consider the addition modulo
 $n$
on this set. The Cayley digraph
 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
is defined by a connection set
 $S\subseteq \mathbb{Z}_n\setminus \{0\}$
as follows:
 $V(X)=\mathbb{Z}_n$
and
 $(x,y)\in E(X)$
if and only if
 $y-x\in S$
. Note that
 $S=N(0)$
, the out-neighbourhood of
 $0$
. If
 $S$
is inverse-closed, i.e.,
 $S=-S$
, then
 $E(X)$
is symmetric and we speak of a Cayley graph. Cayley (di)graphs of
 $\mathbb{Z}_n$
are also called circulant (di)graphs or circulants.
For
 $u\in \mathbb{Z}_n$
, let
 $X_u$
be the vertex-individualized version of
 $X$
. Since
 $X$
is vertex-transitive, all
 $X_u$
are isomorphic to each other, and we can speak about
 $X_0$
without loss of generality. Clearly, in order to canonize
 $X$
, it is sufficient to canonize
 $X_0$
. Therefore, the canonization method in the preceding subsection applies to any Cayley digraph
 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
provided that
 $X_0$
is walk-discrete. We just have to individualize an arbitrary vertex of
 $X$
and then run CR.
This method does not work for circulant graphs. Indeed, define
 $\rho :\mathbb{Z}_n \rightarrow \mathbb{Z}_n$
by
 $\rho (x)=-x$
. If
 $S=-S$
, then
 $\rho$
is an automorphism of
 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
and, hence,
 $W_0(\rho (x))=W_0(x)$
. This implies that the walk matrix
 $W_0$
has at most
 $\lceil (n+1)/2\rceil$
different rows, and
 $X_0$
cannot be walk-discrete. If this maximum is attained, we call
 $X_0$
walk-saturated.
Lemma 3.2. Let
 $X = {\textrm{Cay}}(\mathbb{Z}_n,S)$
, where
 $S=-S$
, and suppose that
 $X_0$
is walk-saturated. Fix
 $u\ne 0$
such that
 $u\ne n/2$
if
 $n$
is even. Then
 \begin{equation*} (W_0(x),W_u(x))\ne (W_0(y),W_u(y)) \end{equation*}
for any two different vertices
 $x$
and
 $y$
of
 $X$
.
Proof. Since
 $X_0$
is walk-saturated, the equality
 $W_0(x)=W_0(y)$
for
 $x\ne y$
is possible only if
 $y=\rho (x)$
, i.e.,
 $y=-x$
in
 $\mathbb{Z}_n$
. Note that
 $W_u(x)=W_0(x-u)$
. Therefore, the equality
 $W_u(x)=W_u(y)$
implies that
 $y=2u-x$
. The equalities
 $y=-x$
and
 $y=2u-x$
can be fulfilled simultaneously only if
 $2u=0$
, which is excluded.
Lemma 3.2 justifies the correctness of the following algorithm for the class of walk-saturated circulant graphs.
CANONICAL LABELLING ALGORITHM
INPUT: a circulant graph
 $X$
.
-
1. Individualize an arbitrary vertex of
$X$
. By vertex-transitivity, we can without loss of generality assume that the individualized vertex is
$0$
. -
2. Run CR on
$X_0$
. Let
$C$
be the obtained colouring of the vertex set. -
3. Let
$c$
be the least colour such that there are exactly two vertices
$u_1$
and
$u_2$
with
$C(u_1)=C(u_2)=c$
. If such
$c$
does not exist, then give up. Let
$u$
be any of
$u_1$
and
$u_2$
. Individualize
$u$
in
$X$
. -
4. Run CR on
$X_u$
. Let
$C'$
be the obtained colouring. -
5. To each vertex
$x$
, assign the label
$L(x)=(C(x),C'(x))$
. -
6. Check that all labels
$L(x)$
are pairwise distinct. If not, then give up.


For each circulant input graph, our canonization algorithm either produces a vertex labelling
 $L$
or explicitly gives up (doing always the same for isomorphic inputs). The labelling
 $L$
is canonical because it does not depend on which vertex is individualized in Step 1 (by vertex-transitivity) nor in Step 3 (because
 $u_1$
and
 $u_2$
are interchangeable by an automorphism of
 $X_0$
). Lemma 3.2 ensures that the algorithm succeeds whenever
 $X_0$
is walk-saturated, and this will allow us to estimate the success probability based on Lemma 2.2 and Theorem2.3.
Finally, we remark that if the algorithm is run on a non-circulant input graph and outputs a vertex labelling, then this labelling does not need to be canonical. To make it canonical in all cases, Steps 1 and 3 have to be performed for all possible individualized vertices, which can yield
 $2n$
different labellings
 $L_1,\ldots ,L_{2n}$
. Of all these candidate labellings, the algorithm chooses that which yields the isomorphic copy of
 $X$
with lexicographically least adjacency matrix. The running time of this algorithm variant is
 $O(n^3\log n)$
. The similar modification is as well possible in the case of digraphs.
4. The walk matrix and the spectrum of circulants
4.1 The spectrum of a circulant
Let
 $A=(a_{ij})$
be the adjacency matrix of a circulant digraph
 $X$
, that is,
 $A$
is the 0–1 matrix whose rows and columns are indexed by the elements
 $0,1,\ldots ,n-1$
of
 $\mathbb{Z}_n$
such that
 $a_{ij}=1$
exactly when
 $(i,j)\in E(X)$
, that is,
 $j-i\in S$
. Note that
 $A$
is a circulant matrix, which means that the
 $(i+1)$
-th row of
 $A$
is obtained from its
 $i$
-th row by the cyclic shift in one element to the right.
Let
 $\omega$
be an
 $n$
-th root of unity, i.e.,
 $\omega \in \mathbb{C}$
and
 $\omega ^n=1$
. For the vector
 $V_\omega =(1,\omega ,\omega ^2,\ldots ,\omega ^{n-1})^\top$
, the definition of a circulant matrix easily implies the equality
 \begin{equation*} {A}{V}_\omega ={\left ( a_0+a_1\omega +a_2\omega ^2+\cdots +a_{n-1}\omega ^{n-1} \right )}\,V_\omega ={\left ( \sum _{j\in S}\omega ^j \right )}V_\omega , \end{equation*}
where
 $(a_0,a_1,a_2,\ldots ,a_{n-1})$
is the first row of
 $A$
, that is, the characteristic vector of
 $S\subset \mathbb{Z}_n$
. We conclude that
 $V_\omega$
is an eigenvector of
 $A$
corresponding to the eigenvalue
 $\lambda _{\omega ,S}=\sum _{j\in S}\omega ^j$
.
Now, let
 $\omega =\zeta _n$
be a primitive
 $n$
-th root of unity. To be specific, we fix
 $\zeta _n=e^{-2\pi \textrm{i}/n}$
. The
 $n$
column vectors
 $V_\omega$
for
 $\omega =\zeta _n^0,\zeta _n^1,\zeta _n^2,\ldots ,\zeta _n^{n-1}$
form a Vandermonde matrix with non-zero determinant. It follows that these
 $n$
vectors are linearly independent and, therefore,
 $\lambda _{\zeta _n^0,S},\lambda _{\zeta _n^1,S},\ldots ,\lambda _{\zeta _n^{n-1},S}$
is the full spectrum of
 $A$
. The
 $i$
-th eigenvalue in this sequence will be below denoted by
 \begin{equation} \lambda _{i,S}=\sum _{j\in S}\zeta _n^{ij}. \end{equation}
4.2 Discrete Fourier transform
Let
 $\mathbb{C}^{\mathbb{Z}_n}$
denote the vector space of all functions from
 $\mathbb{Z}_n$
to the field of complex numbers
 $\mathbb{C}$
with pointwise addition and pointwise scalar multiplication. The pointwise multiplication on
 $\mathbb{C}^{\mathbb{Z}_n}$
will be denoted by
 $\circ$
. Another way to introduce a product on
 $\mathbb{C}^{\mathbb{Z}_n}$
is to consider the convolution
 $\alpha *\beta$
of two functions
 $\alpha ,\beta :\mathbb{Z}_n \rightarrow \mathbb{C}$
, which is defined by
 $(\alpha *\beta )(x)=\sum _{y\in {\mathbb{Z}_n}}\alpha (x-y)\beta (y)$
for each
 $x\in {\mathbb{Z}_n}$
. Both
 $\circ$
and
 $*$
are bilinear and, therefore, both
 $(\mathbb{C}^{\mathbb{Z}_n},\circ )$
and
 $(\mathbb{C}^{\mathbb{Z}_n},*)$
are
 $n$
-dimensional algebras over
 $\mathbb{C}$
. The algebra
 $(\mathbb{C}^{\mathbb{Z}_n},*)$
can alternatively be seen as the group algebra of
 $\mathbb{Z}_n$
over
 $\mathbb{C}$
and, as such, it is semisimple by Maschke’s theorem; see, e.g., [Reference Drozd and Kirichenko17, Section 7.1]. Like any two
 $n$
-dimensional commutative semisimple
 $\mathbb{C}$
-algebras, the algebras
 $(\mathbb{C}^{\mathbb{Z}_n},*)$
and
 $(\mathbb{C}^{\mathbb{Z}_n},\circ )$
are isomorphic (see [Reference Drozd and Kirichenko17, Corollary 2.4.2]). We now describe an explicit algebra isomorphism from
 $(\mathbb{C}^{\mathbb{Z}_n},*)$
to
 $(\mathbb{C}^{\mathbb{Z}_n},\circ )$
.
For
 $T\subseteq {\mathbb{Z}_n}$
, let
 $\chi _T\in \mathbb{C}^{\mathbb{Z}_n}$
be the characteristic function of
 $T$
. In particular,
 $\chi _{\mathbb{Z}_n}$
is the identically one function. For
 $x\in {\mathbb{Z}_n}$
, we set
 $\delta _x=\chi _{\{x\}}$
.
The discrete Fourier transform (DFT) is the linear operator
 $\mathcal{F} \, : \, \mathbb{C}^{\mathbb{Z}_n} \rightarrow \mathbb{C}^{\mathbb{Z}_n}$
mapping a function
 $\alpha :\mathbb{Z}_n \rightarrow \mathbb{C}$
into the function
 $\mathcal{F}(\alpha ):\mathbb{Z}_n \rightarrow \mathbb{C}$
defined by
 \begin{equation} \mathcal{F}(\alpha )(i)=\sum _{j=0}^{n-1}\zeta _n^{ij}\alpha (j). \end{equation}
In the standard basis
 $\delta _0,\delta _1,\ldots ,\delta _{n-1}$
, the DFT is represented by the matrix
 $F=(\zeta _n^{ij})_{i,j\in \mathbb{Z}_n}$
. Since
 $F$
is the familiar Vandermonde matrix with non-zero determinant, the map
 $F$
is a linear isomorphism from
 $\mathbb{C}^{\mathbb{Z}_n}$
onto itself. It is well known and easy to derive from the definitions that
 \begin{equation} \mathcal{F}(\alpha *\beta )=\mathcal{F}(\alpha )\circ \mathcal{F}(\beta ). \end{equation}
4.3 The rank of the walk matrix
We are now prepared to derive Lemma 2.1 and 2.2 from the following more general fact.
Lemma 4.1.
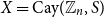 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
has exactly
 ${rk} W_0$
distinct eigenvalues, where
 $W_0$
is the walk matrix of
 $X_0$
.
Proof. Let
 $X'=\textrm {Cay}(\mathbb{Z}_n,-S)$
be the transpose of the digraph
 $X$
, i.e., the digraph obtained from
 $X$
by reversing all arcs. Note that the adjacency matrices of
 $X$
and
 $X'$
are transposes of each other and therefore have the same spectrum. Denote the number of distinct eigenvalues of
 $X'$
, and hence also of
 $X$
, by
 $R$
.
A column vector
 $(a_0,a_1,\ldots ,a_{n-1})^\top$
will be naturally identified with the function
 $\alpha \in \mathbb{C}^{\mathbb{Z}_n}$
defined by
 $\alpha (x)=a_x$
for all
 $x\in \mathbb{Z}_n$
. In this way, the columns of the walk matrix
 $W_0$
correspond to the functions
 $\eta _0,\eta _1,\ldots ,\eta _{n-1}$
where
 $\eta _k(x)=w_{x,k}$
. Thus, the rank of
 $W_0$
is equal to the dimension of the linear subspace
 $U$
of
 $\mathbb{C}^{\mathbb{Z}_n}$
spanned by these functions. We, therefore, have to prove that
 $\dim U=R$
.
Note that
 \begin{align*} \eta _{k+1}(x)&=\sum _{y\in N(x)}\eta _k(y)=\sum _{y\in \mathbb{Z}_n}\chi _S(y-x)\eta _k(y)\\ &=\sum _{y\in \mathbb{Z}_n}\chi _{-S}(x-y)\eta _k(y)=(\chi _{-S}*\eta _k)(x). \end{align*}
It follows that
 $\eta _0=\delta _0$
,
 $\eta _1=\chi _{-S}$
,
 $\eta _2=\chi _{-S}*\chi _{-S}$
and, generally,
 $\eta _k=\chi _{-S}^{*(k)}$
is the
 $(k-1)$
-fold convolution of
 $k$
copies of the characteristic function
 $\chi _{-S}$
of the set
 $-S$
.
Let us apply the DFT
 $\mathcal{F}$
. Note that
 $\mathcal{F}(\delta _0)$
is the all-ones vector. As easily seen from (3) and (4),
 $\mathcal{F}(\chi _{-S})$
is the vector whose entries are the eigenvalues
 $\lambda _{0,-S},\lambda _{1,-S},\ldots ,\lambda _{n-1,-S}$
of the transpose
 $X'=\textrm {Cay}(\mathbb{Z}_n,-S)$
. Equality (5) readily implies that the matrix formed by the column vectors
 $\mathcal{F}(\eta _0),\mathcal{F}(\eta _1),\ldots ,\mathcal{F}(\eta _{n-1})$
has exactly
 $R$
distinct rows. Consequently,
 $\dim U=\dim \mathcal{F}(U)\le R$
. In fact, equality holds because the aforementioned matrix contains a non-degenerate Vandermonde matrix of size
 $R\times R$
as a submatrix.
Lemma 2.1 and 2.2 correspond, respectively, to the special cases
 $\textrm {rk} W_0=n$
and
 $\textrm {rk} W_0=\lceil (n+1)/2\rceil$
of Lemma 4.1. If
 $S=-S$
, then
 $\textrm {rk} W_0\le \lceil (n+1)/2\rceil$
due to the symmetry of the undirected graph
 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
. Lemma 4.1 shows that
 $X$
can have at most
 $\lceil (n+1)/2\rceil$
distinct eigenvales,Footnote
4
and that this maximum is attained exactly when
 $\textrm {rk} W_0$
attains the same maximum value
 $\lceil (n+1)/2\rceil$
.
5. Proof of Theorem2.3
We set
 $\zeta _n=e^{-2\pi \textrm{i}/n}$
. As discussed in Section 4.1, a circulant
 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
has eigenvalues
 $\lambda _0,\lambda _1,\ldots ,\lambda _{n-1}$
where
 \begin{equation*} \lambda _a=\sum _{j\in S}\zeta _n^{aj}=\sum _{j=0}^{n-1}\chi _S(j)\zeta _n^{aj}. \end{equation*}
Let
 $\sigma _j=\chi _S(j)$
. If
 $X$
is a random digraph, i.e., the connection set
 $S$
is chosen uniformly at random among all subsets of
 $\mathbb{Z}_n \! \setminus \! \{0\}$
, then
 $\sigma _1,\sigma _2,\ldots ,\sigma _{n-1}$
is a Bernoulli process, that is, these
 $n-1$
random variables are independent and identically distributed with
 $\sigma _j$
taking each of the values 0 and 1 with probability
 $1/2$
. If
 $X$
is a random graph, i.e., the connection set
 $S=-S$
is chosen randomly among all inverse-closed subsets, then the values
 $\sigma _1,\sigma _2,\ldots ,\sigma _{\lfloor n/2\rfloor }$
form a Bernoulli process, and the remaining values are determined by the equality
 $\sigma _j=\sigma _{n-j}$
. For each
 $a=0,1,\ldots ,n-1$
, the eigenvalue
 \begin{equation} \lambda _a=\sum _{j=1}^{n-1}\sigma _j\zeta _n^{aj} \end{equation}
becomes a random variable taking its values in the cyclotomic field
 $\mathbb{Q}(\zeta _n)$
.
We will use the following observation. As usually,
 $\phi (n)$
stands for Euler’s totient function.
Lemma 5.1. No two different subsets of
 $\{\zeta _n^j\; :\; 1\leq j\leq n/\ln n\}$
have equal sums of their elements.
Proof. The known lower bounds for
 $\phi (n)$
(see, e.g., [Reference Bach and Shallit6, Theorem 8.8.7]) imply that
 $\phi (n) \gt n/\ln n$
for
 $n\ge 3$
. The existence of two different subsets with equal sums would therefore yield a non-trivial linear combinations with rational coefficient of
 $1,\zeta _n,\zeta _n^2,\ldots ,\zeta _n^{\phi (n)-1}$
, contradicting the fact that these numbers form a basis of
 $\mathbb{Q}(\zeta _n)$
considered as a vector space over
 $\mathbb{Q}$
.
Our overall strategy for proving Theorem2.3 will be to use the union bound
 \begin{equation} \mathbb{P}[ \lambda _a=\lambda _b\text{ for some }0\le a,b\le n-1 ]\le \sum _{0\le a,b\le n-1}\mathbb{P}[ \lambda _a=\lambda _b ] \end{equation}
and to show that the right-hand side is bounded by
 $n^{-1/2+o(1)}$
. The summation ranges over unequal
 $a$
and
 $b$
; in the undirected case, we additionally require
 $a+b\ne n$
. For a fixed pair
 $\{a,b\}$
, we have to show that
 $\lambda _a=\lambda _b$
occurs with sufficiently small probability. Using (6), this equality can be rewritten as
 \begin{equation} \sum _{j=1}^{n-1}\sigma _j\zeta _n^{aj}=\sum _{j=1}^{n-1}\sigma _j\zeta _n^{bj} \end{equation}
The basic idea is to “distil” a sufficiently large set of indices
 $J\subset \{1,\ldots ,n-1\}$
such that exposing all random variables
 $\sigma _j$
for
 $j\notin J$
converts (8) into an equality
 \begin{equation} \sum _{j\in J}\sigma _j\zeta _n^{aj}=\sum _{j\in J}\sigma _j\zeta _n^{bj}+\textrm{const} \end{equation}
that can be satisfied by at most one assignment to the remaining random variables
 $\sigma _j$
for
 $j\in J$
. The last condition immediately implies the bound
 $\mathbb{P}[ \lambda _a=\lambda _b ]=2^{-|J|}$
, which will be strong enough for our purposes. To justify that (9) has at most one satisfying assignment, we will crucially rely on Lemma 5.1.
Let
 \begin{equation*} \mathbb{U}=\{z\in \mathbb{C}\; :\; |z|=1\} \end{equation*}
denote the unit circle in the complex plane. Lemma 5.1 will be applicable not only when
 $aj$
and
 $bj$
(modulo
 $n$
) do not exceed
 $n/\ln n$
for all
 $j\in J$
– which would be technically difficult to ensure – but also whenever the set
 $\{\zeta _n^{aj}\}_{j\in J}\cup \{\zeta _n^{bj}\}_{j\in J}$
is contained within an arbitrary arc of
 $\mathbb{U}$
of length
 $2\pi /\ln n$
. In such cases, we can “rotate” this set by multiplying both sides of (9) by a suitable root of unity
 $\zeta _n^t$
. This will transform (9) into a linear combination of the complex numbers
 $\zeta _n^{aj+t}$
and
 $\zeta _n^{bj+t}$
with exponents (modulo
 $n$
) lying in the range covered by Lemma 5.1.
The choice of a suitable set
 $J$
depends on specific properties of the pair
 $\{a,b\}$
. We divide all such pairs into three categories and describe an appropriate “distillation” of
 $J$
separately for each of the three cases. The relevant properties of a pair
 $\{a,b\}$
are expressed in terms of elementary number-theoretic parameters, which we now introduce.
Given
 $z\in \mathbb{C}^\times$
, we write
 $\langle z\rangle$
to denote the cyclic subgroup of the multiplicative group
 $\mathbb{C}^\times$
generated by
 $z$
. For an integer
 $c$
, let
 $g(c)=|\langle \zeta _n^c\rangle |$
denote the order of the element
 $\zeta _n^c$
in the group
 $\langle \zeta _n\rangle$
. Note that
 $g(c)=n/\gcd (c,n)$
. We also define
 \begin{equation*} c'=c/ \! \gcd (c,n), \end{equation*}
noting that
 \begin{equation} \zeta _n^{c}=\zeta _{g(c)}^{c'}. \end{equation}
The above notation will be used both for
 $c=a$
and
 $c=b$
. We set
 \begin{equation*} g=g(a)\text{ and }h=g(b), \end{equation*}
and suppose, without loss of generality, that
 \begin{equation*} h\le g. \end{equation*}
Since
 $\gcd (a',g)=1$
, the integer
 $a'$
can be regarded as an invertible element of the ring
 $\mathbb{Z}_g$
. Let
 $r$
denote the inverse of
 $a'$
in
 $\mathbb{Z}_g$
, i.e.,
 $r$
is the smallest positive integer for which
 $ra'=1\pmod g$
.
Note that
 $\langle \zeta _n^a\rangle =\langle \zeta _g\rangle$
. Indeed,
 $\zeta _n^a\in \langle \zeta _g\rangle$
by (10). On the other hand, (10) also implies that
 $\zeta _g=\zeta _g^{ra'}=\zeta _n^{ar}$
belongs to
 $\langle \zeta _n^a\rangle$
. Set
 \begin{equation} \xi =\zeta _g=\zeta _n^{ar}\text{ and }\eta =\zeta _n^{br}. \end{equation}
Thus, all
 $g-1$
non-unity elements of the multiplicative group
 $\langle \zeta _n^a\rangle =\langle \xi \rangle$
can be listed as
 \begin{equation} \xi =\zeta _n^{ar},\ \xi ^2=\zeta _n^{2ar},\ \ldots \ ,\xi ^{g-1}=\zeta _n^{(g-1)ar}. \end{equation}
It is useful to note that they appear in the left-hand side of Equality (8) for the indices
 $j=r,2r,\ldots ,(g-1)r$
, which are understood modulo
 $n$
. The same positions in the right-hand side of Equality (8) are occupied by
 \begin{equation} \eta =\zeta _n^{br},\ \eta ^2=\zeta _n^{2br},\ \ldots \ ,\eta ^{g-1}=\zeta _n^{(g-1)br}. \end{equation}
The importance of the parameter
 $g$
stems from the fact that the elements of (12), together with the unity
 $\xi ^{g}=1$
, partition the unit circle
 $\mathbb{U}$
into
 $g$
arcs, each of length
 $2\pi /g$
. When
 $g$
is large, this gives us better chances to obtain a linear combination (9) such that the degrees
 $\zeta _n^{aj}$
involved in (9) are sufficiently close to one another on
 $\mathbb{U}$
, allowing us to apply Lemma 5.1 as described above.
The minimum distance in
 $\mathbb{U}$
between two distinct elements
 $\zeta _n^{brk_1}=\eta ^{k_1}$
and
 $\zeta _n^{brk_2}=\eta ^{k_2}$
is important by the same reason. This distance is equal to
 $2\pi /g'$
where
 \begin{equation*} g'=|\langle \eta \rangle | \end{equation*}
is the order of the element
 $\eta$
in
 $\langle \zeta _n\rangle$
. Since
 $\langle \eta \rangle \subseteq \langle \zeta _n^b\rangle$
, we have
 \begin{equation*} g'\le h\le g. \end{equation*}
While all numbers in (12) are distinct, the number of distinct numbers in the sequence (13) is equal to
 $g'$
if
 $g'\lt g$
and to
 $g'-1$
if
 $g'=g$
.
The parameters
 $g$
and
 $g'$
are crucial for our analysis, and we partition all pairs
 $\{a,b\}$
into three groups based on the values of
 $g$
and
 $g'$
. Recall that we assume
 $g(b)\le g(a)$
. In cases where
 $g(b)=g(a)$
, we will further assume that
 $b\lt a$
. This additional assumption does not play any substantive role in the analysis but allows us to treat
 $a,b$
as an ordered pair.
We now outline our argument for each of the three cases – Cases A, B, and C – described below. After presenting the main ideas, we will proceed to a detailed proof, organized into Claims A, B, and C, respectively. Note that Case C is responsible for the probability bound
 $n^{-1/2+o(1)}$
in Theorem2.3, as the estimates for the probability of multiple eigenvalues obtained in Cases A and B are stronger. We define Case C by assuming that the parameter
 $g$
is relatively small in terms of
 $n$
. Notably, this restriction simplifies the analysis, because both sides of Equality (8) can be viewed as linear combinations of a few independent binomial variables. We begin the outline with the most technically demanding case.
Case A:
$g$
and
$g'$
are large


This case is further divided into three subcases. In the first two of them, we can find a sufficiently large set
 $K\subseteq \{1,\ldots ,n-1\}$
, specifically of size
 $|K|=\Omega (\ln ^2n)$
, such that:
-
(i) the subsequence
$(\xi ^k)_{k\in K}$
of the sequence (12) consists of distinct elements, and the same holds true for the corresponding subsequence
$(\eta ^k)_{k\in K}$
of (13); -
(ii) the sets
$\{\xi ^k\}_{k\in K}$
and
$\{\eta ^k\}_{k\in K}$
are disjoint; -
(iii) both sets are contained within a sufficiently short arc of
$\mathbb{U}$
, specifically of length less than
$1/ \! \ln n$
.


We now argue that properties (i)–(iii) allow us to bound the probability of (8) based on Lemma 5.1.
Let us expose the values of all random variables
 $\sigma _j$
excepting
 $\sigma _{kr}$
with
 $k\in K$
(recall that the indices are considered modulo
 $n$
). Equality (8) can now be written as
 \begin{equation} c_1+\sum _{k\in K}\sigma _{kr}\xi ^k=c_2+\sum _{k\in K}\sigma _{kr}\eta ^k \end{equation}
for some constants
 $c_1,c_2\in \mathbb{C}$
. In other words, we estimate the probability of the event that
 \begin{equation} c_1+\sum _{k\in K'}\xi ^k=c_2+\sum _{k\in K'}\eta ^k \end{equation}
for a random subset
 $K'\subseteq K$
. We show that this equality can be true for at most one
 $K'$
.
Indeed, assume that Equality (15) holds true for two different subsets
 $K'=K_1$
and
 $K'=K_2$
of
 $K$
. This implies that
 $\sum _{k\in K'}(\xi ^k-\eta ^k)=c_2-c_1$
for both
 $K'=K_1$
and
 $K'=K_2$
and, therefore,
 \begin{equation} \sum _{k\in K_1}\xi ^k+\sum _{k\in K_2}\eta ^k=\sum _{k\in K_2}\xi ^k+\sum _{k\in K_1}\eta ^k. \end{equation}
By Conditions (i)–(ii), both sides of (16) are sums of
 $|K_1|+|K_2|$
distinct numbers. Since
 $K_1\ne K_2$
, we can without loss of generality suppose that
 $K_1\not \subseteq K_2$
. Taking
 $k\in K_1 \! \setminus \! K_2$
, we see that the number
 $\xi ^k$
occurs only in the left-hand side of (16). Thus, we have equality of two sums of
 $\zeta _n^j$
over different sets of indices
 $j$
. By multiplying both sides of Equation (16) by a suitable
 $\zeta _n^t$
, and using Condition (iii), we can “rotate” these index sets modulo
 $n$
so that they lie within the interval
 $[1,n/\ln n]$
. This leads to a contradiction with Lemma 5.1.
We conclude that Equality (15), and therefore also Equality (8), holds with probability at most
 $2^{-|K|}=n^{-\Omega (\ln n)}$
.
The third subcase of Case A, which relies on the same idea and is somewhat simpler, is omitted from this outline (it appears as Case 3 in the proof of Claim 1 below).
Case B:
$g$
is large, and
$g'$
is small


Since
 $\xi =\zeta _g=e^{-2\pi \textrm{i}/g}$
, the first
 $m$
elements of the sequence (12) are contained in an arc of
 $\mathbb{U}$
of length
 $2\pi m/g$
. The corresponding elements of the sequence (13) can take on at most
 $g'$
different values. Therefore, there is a set
 $K\subseteq \{1,\ldots ,m\}$
of size
 \begin{equation*} |K|\ge m/g' \end{equation*}
such that if
 $k\in K$
, then
 $\eta ^k=\eta '$
for the same
 $\eta '$
. Expose all
 $\sigma _j$
excepting
 $\sigma _{kr}$
for
 $k\in K$
. Similarly to Case A, Equality (8) converts into Equality (14) for some constants
 $c_1$
and
 $c_2$
. This event can be recast as
 \begin{equation} c_1+\sum _{k\in K'}\xi ^k=c_2+|K'|\eta ' \end{equation}
for a random subset
 $K'\subseteq K$
. By Chernoff’s bound, the size of
 $K'$
is concentrated in the interval
 $\frac 12|K|-|K|^{2/3}\lt |K'|\lt \frac 12|K|+|K|^{2/3}$
with probability no less than
 $1-2\exp ({-}|K|^{1/3})$
. Fix an integer
 $m'$
such that
 $\frac 12|K|-|K|^{2/3}\lt m'\lt \frac 12|K|+|K|^{2/3}$
and consider the event (17) conditioned on
 $|K'|=m'$
. Under this condition, Equality (17) reads
 \begin{equation} \sum _{k\in K'}\xi ^k=c_2+m'\eta '-c_1. \end{equation}
We choose
 $m$
such that
 \begin{equation} 2\pi m/g\lt 1/\ln n \end{equation}
while
 $m/g'$
, and hence
 $|K|$
, is large. Condition (19) ensures that Lemma 5.1 applies, implying that Equality (18) holds for at most one subset
 $K'\subseteq K$
. It follows that this equality holds with probability at most
 $1/\binom{|K|}{m'}$
. We therefore conclude that Equality (8) holds with probability at most
 \begin{equation} 1/\binom{|K|}{|K|/2+|K|^{2/3}}+2\exp {\left ( -|K|^{1/3} \right )}. \end{equation}
The specification of “large”
 $g$
and “small”
 $g'$
in the formal argument below ensures that this probability is subexponentially small.
Case C:
$g$
is small

This case can be treated without invoking Lemma 5.1. Let
 $J=\{j\lt n\; :\; \zeta _n^{aj}=\xi \}$
, and note that
 $|J|=n/g$
. The set
 $J$
contains a subset
 $J'$
of size
 $|J'|\ge |J|/h\ge n/g^2$
such that the values
 $\zeta _n^{bj}$
are all equal for
 $j\in J'$
. That is, for all
 $j\in J'$
, we have
 $\zeta _n^{aj}=\xi$
and
 $\zeta _n^{bj}=\eta '$
where
 $\eta '$
is the same
 $h$
-th root of unity. Moreover,
 $J'\subseteq J$
can be chosen so that
 $\xi \ne \eta '$
; see the proof of Claim 3 below for details.
Let us expose all random variables
 $\sigma _j$
except those for
 $j\in J'$
. Equality (8) then implies that
 \begin{equation*} \sum _{j\in J'}\sigma _j(\xi -\eta ')=c \end{equation*}
for a constant
 $c\in \mathbb{C}$
and, therefore, the sum
 $\sum _{j\in J'}\sigma _j$
evaluates to a constant value. The probability of the last event is bounded by
 $\binom{|J'|}{\lfloor |J'|/2\rfloor}2^{-|J'|} \le |J'|^{-1/2} \le gn^{-1/2}$
. Although this bound is weaker than those obtained in Cases A and B, it is still sufficient for use with the union bound (7) because, as we will see, the number of pairs
 $a,b$
covered by Case C is relatively small.
After this outline, we proceed to the detailed proof. We begin by noting that the numbers
 $\xi$
and
 $\eta$
, defined by (11), are distinct. Indeed, the equality
 $\xi =\eta$
would imply that
 $\langle \zeta _n^b\rangle$
contains
 $\langle \eta \rangle =\langle \xi \rangle =\langle \zeta _n^a\rangle$
, showing that
 $h\ge g$
and, hence,
 $h=g$
in this case. By (10), the last equality leads to
 \begin{equation*} \zeta _g^{a'r}=\zeta _n^{ar}=\zeta _n^{br}=\zeta _h^{b'r}=\zeta _g^{b'r}, \end{equation*}
which holds only if
 $r(a'-b')$
is divisible by
 $g$
. Since
 $r$
and
 $g$
are coprime, we conclude that
 $a'-b'$
must be divisible by
 $g$
. Since
 $a'$
and
 $b'$
are strictly smaller than
 $g$
, this is possible only when
 $a'=b'$
, contradicting the assumption that
 $a\ne b$
.
Let
 $\varepsilon \gt 0$
be an arbitrarily small constant. Once this parameter is fixed, we assume that
 $n$
is sufficiently large. We divide the remainder of the proof into Claims 1–3, corresponding to Cases A, B, and C discussed above. We present a detailed argument for digraphs (Part 1 of the theorem), which, with minor modifications, also applies to graphs (Part 2). We comment on these modifications at the end of the proof.
For the argument
 $\arg (z)$
of a complex number
 $z$
, we suppose that
 $\arg (z)\in [0,2\pi )$
.
Claim 1. Let
 $P_1=\{(a,b)\; :\; {g\geq n^{6\varepsilon }\text{ and }g'\geq n^{\varepsilon }}\}$
. Then
 \begin{equation*} \sum _{(a,b)\in P_1}\mathbb{P}[ \lambda _a=\lambda _b ] \le n^{-0.5\ln n}. \end{equation*}
Proof. We claim that there exists
 $s$
such that
 \begin{equation} 1\leq s\leq \lceil \ln ^4n\rceil \end{equation}
and
 \begin{equation*} \text{either }0\lt \arg (\eta ^s)\le 2\pi /\ln ^4n \text{ or } 0\lt \arg (\eta ^{-s})\le 2\pi /\ln ^4n. \end{equation*}
Indeed, consider the set
 $\mathcal{S}=\{\eta ^s\; :\; {1\leq s\leq \lceil \ln ^4n\rceil }\}$
. All elements of
 $\mathcal{S}$
are pairwise distinct. Indeed, suppose that
 $\eta ^{s_1}=\eta ^{s_2}$
for
 $1\le s_1\lt s_2\le \lceil \ln ^4n\rceil$
. Then
 $\eta ^{s_2-s_1}=1$
, so
 $s_2-s_1$
must be a multiple of the order of
 $\eta$
, which is
 $g'$
. This yields a contradiction because, since
 $n$
is assumed to be sufficiently large, we have
 \begin{equation*} s_2-s_1\lt \ln ^4n\lt n^{\varepsilon }\le g'. \end{equation*}
Let
 $\eta ^{s_1}$
and
 $\eta ^{s_2}$
, with
 $s_1\lt s_2$
, be two elements of
 $\mathcal{S}$
such that the distance between them on the unit circle
 $\mathbb{U}$
is minimal among all such pairs. Since this distance is at most
 $2\pi /\ln ^4n$
, we can set
 $s=s_2-s_1$
.
We now consider three cases and show that, in each of them,
 \begin{equation} \mathbb{P}[ \lambda _a=\lambda _b ] \le n^{-0.6\ln n}. \end{equation}
Case 1:
 $\arg (\eta ^{s})\le 2\pi /\ln ^4n$
.
We follow the strategy presented in Case A of the outline above. To establish the upper bound (22), it suffices to find a set
 $K\subseteq \{1,\ldots ,n-1\}$
of size
 $|K|=\lceil \ln ^2n\rceil$
that satisfies Conditions (i)–(iii) stated above. We set
 $K=\{s,2s,\ldots ,\lceil \ln ^2 n\rceil s\}$
.
Condition (i) for this set is ensured by the estimate
 $\arg (\xi )=2\pi -2\pi /g \ge 2\pi -2\pi /n^{6\varepsilon }$
and by the definition of Case 1. Since
 $n$
is large enough, due to (21) we have
 $\arg (\xi ^{\ell s})\gt 2\pi -2\pi /n^{5\varepsilon }$
for all
 $\ell \leq \lceil \ln ^2n\rceil$
. In the case under consideration we also have
 $\arg (\eta ^{\ell s})\lt \pi /\ln n$
for all
 $\ell \le \lceil \ln ^2 n\rceil$
. Consequently,
 \begin{equation*} \{\arg (\xi ^k)\}_{k\in K}\subset (2\pi -\pi / \! \ln n,2\pi )\text{ and }\{\arg (\eta ^k)\}_{k\in K}\subset (0,\pi /\ln n). \end{equation*}
This implies the other two Conditions (ii) and (iii), yielding the upper bound
 \begin{equation} \mathbb{P}[ \lambda _a=\lambda _b ] \le 2^{-|K|}\le 2^{-\ln ^2 n}\le n^{-0.6\ln n}. \end{equation}
Case 2:
 $\arg (\eta ^{-s})\le 2\pi / \! \ln ^4n$
and
 $\eta ^s\neq \xi ^s$
.
The first of the two assumptions ensures – similarly to Case 1 – that Condition (i) is fulfilled for every set
 $K\subseteq \{s,2s,\ldots ,(2\lceil \ln ^2 n\rceil ) s\}$
. Each such set
 $K$
also satisfies Condition (iii) because, similarly to Case 1, we have
 \begin{equation*} \{\arg (\xi ^k)\}_{k\in K}\subset (2\pi -2\pi / \! \ln n,2\pi )\text{ and }\{\arg (\eta ^k)\}_{k\in K}\subset (2\pi -2\pi / \! \ln n,2\pi ). \end{equation*}
These inclusions, however, do not guarantee Condition (ii). Nevertheless, we can show that Condition (ii) holds for at least one set
 $K\subseteq \{s,2s,\ldots ,(2\lceil \ln ^2 n\rceil ) s\}$
such that
 $|K|\ge \lceil \ln ^2 n\rceil$
.
Indeed, assume without loss of generality that
 $\arg (\xi ^{-s})\lt \arg (\eta ^{-s})$
. The existence of a suitable set
 $K$
follows from the observation that, among any two consecutive values
 $\arg (\xi ^{\ell s})$
and
 $\arg (\xi ^{(\ell +1)s})$
for
 $\ell \lt 2\lceil \ln ^2 n\rceil$
, at most one can belong to the set
 $\{\arg (\eta ^k)\}_{k\in \{s,2s,\ldots ,(2\lceil \ln ^2 n\rceil ) s\}}$
, because the distance between any two neighbouring elements of this set on the unit circle
 $\mathbb{U}$
(which is equal to
 $\arg (\eta ^{-s})$
) is larger than the distance between
 $\xi ^{\ell s}$
and
 $\xi ^{(\ell +1)s}$
(which is equal to
 $\arg (\xi ^{-s})$
). It follows that the set
 $K$
, consisting of all those
 $\ell s$
with
 $\ell \le 2\lceil \ln ^2 n\rceil$
such that
 $\arg (\xi ^{\ell s})\notin \{\arg (\eta ^k)\}_{k\in \{s,2s,\ldots ,(2\lceil \ln ^2 n\rceil ) s\}}$
, has the desired size. Condition (ii) is satisfied for this set by construction, and we obtain the upper bound (23) also in this case.
Case 3:
 $\arg (\eta ^{-s})\le 2\pi / \! \ln ^4n$
and
 $\eta ^s=\xi ^s$
.
Let
 $K=\{0,s,2s,\ldots ,\lceil \ln ^2 n\rceil s\}$
. Following our general strategy, let us expose all random variables
 $\sigma _j$
excepting
 $\sigma _{(k+1)r}$
for
 $k\in K$
. The event (8) can now be recast as the equality
 \begin{equation} \sum _{k\in K'}(\xi ^{k+1}-\eta ^{k+1})=c \end{equation}
for a constant
 $c\in \mathbb{C}$
and a random subset
 $K'\subseteq K$
. For
 $k=\ell s$
, we have
 \begin{equation*} \xi ^{k+1}-\eta ^{k+1}=\xi ^{\ell s+1}-\eta ^{\ell s+1}=\xi ^{\ell s+1}-\xi ^{\ell s}\eta =\xi ^{\ell s}(\xi -\eta ), \end{equation*}
which allows us to rewrite Equality (24) as
 \begin{equation} \sum _{k\in K'}\xi ^k=c/(\xi -\eta ) \end{equation}
(recall that
 $\xi \ne \eta$
). Since
 $\arg (\xi ^s)=\arg (\eta ^s)\ge 2\pi -2\pi / \! \ln ^4n$
, we have
 $\arg (\xi ^{\ell s})\gt 2\pi -2\pi /\ln n$
for all
 $\ell \le \lceil \ln ^2 n\rceil$
. We can, therefore, use Lemma 5.1 to conclude that Equality (25) can be true for at most one
 $K'\subseteq K$
. It follows that Equality (24), and as well Equality (8), holds with probability at most
 $2^{-|K|} \le n^{-0.6\ln n}$
.
Thus, Bound (22) is established in each of the three cases. Consequently,
 \begin{equation*} \sum _{(a,b)\in P_1}\mathbb{P}[ \lambda _a=\lambda _b ] \le |P_1|\cdot n^{-0.6\ln n} \le n^{-0.5\ln n}, \end{equation*}
where the last inequality holds because
 $n$
is assumed to be sufficiently large. The proof of the claim is complete.
Claim 2. Let
 $P_2=\{(a,b)\; :\; {g\geq n^{6\varepsilon }\text{ while }g'\lt n^{\varepsilon }}\}$
. Then
 \begin{equation*} \sum _{(a,b)\in P_2}\mathbb{P}[ \lambda _a=\lambda _b ]\le \exp {\left ( -n^\varepsilon \right )}. \end{equation*}
Proof. We closely follow the proof strategy presented (in a fairly complete form) in Case B of the outline above. Specifically, we set
 $m=n^{5\varepsilon }$
. Since
 $n$
is assumed to be sufficiently large, this implies
 $|K|\ge m/g'\gt n^{4\varepsilon }$
and also ensures Bound (19). This justifies the probability bound (20). Using the estimate
 $\binom{n}{k}\ge (n/k)^k$
, we conclude from (20) that if
 $(a,b)\in P_2$
, then
 \begin{equation*} \mathbb{P}[ \lambda _a=\lambda _b ] \lt {\left ( \frac 12+|K|^{-1/3} \right )}^{|K|/2}+2\exp {\left ( -|K|^{1/3} \right )}. \end{equation*}
Since
 $n$
is sufficiently large, this probability is bounded by
 $3\exp {\left ( -n^{4\varepsilon /3} \right )}$
and, therefore,
 \begin{equation*} \sum _{(a,b)\in P_2}\mathbb{P}[ \lambda _a=\lambda _b ]\le |P_2|\cdot 3\exp {\left ( -n^{4\varepsilon /3} \right )}\le \exp {\left ( -n^{\varepsilon } \right )}, \end{equation*}
as required.
Claim 3. Let
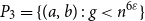 $P_3=\{(a,b)\; :\; {g \lt n^{6\varepsilon }}\}$
. Then
 \begin{equation*} \sum _{(a,b)\in P_3}\mathbb{P}[ \lambda _a=\lambda _b ] \le n^{-1/2+20\varepsilon }. \end{equation*}
Proof. As explained in Case C of the outline, we begin by considering the set
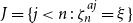 $J=\{j\lt n\; :\; {\zeta _n^{aj}=\xi }\}$
. This set can be described explicitly as
 $J=\{r+ig\; :\; {0\le i\lt n/g}\}$
. Define the subset
 $J'\subseteq J$
by
 $J'=\{r+igh \; :\; {0\le i\lt n/(gh)}\}$
and note that
 $\zeta _n^{bj}=\eta$
for all
 $j\in J'$
. The size of
 $J'$
can be bounded below by
 $n/(gh)\ge n/g^2\gt n^{1-12\varepsilon }$
.
Recall that
 $\eta \ne \xi$
. Exposing all
 $\sigma _j$
except those for
 $j\in J'$
, we obtain from Equality (8) that
 $\sum _{j\in J'}\sigma _j=c$
for a constant
 $c$
. This occurs with probability at most
 \begin{equation*} \binom{|J'|}{\lfloor |J'|/2\rfloor}2^{-|J'|} \lt |J'|^{-1/2} \lt n^{-1/2+6\varepsilon }, \end{equation*}
providing us with an upper bound for
 $\mathbb{P}[ \lambda _a=\lambda _b ]$
if
 $(a,b)\in P_3$
.
We now estimate the number of pairs
 $(a,b)$
in
 $P_3$
. Recall that
 $a=\gcd {(a,n)}\cdot a'$
, where
 $a'\le n/\gcd {(a,n)}=g\lt n^{6\varepsilon }$
. The factor
 $\gcd {(a,n)}$
of
 $a$
can take on at most
 $d(n)$
different values, where
 $d(n)$
denotes the total number of divisors of
 $n$
. It is known [Reference Apostol1, Theorem 13.12] that
 $d(n)=n^{O(1/\ln \ln n)}$
. Since there are less than
 $n^{6\varepsilon }$
possibilities to choose the factor
 $a'$
, the element
 $a$
can be chosen in at most
 $n^{7\varepsilon }$
ways, and the same holds true as well for
 $b$
. It follows that
 $|P_3|\le n^{14\varepsilon }$
, and we conclude that
 \begin{equation*} \sum _{(a,b)\in P_3}\mathbb{P}[ \lambda _a=\lambda _b ] \lt |P_3|\cdot n^{-1/2+6\varepsilon } \le n^{-1/2+20\varepsilon }, \end{equation*}
completing the proof of the claim.
 \begin{equation*} \sum _{0\le a,b\le n-1}\mathbb{P}[ \lambda _a=\lambda _b ] \le n^{-1/2+\varepsilon } \end{equation*}
for each
 $\varepsilon \gt 0$
and sufficiently large
 $n$
. This completes the proof of Part 1 of Theorem2.3. The proof of Part 2 proceeds in essentially the same way. The only difference is that, for an unexposed random variable
 $\sigma _j$
, instead of the term
 $\sigma _j\zeta _n^{aj}$
we now deal with
 $\sigma _j\zeta _n^{aj}+\sigma _{n-j}\zeta _n^{a(n-j)}=\sigma _j(\zeta _n^{aj}+\zeta _n^{-aj})$
. Lemma 5.1 remains applicable after multiplying the entire sum by an additional factor of
 $\zeta _n^{t'}$
for a small value of
 $t'$
. Finally, in Case 1 of the proof of Claim A, one has to address also the possibility that
 $\eta ^{-s}=\xi ^s$
, which is handled similarly to Case 3 of the proof.
Remark 5.2. The probability bound in Theorem 2.3 is nearly optimal. This can be shown by noticing that a random digraph
 $\textrm {Cay}(\mathbb{Z}_n,S)$
for
 $n=3p$
with
 $p$
prime has repeated eigenvalues with probability
 $\Omega (n^{-1/2})$
. Indeed, for
 $r=0,1,2$
, let
 $S_r=\{\!\{s\in S\}\!\}{s=r\pmod 3}$
. Note that
 \begin{equation*} \lambda _p=\sum _{j\in S}\zeta _n^{pj}=\sum _{j\in S}\zeta _3^{j}=\sum _{j\in S_0}1+\sum _{j\in S_1}\zeta _3+\sum _{j\in S_2}\zeta _3^{2}. \end{equation*}
Likewise,
 \begin{equation*} \lambda _{2p}=\sum _{j\in S}\zeta _n^{2pj}=\sum _{j\in S}\zeta _3^{2j}=\sum _{j\in S_0}1+\sum _{j\in S_1}\zeta _3^2+\sum _{j\in S_2}\zeta _3. \end{equation*}
As a consequence,
 $\lambda _p=\lambda _{2p}$
whenever
 $|S_1|=|S_2|$
. The last equality is true with probability
 $(1-o(1))/\sqrt {\pi n/3}$
because
 $|S_1|$
and
 $|S_2|$
are independent random variables with probability distribution
 $\textrm{Bin}(p,1/2)$
.
It can be similarly shown that, for
 $n=5p$
, the spectrum of a random graph
 $\textrm {Cay}(\mathbb{Z}_n,S)$
is not saturated with the same probability bound
 $\Omega (n^{-1/2})$
.
6. Proof of Theorem1.1
We are now ready to prove our main result. Specifically, we prove Theorem1.1 for each of the three concepts of a circulant:
-
• A Cayley (di)graph
$X=\textrm {Cay}(\mathbb{Z}_n,S)$
. The uniform probability distribution of
$X$
means that the connection set
$S$
is equiprobably chosen among all subsets of
$\mathbb{Z}_n \! \setminus \! \{0\}$
in the case of digraphs and among all inverse-closed subsets in the case of graphs. -
• An unlabelled circulant, that is, an isomorphism class of Cayley (di)graphs
$X=\textrm {Cay}(\mathbb{Z}_n,S)$
. The uniform distribution means that each isomorphism class on
$\mathbb{Z}_n$
is chosen equiprobably. In the algorithmic setting, an isomorphism class is presented by its representative (a (di)graph from the class). Alternatively, we can think of the probability distribution on all Cayley (di)graphs
$X=\textrm {Cay}(\mathbb{Z}_n,S)$
in which each
$X$
appears with probability
$1/(\ell _n\, s(X))$
, where
$\ell _n$
is the total number of
$n$
-vertex unlabelled circulants and
$s(X)$
is the number of connection sets
$S$
such that
$\textrm {Cay}(\mathbb{Z}_n,S)$
is isomorphic to
$X$
. -
• A labelled circulant, that is, an arbitrary (di)graph on the vertex set
$\{0,1,\ldots ,n-1\}$
isomorphic to some Cayley (di)graph
$X=\textrm {Cay}(\mathbb{Z}_n,S)$
. The uniform distribution is considered on all
$n$
-vertex (di)graphs in this class.


In each of the three cases, we use the same canonization algorithm presented in Section 3.2. For digraphs, the algorithm is extremely simple: We just individualize one vertex in an input digraph
 $X$
and run CR on the obtained vertex-coloured graph
 $X_0$
. In this way either we get an individual label for each vertex of
 $X$
or the algorithm gives up. The labelling is canonical for all circulants
 $X$
, and it is successfully produced whenever
 $X_0$
is walk-discrete. For graphs, the algorithm is a little bit more complicated and is discussed in detail in Section 3.2. It succeeds whenever
 $X_0$
is walk-saturated.
Lemma 2.1 and 2.2 provide us with two sufficient spectral conditions:
 $X_0$
is walk-discrete whenever
 $X$
has simple spectrum, and
 $X_0$
is walk-saturated whenever
 $X$
has saturated spectrum. This reduces our task to estimating the probability that the random digraph
 $X$
has simple spectrum and, respectively, that the random graph
 $X$
has saturated spectrum. In the case of Cayley (di)graphs, the proof is completed by applying Theorem2.3.
It remains to show that the estimate of Theorem2.3 stays as well true for the uniformly distributed labelled and unlabelled circulants. To this end, we present a general way to convert an estimate for one distribution into an estimate for another distribution with a small overhead cost.
6.1 Formal framework
We introduce the following notation simultaneously for graphs and digraphs. Let
 $\mathcal{C}$
be the set of all Cayley (di)graphs
 $X$
of cyclic groups, that is, all (di)graphs
 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
for any
 $n$
and
 $S$
. Recall that the notion of a Cayley (di)graph was formally defined in Section 3.2. According to this definition, two graphs
 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
and
 $Y=\textrm {Cay}(\mathbb{Z}_n,T)$
in
 $\mathcal{C}$
are different exactly when
 $S\ne T$
.
In general, speaking of a (di)graph
 $X$
, we always suppose that the vertex set of
 $X$
is
 $\{0,1,\ldots ,n-1\}$
, where
 $n$
is the order of
 $X$
. For a set of (di)graphs
 $\mathcal{Q}$
, by
 $\mathcal{Q}_n$
we denote the set of the (di)graphs in
 $\mathcal{Q}$
that have order
 $n$
. By
 ${\mathcal{Q}}^{\mathfrak{u}}$
we denote the unlabelled version of
 $\mathcal{Q}$
where isomorphic graphs are not distinguished. Formally,
 ${\mathcal{Q}}^{\mathfrak{u}}$
is the quotient set of
 $\mathcal{Q}$
by the isomorphism relation. In other words,
 ${\mathcal{Q}}^{\mathfrak{u}}$
consists of all unlabelled graphs whose representatives appear in
 $\mathcal{Q}$
. Furthermore,
 ${\mathcal{Q}}^{\mathfrak{l}}$
is defined to be the closure of
 $\mathcal{Q}$
under isomorphism, that is, if
 $\mathcal{Q}$
contains a (di)graph
 $X$
of order
 $n$
, then
 ${\mathcal{Q}}^{\mathfrak{l}}$
contains all graphs on the vertex set
 $\{0,1,\ldots ,n-1\}$
isomorphic to
 $X$
. We write
 ${\mathcal{Q}}^{\mathfrak{u}}_n$
and
 ${\mathcal{Q}}^{\mathfrak{l}}_n$
to denote the restrictions of
 ${\mathcal{Q}}^{\mathfrak{u}}$
and
 ${\mathcal{Q}}^{\mathfrak{l}}$
to the (di)graphs of order
 $n$
.
Note that
 ${{\mathcal{C}}}^{\mathfrak{u}}$
is precisely the set of unlabelled circulants, and
 ${{\mathcal{C}}}^{\mathfrak{l}}$
is the set of labelled circulants.
For an arbitrary set of (di)graphs
 $\mathcal{Q}$
, let
 $a(\mathcal{Q}_n)$
denote the minimum number of automorphisms of a (di)graph in
 $\mathcal{Q}_n$
. Note that
 \begin{equation} |{\mathcal{Q}}^{\mathfrak{l}}_n|\le |{\mathcal{Q}}^{\mathfrak{u}}_n|\,n!/a(\mathcal{Q}_n). \end{equation}
The following important fact is a consequence of the main result in [Reference Muzychuk35]; see [Reference Muzychuk35, Theorem 1.1] and the discussion right after its statement.
Proposition 6.1 (Muzychuk [Reference Muzychuk35]). For every
 $S\subseteq \mathbb{Z}_n\setminus \{0\}$
there are at most
 $\phi (n)$
sets
 $S'\subseteq \mathbb{Z}_n \! \setminus \! \{0\}$
such that
 $\textrm {Cay}(\mathbb{Z}_n,S')\cong \textrm {Cay}(\mathbb{Z}_n,S)$
.
Proposition 6.1 readily implies that if
 $\mathcal{Q}\subseteq {\mathcal{C}}$
, then
 \begin{equation} |{\mathcal{Q}}^{\mathfrak{u}}_n|\le |\mathcal{Q}_n|\le \phi (n)|{\mathcal{Q}}^{\mathfrak{u}}_n|. \end{equation}
Seeing
 $\mathbb{Z}_n$
as a ring with addition and multiplication modulo
 $n$
, we write
 $\mathbb{Z}_n^\times$
to denote the multiplicative group of order
 $\phi (n)$
consisting of the invertible elements of
 $\mathbb{Z}_n$
. For a set
 $S\subseteq \mathbb{Z}_n \! \setminus \! \{0\}$
, we define the subgroup
 $K(S)\le \mathbb{Z}_n^\times$
by
 $K(S)=\{k\in \mathbb{Z}_n^\times\; :\; {kS=S}\}$
. In the case of digraphs, we call a connection set
 $S$
multiplier-free if
 $K(S)=\{1\}$
. In the case of graphs, an inverse-closed connection set
 $S=-S$
is called multiplier-free if
 $K(S)=\{1,-1\}$
. The set of Cayley (di)graphs with multiplier-free connection sets is denoted by
 $\mathcal{A}$
.
We say that a set
 $\mathcal{Q}\subseteq {\mathcal{C}}$
is isomorphism-invariant within
 $\mathcal{C}$
if for every
 $X\in \mathcal{Q}$
and
 $Y\in {\mathcal{C}}$
, we have
 $Y\in \mathcal{Q}$
whenever
 $X\cong Y$
.
Lemma 6.2. The set
 $\mathcal{A}$
is isomorphism-invariant within
 $\mathcal{C}$
.
Proof. Assume that
 \begin{equation} \textrm {Cay}(\mathbb{Z}_n,S)\cong \textrm {Cay}(\mathbb{Z}_n,T). \end{equation}
Let
 $kS=S$
for
 $k\in \mathbb{Z}_n^\times$
. To obtain the lemma, it is enough to prove that
 $kT=T$
as well.
We use the following fact, which was conjectured by Zibin and proved by Muzychuk, Klin, and Pöschel [Reference Muzychuk, Klin and Pöschel36]. Let
 $d\mid n$
, i.e.,
 $d$
is a divisor of
 $n$
. For
 $S\subseteq \mathbb{Z}_n$
, define
 $(S)_d=\{s\in S\; :\; {\gcd (s,n)=d}\}$
. Then, according to [Reference Muzychuk, Klin and Pöschel36, Theorem 5.1], the isomorphism (28) implies that for every
 $d\mid n$
there exists
 $m_d\in \mathbb{Z}_n^\times$
such that
 $(T)_d=m_d(S)_d$
.
For
 $k\in \mathbb{Z}_n^\times$
, let
 $\mu _k$
be the permutation of
 $\mathbb{Z}_n$
defined by
 $\mu _k(x)=kx$
. The equality
 $kS=S$
means that
 $S$
is a union of orbits of
 $\mu _k$
, that is, there is a set
 $H\subset \mathbb{Z}_n$
such that
 \begin{equation*} S=\bigcup _{h\in H}\langle k\rangle h=\bigcup _{d\mid n}\bigcup _{h\in (H)_d}\langle k\rangle h, \end{equation*}
where
 $\langle k\rangle$
denotes the subgroup of
 $\mathbb{Z}_n^\times$
generated by
 $k$
. Note that
 $(S)_d=\bigcup _{h\in (H)_d}\langle k\rangle h$
. It follows that
 \begin{equation*} T=\bigcup _{d\mid n}(T)_d=\bigcup _{d\mid n}m_d(S)_d=\bigcup _{d\mid n}\bigcup _{h\in (H)_d}\langle k\rangle (hm_d). \end{equation*}
This shows that
 $T$
is also a union of orbits of
 $\mu _k$
and, as required,
 $kT=T$
.
If
 $\mathcal{Q}\subseteq {\mathcal{A}}$
is isomorphism-invariant within
 $\mathcal{C}$
, then the lower bound in (27) can be improved as follows:
 \begin{align} |\mathcal{Q}_n|&= \phi (n)|{\mathcal{Q}}^{\mathfrak{u}}_n|\quad\ \text{for digraphs,} \end{align}
 \begin{align} \frac {\phi (n)}2\,|{\mathcal{Q}}^{\mathfrak{u}}_n|\ \le |\mathcal{Q}_n|&\le \ \phi (n)|{\mathcal{Q}}^{\mathfrak{u}}_n|\quad \text{for graphs.} \end{align}
Indeed, if
 $\textrm {Cay}(\mathbb{Z}_n,S)\in {\mathcal{A}}$
and
 $k,k'\in \mathbb{Z}_n^\times$
, then the isomorphic copies
 $\textrm {Cay}(\mathbb{Z}_n,kS)$
and
 $\textrm {Cay}(\mathbb{Z}_n,k'S)$
of this graph are distinct (i.e.,
 $kS\ne k'S$
) whenever
 $k'\ne k$
in the case of digraphs and
 $k'\ne \pm k$
in the case of graphs.
Lemma 6.3.
-
1. A random connection set
$S\subseteq \mathbb{Z}_n\setminus \{0\}$
is not multiplier-free with probability less than
$n\,2^{-n/4}$
. -
2. A random inverse-closed connection set
$S=-S$
is not multiplier-free with probability less than
$2n\,2^{-n/8}$
.


Proof. Define the annihilator of
 $a\in \mathbb{Z}_n$
by
 $\textrm {Ann}(a)=\{x\in \mathbb{Z}_n\; :\; {xa=0}\}$
. Since
 $\textrm {Ann}(a)$
is a subgroup of
 $\mathbb{Z}_n$
, we have
 $|\textrm {Ann}(a)|\le n/2$
for every
 $a\ne 0$
.
-
1. It suffices to prove that, for each
$a\ne 1$
in
$\mathbb{Z}_n^\times$
, the equality
$aS=S$
is fulfilled with probability at most
$2^{-n/4}$
. Let
$\mu _a$
be the permutation of
$\mathbb{Z}_n$
defined by
$\mu _a(x)=ax$
. We have
$\mu _a(x)=x$
exactly when
$x\in \textrm {Ann}(a-1)$
. Thus,
$\mu _a$
is the identity on
$\textrm {Ann}(a-1)$
and a fixed-point-free permutation of the set
$\mathbb{Z}_n \! \setminus \! \textrm {Ann}(a-1)$
. Denote the restriction of
$\mu _a$
to the latter set by
$\mu '_a$
. Let
$c_1,\ldots ,c_t$
be the cycle type of
$\mu '_a$
. Note that
$\sum _{i=1}^tc_i=n-|\textrm {Ann}(a-1)|\ge n/2$
. Note also that
$t\le (\sum _{i=1}^tc_i)/2$
because
$c_i\ge 2$
for all
$i$
. The equality
$aS=S$
is true if and only if every cycle of
$\mu '_a$
either is entirely in
$S$
or is disjoint from
$S$
. This happens with probability
\begin{equation*} \prod _{i=1}^t 2^{-c_i+1}=2^{-(\sum _{i=1}^tc_i)+t}\le 2^{-(\sum _{i=1}^tc_i)/2}\le 2^{-n/4}. \end{equation*}
-
2. Again, it is enough to prove that, for each
$a\ne \pm 1$
in
$\mathbb{Z}_n^\times$
, the equality
$aS=S$
is fulfilled with probability at most
$2^{-n/8+2}$
. Let
$Z$
be the set of all pairs
$\{x,-x\}$
for
$x\in \mathbb{Z}_n$
such that
$x\ne -x$
. Note that
$|Z|=\lfloor (n-1)/2\rfloor$
. The permutation
$\mu _a$
naturally acts on
$Z$
by
$\mu _a(\{x,-x\})=\{ax,-ax\}$
. Let us estimate the number of fixed points under this action. We have
$\mu _a(\{x,-x\})=\{x,-x\}$
if and only if
$ax=x$
or
$ax=-x$
, which happens exactly when
$x\in \textrm {Ann}(a-1)\cup \textrm {Ann}(a+1)$
. Note that(31)
\begin{equation} |\textrm {Ann}(a-1)\cup \textrm {Ann}(a+1)|\le \frac n2+1. \end{equation}


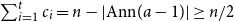


Indeed, let
 $b=\gcd (a-1,n)$
and
 $c=\gcd (a+1,n)$
, and note that
 $|\textrm {Ann}(a-1)|=b$
and
 $|\textrm {Ann}(a+1)|=c$
. Since the sets
 $\textrm {Ann}(a-1)$
and
 $\textrm {Ann}(a+1)$
share at least one element, namely
 $0$
, it is enough to prove that
 $b+c\le n/2+2$
. Since neither
 $a-1=0$
nor
 $a+1=0$
, neither
 $b$
nor
 $c$
exceeds
 $n/2$
. Hence, we are immediately done if
 $b\le 2$
or
 $c\le 2$
. Suppose, therefore, that both
 $b\ge 3$
and
 $c\ge 3$
.
Let
 $d=\gcd (b,c)$
. Since
 $d$
divides both
 $a-1$
and
 $a+1$
, we have
 $d\le 2$
. If
 $d=1$
, then
 $b$
and
 $c$
are coprime divisors of
 $n$
and, therefore,
 $b+c\le b+n/b$
. Note that
 $3\le b\le n/c\le n/3$
. In particular,
 $n\ge 9$
in this case. It follows that
 $b+c\le n/3+3\lt n/2+2$
.
If
 $d=2$
, then
 $b/2$
and
 $c/2$
are coprime divisors of
 $n/2$
. The similar argument yields
 \begin{equation*} \frac b2 + \frac c2 \le \frac b2 + \frac {n/2}{b/2} \le \frac n3 + \frac 32 \lt \frac n2+2, \end{equation*}
completing the proof of Bound (31).
Since
 $x$
belongs to
 $\textrm {Ann}(a-1)\cup \textrm {Ann}(a+1)$
simultaneously with
 $-x$
, the number of fixed points under the action of
 $\mu _a$
on
 $Z$
is at most
 $n/4$
. It follows that at least
 $n/4-1$
pairs in
 $Z$
are non-fixed. Similarly to Part 1, we conclude that
 $aS=S$
with probability at most
 $2^{-n/8+1}$
.
To conclude the notational stuff, let
 $\mathcal{Q}\subseteq {\mathcal{C}}$
. Then
 $\mathbb{P}[ \mathcal{Q}_n ]=|\mathcal{Q}_n|/|{\mathcal{C}}_n|$
is the probability that a random Cayley (di)graph
 $\textrm {Cay}(\mathbb{Z}_n,S)$
, where
 $S$
is chosen equiprobably among all possible connection sets
 $S\subseteq \mathbb{Z}_n \! \setminus \! \{0\}$
, belongs to
 $\mathcal{Q}$
. Exactly this random Cayley (di)graph model is considered in Theorem2.3 and studied in Section 5. In what follows, we also write
 $\mathbb{P}_{\mathfrak{l}}[ {\mathcal{Q}}^{\mathfrak{l}}_n ]$
to denote the probability that a random labelled circulant of order
 $n$
, that is, a (di)graph chosen randomly and uniformly in
 ${{\mathcal{C}}}^{\mathfrak{l}}_n$
, belongs to
 ${\mathcal{Q}}^{\mathfrak{l}}_n$
. Thus,
 $\mathbb{P}_{\mathfrak{l}}[ {\mathcal{Q}}^{\mathfrak{l}}_n ]=|{\mathcal{Q}}^{\mathfrak{l}}_n|/|{{\mathcal{C}}}^{\mathfrak{l}}_n|$
. Similarly,
 $\mathbb{P}_{\mathfrak{u}}[ {\mathcal{Q}}^{\mathfrak{u}}_n ]=|{\mathcal{Q}}^{\mathfrak{u}}_n|/|{{\mathcal{C}}}^{\mathfrak{u}}_n|$
is the probability that a random unlabelled circulant of order
 $n$
belongs to
 ${\mathcal{Q}}^{\mathfrak{u}}_n$
.
6.2 From cayley (di)graphs to unlabelled circulants
Lemma 6.4. Let
 $\mathcal{R}\subseteq {\mathcal{C}}$
. If
 $\mathcal{R}$
is isomorphism-invariant within
 $\mathcal{C}$
, then
 \begin{eqnarray*} \mathbb{P}_{\mathfrak{u}}[ {\mathcal{R}}^{\mathfrak{u}}_n ]&\le &(1+o(1))\,\mathbb{P}[ {\mathcal{R}}_n ]+n^2\,2^{-n/4}\quad \text{for digraphs,}\\[5pt] \mathbb{P}_{\mathfrak{u}}[ {\mathcal{R}}^{\mathfrak{u}}_n ]&\le &(2+o(1))\,\mathbb{P}[ {\mathcal{R}}_n ]+2n^2\,2^{-n/8}\quad \text{for graphs.} \end{eqnarray*}
Proof. We prove the inequality for graphs; the case of digraphs is similar. Note that
 ${{\mathcal{C}}}^{\mathfrak{u}}_n\setminus {{\mathcal{A}}}^{\mathfrak{u}}_n={({\mathcal{C}}_n \! \setminus \! {\mathcal{A}}_n)}^{\mathfrak{u}}$
due to Lemma 6.2. Applying the inequalities (27) to
 $\mathcal{Q}={\mathcal{C}}\setminus {\mathcal{A}}$
and to
 $\mathcal{Q}={\mathcal{C}}$
, we derive from Lemma 6.3
 \begin{equation} \mathbb{P}_{\mathfrak{u}}[ {{\mathcal{C}}}^{\mathfrak{u}}_n \! \setminus \! {{\mathcal{A}}}^{\mathfrak{u}}_n ]=\frac {|{{\mathcal{C}}}^{\mathfrak{u}}_n \! \setminus \! {{\mathcal{A}}}^{\mathfrak{u}}_n|}{|{{\mathcal{C}}}^{\mathfrak{u}}_n|} =\frac {|{({\mathcal{C}}_n \! \setminus \! {\mathcal{A}}_n)}^{\mathfrak{u}}|}{|{{\mathcal{C}}}^{\mathfrak{u}}_n|}\le \frac {|{\mathcal{C}}_n\setminus {\mathcal{A}}_n|}{|{\mathcal{C}}_n|/\phi (n)}=\phi (n)\,\mathbb{P}[ {\mathcal{C}}_n\setminus {\mathcal{A}}_n ]\le 2n^2\,2^{-n/8}. \end{equation}
Note that
 ${\mathcal{R}}^{\mathfrak{u}}_n\cap {{\mathcal{A}}}^{\mathfrak{u}}_n={(\mathcal{R}_n\cap {\mathcal{A}}_n)}^{\mathfrak{u}}$
because
 $\mathcal{A}$
is isomorphism-invariant within
 $\mathcal{C}$
by Lemma 6.2 and
 $\mathcal{R}$
is isomorphism-invariant within
 $\mathcal{C}$
by assumption. Using Bound (32) and applying the inequalities (30) to
 $\mathcal{Q}=\mathcal{R}\cap {\mathcal{A}}$
and to
 $\mathcal{Q}={\mathcal{A}}$
, we obtain
 \begin{align*} \mathbb{P}_{\mathfrak{u}}[ {\mathcal{R}}^{\mathfrak{u}}_n ]\le \mathbb{P}_{\mathfrak{u}}[ {\mathcal{R}}^{\mathfrak{u}}_n\cap {{\mathcal{A}}}^{\mathfrak{u}}_n ]+\mathbb{P}_{\mathfrak{u}}[ {{\mathcal{C}}}^{\mathfrak{u}}_n\setminus {{\mathcal{A}}}^{\mathfrak{u}}_n ]\le \frac {\mathbb{P}_{\mathfrak{u}}[ {\mathcal{R}}^{\mathfrak{u}}_n\cap {{\mathcal{A}}}^{\mathfrak{u}}_n ]}{\mathbb{P}_{\mathfrak{u}}[ {{\mathcal{A}}}^{\mathfrak{u}}_n ]}+2n^2\,2^{-n/8} =\frac {|{\mathcal{R}}^{\mathfrak{u}}_n\cap {{\mathcal{A}}}^{\mathfrak{u}}_n|}{|{{\mathcal{A}}}^{\mathfrak{u}}_n|}+2n^2\,2^{-n/8}\\[5pt] =\frac {|{(\mathcal{R}_n\cap {\mathcal{A}}_n)}^{\mathfrak{u}}|}{|{{\mathcal{A}}}^{\mathfrak{u}}_n|}+2n^2\,2^{-n/8} \le \frac {2\,|\mathcal{R}_n\cap {\mathcal{A}}_n|/\phi (n)}{|{\mathcal{A}}_n|/\phi (n)}+2n^2\,2^{-n/8}\le \frac {2\,|\mathcal{R}_n|}{|{\mathcal{A}}_n|}+2n^2\,2^{-n/8}\\[5pt] =\frac {2\,\mathbb{P}[ \mathcal{R}_n ]}{\mathbb{P}[ {\mathcal{A}}_n ]}+2n^2\,2^{-n/8} =(2+o(1))\,\mathbb{P}[ \mathcal{R}_n ]+2n^2\,2^{-n/8}. \end{align*}
For the last equality we used Lemma 6.3 once again.
Let
 $\mathcal{R}$
be the set of all Cayley digraphs
 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
whose spectrum is not simple. In the case of graphs, we set
 $\mathcal{R}$
to be the set of all
 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
whose spectrum is not saturated. Lemma 6.4 implies that the bound of Theorem2.3 holds true also for unlabelled circulants. This completes the proof of Theorem1.1 in the unlabelled case.
6.3 From unlabelled to labelled circulants
For
 $a\in \mathbb{Z}_n$
, define a bijection
 $\sigma _a:\mathbb{Z}_n \rightarrow \mathbb{Z}_n$
by
 $\sigma _a(x)=x+a$
. For every Cayley digraph
 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
, the map
 $\sigma _a$
is an automorphism of
 $X$
for all
 $a$
. If
 $X$
has no other automorphism, that is,
 $\textrm {Aut}(X)$
is as small as possible (see [Reference Dobson, Malnič and Marušič16, Section 8.1]), then we call
 $X$
firm. In other words,
 $X$
is firm exactly when
 $\textrm {Aut}(X)\cong \mathbb{Z}_n$
.
Now, let
 $X$
be a Cayley graph. In this case there is also another automorphism
 $\rho$
defined by
 $\rho (x)=-x$
. The automorphisms
 $\sigma _1$
and
 $\rho$
generate a subgroup of
 $\textrm {Aut}(X)$
isomorphic to the dihedral group
 $D_{2n}$
. If
 $X$
has no other automorphisms, i.e.,
 $\textrm {Aut}(X)\cong D_{2n}$
, then we say that
 $X$
is a firm Cayley graph of
 $\mathbb{Z}_n$
. Note that a firm graph is not firm as a digraph; this should not make any confusion because we treat random graphs and random digraphs separately (even when in parallel).
The set of firm (di)graphs is denoted by
 $\mathcal{F}$
. The following equalities easily follow from the definitions: If
 $\mathcal{Q}\subseteq {\mathcal{F}}$
, then
 \begin{eqnarray} |{\mathcal{Q}}^{\mathfrak{l}}_n|&=&(n-1)!\,|{\mathcal{Q}}^{\mathfrak{u}}_n|\quad \text{for digraphs,} \end{eqnarray}
 \begin{eqnarray} |{\mathcal{Q}}^{\mathfrak{l}}_n|&=&\frac {(n-1)!}2\,|{\mathcal{Q}}^{\mathfrak{u}}_n|\quad \text{for graphs.} \end{eqnarray}
We will need the following estimates obtained in [Reference Bhoumik, Dobson and Morris8, Reference Dobson, Spiga and Verret15].Footnote 5
Proposition 6.5.
-
1.
$\mathbb{P}[ {\mathcal{C}}_n\setminus {\mathcal{F}}_n ]=2^{-n/4+o(n)}$
for digraphs (Dobson, Spiga, and Verret [Reference Dobson, Spiga and Verret15, Theorem 1.6]). -
2.
$\mathbb{P}[ {\mathcal{C}}_n\setminus {\mathcal{F}}_n ]=O(n2^{-n/8})$
for graphs (Bhoumik, Dobson, and Morris [Reference Bhoumik, Dobson and Morris8, Theorem 3.2]).


Note that
 ${{\mathcal{C}}}^{\mathfrak{u}}_n\setminus {{\mathcal{F}}}^{\mathfrak{u}}_n={({\mathcal{C}}_n \! \setminus \! {\mathcal{F}}_n)}^{\mathfrak{u}}$
because
 $\mathcal{F}$
is obviously isomorphism-invariant within
 $\mathcal{C}$
. Applying the inequalities (27) to
 $\mathcal{Q}={\mathcal{C}}\setminus {\mathcal{F}}$
and to
 $\mathcal{Q}={\mathcal{C}}$
, similarly to (32) we get the relation
 \begin{equation*} \mathbb{P}_{\mathfrak{u}}[ {{\mathcal{C}}}^{\mathfrak{u}}_n \! \setminus \! {{\mathcal{F}}}^{\mathfrak{u}}_n ]\le \phi (n)\,\mathbb{P}[ {\mathcal{C}}_n \! \setminus \! {\mathcal{F}}_n ]. \end{equation*}
By Proposition 6.5, this implies that
 \begin{eqnarray} \mathbb{P}_{\mathfrak{u}}[ {{\mathcal{C}}}^{\mathfrak{u}}_n\setminus {{\mathcal{F}}}^{\mathfrak{u}}_n ]&=&2^{-n/4+o(n)}\quad \text{for digraphs,} \end{eqnarray}
 \begin{eqnarray} \mathbb{P}_{\mathfrak{u}}[ {{\mathcal{C}}}^{\mathfrak{u}}_n\setminus {{\mathcal{F}}}^{\mathfrak{u}}_n ]&=&O(n^2\,2^{-n/8})\quad \text{for graphs.} \end{eqnarray}
Lemma 6.6. Let
 $\mathcal{S}\subseteq {\mathcal{C}}$
. If
 $\mathcal{S}$
is isomorphism-invariant within
 $\mathcal{C}$
, then
 \begin{eqnarray*} \mathbb{P}_{\mathfrak{l}}[ {\mathcal{S}}^{\mathfrak{l}}_n ]&\ge &\mathbb{P}_{\mathfrak{u}}[ {\mathcal{S}}^{\mathfrak{u}}_n ]-2^{-n/4+o(n)}\quad \text{for digraphs,}\\[5pt] \mathbb{P}_{\mathfrak{l}}[ {\mathcal{S}}^{\mathfrak{l}}_n ]&\ge &\mathbb{P}_{\mathfrak{u}}[ {\mathcal{S}}^{\mathfrak{u}}_n ]-O(n^2\,2^{-n/8})\quad \text{for graphs.} \end{eqnarray*}
Proof. We prove the inequality for graphs; the case of digraphs is similar. Note that
 ${\mathcal{S}}^{\mathfrak{u}}_n\cap {{\mathcal{F}}}^{\mathfrak{u}}_n={(\mathcal{S}_n\cap {\mathcal{F}}_n)}^{\mathfrak{u}}$
and
 ${\mathcal{S}}^{\mathfrak{l}}_n\cap {{\mathcal{F}}}^{\mathfrak{l}}_n={(\mathcal{S}_n\cap {\mathcal{F}}_n)}^{\mathfrak{l}}$
because both
 $\mathcal{S}$
and
 $\mathcal{F}$
are isomorphism-invariant within
 $\mathcal{C}$
. Applying the inequality (26) to
 $Q={\mathcal{C}}$
and the equality (34) to
 $\mathcal{Q}=\mathcal{S}\cap {\mathcal{F}}$
, we derive
 \begin{align} \mathbb{P}_{\mathfrak{l}}[ {\mathcal{S}}^{\mathfrak{l}}_n ]\ge \mathbb{P}_{\mathfrak{l}}[ {\mathcal{S}}^{\mathfrak{l}}_n\cap {{\mathcal{F}}}^{\mathfrak{l}}_n ] & = \frac {|{\mathcal{S}}^{\mathfrak{l}}_n\cap {{\mathcal{F}}}^{\mathfrak{l}}_n|}{|{{\mathcal{C}}}^{\mathfrak{l}}_n|}=\frac {|{(\mathcal{S}_n\cap {\mathcal{F}}_n)}^{\mathfrak{l}}|}{|{{\mathcal{C}}}^{\mathfrak{l}}_n|} \nonumber\\& \ge \frac {(n-1)!\,|{(\mathcal{S}_n\cap {\mathcal{F}}_n)}^{\mathfrak{u}}|/2}{(n-1)!\,|{{\mathcal{C}}}^{\mathfrak{u}}_n|/2} =\frac {|{\mathcal{S}}^{\mathfrak{u}}_n\cap {{\mathcal{F}}}^{\mathfrak{u}}_n|}{|{{\mathcal{C}}}^{\mathfrak{u}}_n|}= \mathbb{P}_{\mathfrak{u}}[ {\mathcal{S}}^{\mathfrak{u}}_n\cap {{\mathcal{F}}}^{\mathfrak{u}}_n ]. \end{align}
This implies that
 \begin{equation*} \mathbb{P}_{\mathfrak{l}}[ {\mathcal{S}}^{\mathfrak{l}}_n ]\ge \mathbb{P}_{\mathfrak{u}}[ {\mathcal{S}}^{\mathfrak{u}}_n ]-\mathbb{P}_{\mathfrak{u}}[ {{\mathcal{C}}}^{\mathfrak{u}}_n\setminus {{\mathcal{F}}}^{\mathfrak{u}}_n ]\ge \mathbb{P}_{\mathfrak{u}}[ {\mathcal{S}}^{\mathfrak{u}}_n ]-O(n^2\,2^{-n/8}). \end{equation*}
The last inequality follows from the bound (36).
Now, let
 $\mathcal{S}$
be the set of all Cayley digraphs
 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
with simple spectrum. In the case of graphs, we set
 $\mathcal{S}$
to be the set of all
 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
with saturated spectrum. We already know that the bound of Theorem2.3 holds true for unlabelled circulants. Lemma 6.6 implies that it is as well true for labelled circulants.
Lemma 6.6 provides a rather general way of showing that if a property holds for almost all unlabelled circulants, then it also holds for almost all labelled circulants. We remark that that for the property
 $\mathcal{S}$
that a circulant digraph has simple spectrum (or that a circulant graph has saturated spectrum) this can be alternatively derived from Lemma 2.1, 2.2, and 3.2. Indeed, these lemmas imply that
 $\mathcal{S}\subseteq {\mathcal{F}}$
, which allows us to obtain the inequality
 $\mathbb{P}_{\mathfrak{l}}[ {\mathcal{S}}^{\mathfrak{l}}_n ]\ge \mathbb{P}_{\mathfrak{u}}[ {\mathcal{S}}^{\mathfrak{u}}_n ]$
directly from (38).
The proof of Theorem1.1 is complete.
7. Canonical Cayley representations via 2-WL
This section is devoted to the proof of Theorem1.2. Before presenting the proof in Subsection 7.4, we provide a formal description of the
 $2\text{-}\textrm{WL}$
algorithm in Subsection 7.1, and collect relevant preliminary results in Sections 7.2 and 7.3.
7.1 Description of 2-WL
For notational simplicity, an ordered pair
 $(a,b)$
will be denoted by
 $ab$
. Given a loopless digraph
 $X=(V,E)$
as an input,
 $2\text{-}\textrm{WL}$
iteratively computes a sequence of colourings
 $c^i_X$
of the Cartesian square
 $V\times V$
. The initial colouring is defined by
 $c^0_X(uv)=(\textit{type}(uv),\textit{type}(vu))$
where
 $\textit{type}(uv)$
takes on one of three values according to the type of an ordered vertex pair
 $uv$
, namely arc if
 $uv\in E$
, nonarc if
 $uv\notin E$
and
 $u\ne v$
, and loop if
 $u=v$
. The colouring is modified iteratively as follows:
 \begin{equation*} c^{i+1}_X(uv)=\{\!\{{\left ( c^{i}_X(uw), c^{i}_X(wv) \right )}\}\!\}_{w\in V}. \end{equation*}
In words, the new colour of a pair
 $uv$
is a “superposition” of all old colour pairs observable along the extensions of
 $uv$
to a triple
 $uwv$
. Denote the partition of
 $V\times V$
into the colour classes of
 $c^i_X$
by
 $\mathcal{C}^i_X$
. A simple inductive argument shows that
 \begin{equation*} c^{i+1}_X(uv)\ne c^{i+1}_X(u'v')\text{ whenever }c^{i}_X(uv)\ne c^{i}_X(u'v') \end{equation*}
which means that
 $\mathcal{C}^{i+1}_X$
is finer than or equal to
 $\mathcal{C}^i_X$
. It follows that the partition stabilizes starting from some step
 $t=t(X)$
, that is,
 $\mathcal{C}^{t}_X=\mathcal{C}^{t-1}_X$
, which implies that
 $\mathcal{C}^i_X=\mathcal{C}^{t-1}_X$
for all
 $i\ge t$
. Note that
 $t\le |V|^2$
. As soon as the stabilization is reached, the algorithm terminates and outputs the colouring
 $c^t_X$
.
An easy induction on
 $i$
shows that, if
 $\phi$
is an isomorphism from
 $X$
to
 $Y$
, then
 \begin{equation} c^i_X(uv)=c^i_Y(\phi (u)\phi (v)). \end{equation}
Note that the length of
 $c^i_X$
-colours (in any natural encoding) grows exponentially with
 $i$
increasing. Similarly to CR, the exponential blow-up is remedied by renaming the colours after each step. Finally, note that
 $2\text{-}\textrm{WL}$
can be implemented in time
 $O(n^3\log n)$
; see [Reference Immerman and Lander26, Reference Immerman and Sengupta27].
Let
 $\textrm {WL}_2(X)=\mathcal{C}^{t}_X$
denote the stabilized partition of
 $V^2$
. It can be noticed that
 $\textrm {WL}_2(X)$
forms a coherent configuration [Reference Chen and Ponomarenko13], but we will not use this fact directly. However, we will need another source of coherent configurations, which we introduce in the next subsection.
7.2 Orbitals of a permutation group
Let
 $G\le \textrm {Sym}(V)$
be a group of permutations of a set
 $V$
. A natural action of
 $G$
on
 $V^2$
is defined by
 $\alpha (x,y)=(\alpha (x),\alpha (y))$
for
 $x,y\in V$
and
 $\alpha \in G$
. An orbit of this action is called orbital. We denote the partition of
 $V^2$
into the orbitals of
 $G$
by
 $\textrm {Orb}_2(G)$
.
Equality (39) readily implies that the partition
 $\textrm {WL}_2(X)$
is refined by the partition
 $\textrm {Orb}_2(\textrm {Aut}(X))$
. Similarly to the concept of a Schurian coherent configuration [Reference Chen and Ponomarenko13], we call a digraph
 $X$
Schurian if
 $\textrm {WL}_2(X)=\textrm {Orb}_2(\textrm {Aut}(X))$
.
For each
 $a\in \mathbb{Z}_n$
, a digraph
 $X=\textrm {Cay}(\mathbb{Z}_n,S)$
has an automorphism
 $\sigma _a$
defined by
 $\sigma _a(x)=x+a$
. These automorphisms form a subgroup of
 $\textrm {Aut}(X)$
. If this subgroup is normal, the circulant
 $X$
is called normal (see [Reference Dobson, Malnič and Marušič16, Chapter 8.1], where this concept is discussed in the more general setting of Cayley graphs for any groups). Note that if
 $X$
is firm – according to the definition given in Section 6.3, then
 $X$
is normal. This is true both for digraphs and graphs (in the case of graphs, recall that every subgroup of index 2 is normal).
Proposition 7.1 [Reference Evdokimov and Ponomarenko21, Theorem 6.1]. Every normal circulant digraph is Schurian.
Extending the definition of a firm Cayley (di)graph in Section 6.3, we also call an arbitrary labelled circulant (di)graph firm if it is isomorphic to a firm Cayley (di)graph
 $\textrm {Cay}(\mathbb{Z}_n,S)$
or, equivalently, if
 $\textrm {Aut}(X)$
is as small as possible, i.e.,
 $\textrm {Aut}(X)$
isomorphic to the cyclic group in the directed case and to the dihedral group in the undirected case.
The Schurity property of a digraph
 $X$
is beneficial because it enables an efficient computation of the partition
 $\textrm {Orb}_2(\textrm {Aut}(X))$
just by running
 $2\text{-}\textrm{WL}$
on
 $X$
. Moreover, if
 $X$
is a firm circulant (di)graph, then the knowledge of
 $\textrm {Orb}_2(\textrm {Aut}(X))$
allows us to determine the automorphism group
 $\textrm {Aut}(X)$
as a permutation group. We now state this fact formally in the form that will be useful in the next subsection.
Let
 $C_n$
denote a cyclic permutation group on the
 $n$
-element set
 $V$
that acts on
 $V$
transitively or, equivalently, contains a cycle of length
 $n$
. Assume that
 $n\ge 3$
and note that
 $C_n$
has a unique extention to a dihedral group (of permutations of
 $V$
). We denote this dihedral permutation group by
 $D_{2n}$
. Note that all
 $\phi (n)$
elements of order
 $n$
in
 $C_n$
are cycles of length
 $n$
. The same holds true for
 $D_{2n}$
. Indeed, every element in
 $D_{2n} \! \setminus \! C_n$
has degree 2. We now observe that, given the partitions
 $\textrm {Orb}_2(C_n)$
and
 $\textrm {Orb}_2(D_{2n})$
, the elements of order
 $n$
in
 $C_n$
and
 $D_{2n}$
can be explicitly constructed as permutations of the set
 $V$
.
Lemma 7.2.
-
1. The
$\phi (n)$
generators of
$C_n$
are uniquely determined by
$\textrm {Orb}_2(C_n)$
and can be constructed from
$\textrm {Orb}_2(C_n)$
in time
$O(n^2)$
. -
2. The
$\phi (n)$
elements of order
$n$
of
$D_{2n}$
are uniquely determined by
$\textrm {Orb}_2(D_{2n})$
and can be constructed from
$\textrm {Orb}_2(D_{2n})$
in time
$O(n^2)$
.


Proof.
-
1. Assume for a while that
$V=\mathbb{Z}_n$
and that
$C_n$
consists of the permutations
$\sigma _a$
,
$a\in \mathbb{Z}_n$
, defined (like above) by
$\sigma _a(x)=x+a$
. Note that
$\sigma _a$
is a generator of
$C_n$
if and only if
$a\in \mathbb{Z}_n^\times$
. Each orbital of
$C_n$
will be regarded as a digraph. As easily seen, two pairs
$(x,y)$
and
$(x',y')$
are in the same orbital exactly when
$y-x=y'-x'$
. It follows that the orbitals of
$C_n$
are exactly the digraphs
$\textrm {Cay}(\mathbb{Z}_n,\{a\})$
for
$a\in \mathbb{Z}_n$
. Note that
$\textrm {Cay}(\mathbb{Z}_n,\{a\})$
has
$\gcd (a,n)$
connected components, and each of them is isomorphic to the directed cycle of length
$n/\gcd (a,n)$
. This implies that, in general, the generating elements of
$C_n$
can be identified by finding all
$\phi (n)$
orbitals of
$C_n$
that, viewed as digraphs, are directed cycles of length
$n$
. For each such cycle, one then forms a cyclic permutation of
$V$
along the cycle. -
2. Note that
$\textrm {Orb}_2(C_n)$
contains, along with each orbital
$C=\textrm {Cay}(\mathbb{Z}_n,\{a\})$
, its transpose
$C'=\textrm {Cay}(\mathbb{Z}_n,\{-a\})$
. As easily seen, the orbitals of
$D_{2n}$
are exactly the symmetric closures
$C\cup C'=\textrm {Cay}(\mathbb{Z}_n,\{-a,a\})$
of the orbitals of
$C_n$
. Therefore, the elements of order
$n$
of
$D_{2n}$
are identified by finding all
$\phi (n)/2$
orbitals of
$D_{2n}$
that are (undirected) cycles of length
$n$
and by forming, along each of these cycles, two cyclic permutations of
$V$
in both directions.


7.3 Cayley representations of firm circulants
Recall that a Cayley representation of a labelled circulant
 $X$
on
 $n$
vertices is a map
 $\lambda :V(X) \rightarrow \mathbb{Z}_n$
such that
 $X^\lambda$
is a Cayley graph, i.e.,
 $X^\lambda =\textrm {Cay}(\mathbb{Z}_n,S)$
for some
 $S$
. We call two Cayley representation
 $\lambda$
and
 $\lambda '$
of
 $X$
equivalent if
 $X^\lambda =X^{\lambda '}$
. If
 $X^\lambda =\textrm {Cay}(\mathbb{Z}_n,S)$
, then
 $\lambda$
and
 $\lambda '$
are equivalent if and only if
 $\lambda '=\alpha \lambda$
for some automorphism
 $\alpha$
of
 $\textrm {Cay}(\mathbb{Z}_n,S)$
. Thus, if
 $X$
is a firm digraph, then
 $\lambda$
has exactly
 $n$
equivalent Cayley representations, and if
 $X$
is a firm graph, then
 $\lambda$
has exactly
 $2n$
equivalent representations. It is useful to notice the following simple fact.
Lemma 7.3.
-
1. Let
$X$
be a firm circulant digraph. There is a one-to-one correspondence between the equivalence classes of Cayley representations of
$X$
and the generators of
$\textrm {Aut}(X)$
. -
2. Let
$X$
be a firm circulant graph on
$n$
vertices. There is a one-to-one correspondence between the equivalence classes of Cayley representations of
$X$
and the pairs of mutually inverse cycles of length
$n$
in
$\textrm {Aut}(X)$
. -
3. In both cases, if a cycle of length
$n$
in
$\textrm {Aut}(X)$
is given, a Cayley representation of
$X$
from the corresponding equivalence class is constructible in linear time.


Proof. Let
 $\lambda$
be a Cayley representation of
 $X$
. The cycle
 $(\lambda ^{-1}(0),\lambda ^{-1}(1),\ldots ,\lambda ^{-1}(n-1))$
is a generator of
 $\textrm {Aut}(X)$
. Every Cayley representation
 $\lambda '$
equivalent to
 $\lambda$
yields the same generator. Conversely, every cycle of length
 $n$
in
 $\textrm {Aut}(X)$
determines, in an explicit way,
 $n$
equivalent Cayley representations of
 $X$
.
The case of graphs is similar with the only difference that a cycle
 $(v_0,v_1,\ldots ,v_{n-1})$
and its inverse
 $(v_{n-1},\ldots ,v_1,v_0)$
yield equivalent Cayley representations of
 $X$
.
Lemma 7.3 implies that every firm circulant digraph
 $X$
on
 $n$
vertices has, up to equivalence, exactly
 $\phi (n)$
Cayley representations. In the case that
 $X$
is a graph, there are, up to equivalence, exactly
 $\phi (n)/2$
Cayley representations.
7.4 Proof of Theorem1.2
We design an algorithm such that the following three conditions are fulfilled for a certain class of (di)graphs
 $\mathcal{C}$
:
-
• the algorithm computes a canonical Cayley representation for all inputs in
$\mathcal{C}$
; -
• the algorithm gives up on all inputs not in
$\mathcal{C}$
; -
•
$\mathcal{C}$
contains all firm circulant (di)graphs.


The last condition ensures the success probability bound stated in Theorem1.2. Indeed, a random Cayley (di)graph
 $\textrm {Cay}(\mathbb{Z}_n,S)$
is firm with high probability by Proposition 6.5, and this remains true for a random labelled circulant by the transition lemmas obtained in Section 6, i.e., by Lemma 6.4 and 6.6.
Since firm circulant (di)graphs are normal, Proposition 7.1 shows that the orbital partition
 $\textrm {Orb}_2(\textrm {Aut}(X))$
for a firm circulant
 $X$
can be computed just by running
 $2\text{-}\textrm{WL}$
on
 $X$
. According to [Reference Immerman and Lander26, Reference Immerman and Sengupta27], this takes time
 $O(n^3\log n)$
, where
 $n$
is the number of vertices in
 $X$
. Given
 $\textrm {Orb}_2(\textrm {Aut}(X))$
, one can easily determine all cycles of length
 $n$
in the permutation group
 $\textrm {Aut}(X)$
; see Lemma 7.2. By Lemma 7.3, these can be used to efficiently construct all Cayley representations of
 $X$
. Note that it is enough to have one representation from each equivalence class. Summing up, we come to the following procedure.
CANONICAL CAYLEY REPRESENTATION ALGORITHM
INPUT: a (di)graph
 $X$
.
-
1. Run
$2\text{-}\textrm{WL}$
on
$X$
. -
2. Check whether the partition
$\textrm {WL}_2(X)$
contains a part that is isomorphic to a cycle (di)graph of length
$n$
. If not, terminate. Otherwise, let
$C$
be the part of
$\textrm {WL}_2(X)$
of this kind that has the lexicographically smallest
$2\text{-}\textrm{WL}$
-colour. -
3. Choose an arbitrary vertex
$x_0$
and enumerate the vertices of
$X$
along
$C$
starting from
$x_0$
(in the case of graphs, choose any of the two directions in
$C$
). Let
$x_0,x_1,\ldots ,x_{n-1}$
be the obtained enumeration. -
4. Check whether the cyclic permutation
$(x_0x_1\ldots x_{n-1})$
is an automorphism of
$X$
. If not, then give up. -
5. Output the labelling
$\lambda _X:V(X) \rightarrow \mathbb{Z}_n$
where
$\lambda _X(x_i)=i$
.


The proof of Theorem1.2 is complete.
Remark 7.4. Proposition 7.1 can also be used to show that
 $2\text{-}\textrm{WL}$
distinguishes a firm circulant (di)graph
 $X$
from any other non-isomorphic (di)graph
 $Y$
in the sense that the colour palettes produced by
 $2\text{-}\textrm{WL}$
on
 $X$
and
 $Y$
are different, i.e.,
 $\{\!\{c^{t(X)}_X(uv)\; :\; {uv\in V(X)^2}\}\!\}\ne \{\!\{c^{t(Y)}_Y(uv)\; :\; {uv\in V(Y)^2}\}\!\}$
. The class of the firm circulant digraphs contains all circulant digraphs with simple spectrum [Reference Elspas and Turner18, Theorem 3]. For this smaller class of circulant digraphs, the identifiability by
 $2\text{-}\textrm{WL}$
follows also from any of the results stated in [Reference Friedland22, Corollary 4.5] or [Reference Evdokimov and Ponomarenko20, Corollary of Theorem 1] (the latter results is stronger than the former in view of [Reference Chen and Ponomarenko13, Theorem 3.3.19]).
Acknowledgements
The authors gratefully acknowledge the anonymous referee for their careful reading of the manuscript and numerous helpful comments, which significantly improved the presentation of the manuscript.
Data availability statement
This is a purely theoretical research, no new data were created or analyzed in the study.
Funding statement
Oleg Verbitsky is supported by DFG grant KO 1053/8–2.
Competing interests
The authors declare none.



