





1. Introduction
One fundamental process in early language development is infants’ ability to segment the speech to which they are exposed in order to extract and generalize meaningful linguistic units. In recent decades, naturalistic and experimental research has deepened our understanding of input characteristics that support this online processing. Unique phonetic, prosodic, lexical, and syntactic features that distinguish the speech addressed to children (child-directed speech [CDS]) from speech to adults (adult-directed speech [ADS]) (Soderstrom, 2007) provide cues that support speech perception processes such as segmentation.
Among CDS features, repetition with variation has been especially related to children’s language development (Lester et al., Reference Lester, Moran, Aylin, Allen, Pfeiler and Stoll2022; Soderstrom, 2007). The sheer frequency of a word is among the best predictors of how early it is acquired (Goodman et al., Reference Goodman, Dale and Li2008) and of the composition of children’s early vocabulary (Cameron-Faulkner et al., Reference Cameron-Faulkner, Lieven and Tomasello2003). Evidence indicates that repetition paves the way for learning. This is particularly the case when structured in contiguous utterances – within one interactional turn – which present the repeated word in different morphosyntactic contexts (Lester et al., Reference Lester, Moran, Aylin, Allen, Pfeiler and Stoll2022). In “variation sets (VS)” (Küntay & Slobin, Reference Küntay, Slobin, Slobin, Gerhartd, Kyratzis and Guo1996, Reference Küntay and Slobin2002), partial repetitions are embedded in reformulated utterances that play a constant pragmatic intention (regulating action, providing or requesting information).
(1)
FA1:
¡ay qué lindo chancho!
“oh what a nice pig!”
FA1:
¿quién está haciendo sonar el chancho?
“who is making the pig sound?”
Repetition with variation might also influence which categories of words (nouns, verbs, or adjectives) children learn in the long term. The proportion of words from specific categories in naturalistic speech may be influenced by certain typological characteristics of the language, such as canonical word order and whether it is pro-drop or non-pro-drop. For example, English, a non-pro-drop language that does not omit the subject in most contexts, tends to contain more nouns in CDS than Spanish, a pro-drop language (Casart Quintero & Iribarren Perez, Reference Casart Quintero and Iribarren Perez2007; Dhillon, Reference Dhillon2010). Also, households in diverse socioeconomic circumstances may differ in activities and conversational interactions that influence the proportion of different word types. For instance, book-reading and object-play situations – more frequent in middle socioeconomic status (SES) than in low-SES families – are characterized by a higher number of nouns. These differences may influence not only the prevalence of words repeated in VS (Alam et al., Reference Alam, Rosemberg, Garber and Stein2022; Tal & Arnon, Reference Tal and Arnon2018) but also the type of words children access (Rosemberg et al., Reference Rosemberg, Alam, Audisio, Ramírez, Garber and Migdalek2020), potentially shaping their learning paths.
Despite the role VS may play in shaping children’s vocabulary trajectories, no previous studies have examined whether the quantity of VS focused on a particular type of content word (verb, noun, or adjective) is related to the language typology of the community or the socioeconomic circumstances that characterize children’s early socialization. To address this, the present paper examines the proportion of VS in CDS (compared to ADS) and their focus on different lexical categories. The data for this study come from naturalistic corpora collected in low-and middle-socioeconomic households in two communities that differ in the language spoken, Argentinian Spanish and North American English. To this end, we review research on (a) VS’ characteristics, (b) how socioeconomic circumstances contribute to the proportion of VS in children’s communicative environments, and (c) linguistic and contextual factors that may be related to the proportion of VS focused on different lexical categories. Based on this review, we present our research questions.
1.1. The characteristics of variation sets
VS were first defined by Küntay and Slobin (Reference Küntay, Slobin, Slobin, Gerhartd, Kyratzis and Guo1996) as interactional sequences addressed to the child with a particular communicative intention, where a repeated word is wrapped with various surrounding words across utterances. As such, variability and repetition work together to promote child comprehension by gradually introducing new content, within a short time frame, around a stable lexical or conceptual point.
The sequences involve three types of phenomena: lexical substitution and rephrasing, addition or deletion of specific reference, and reordering. Küntay and Slobin (Reference Küntay, Slobin, Slobin, Gerhartd, Kyratzis and Guo1996, Reference Küntay and Slobin2002) extensively discussed how these phenomena may support children’s morphological, lexical, and syntactic development. To grasp the meaning and uses of verbs, nouns, or adjectives, children collapse across the VS and extract the relevant elements from the sets of syntactic frames in which these types of words occur. They track lexical roots across positions and morpheme combinations, moving in and out of patterns of ellipsis and uncovering inflectional paradigms in diverse syntactic structures. These provide surface cues that lead children towards the formal and functional properties of repeated elements. Thus, cues for grammatical analysis in CDS are not encountered directly but emerge through discourse-mediated patterns within social interaction.
To make a substantial impact on language acquisition, VS should appear regularly in children’s early interactions. Küntay and Slobin’s (Reference Küntay, Slobin, Slobin, Gerhartd, Kyratzis and Guo1996) first finding of the prevalence of VS in the speech directed to a Turkish toddler was replicated in different languages, such as English, Spanish, Hebrew, Chintang, and Swedish: approximately 20% of the utterances addressed to the child are structured as VS (Alam et al., Reference Alam, Rosemberg, Garber and Stein2022; Tal & Arnon, Reference Tal and Arnon2018; Waterfall, Reference Waterfall2006; Waterfall et al., Reference Waterfall, Sandbank, Onnis and Edelman2010; Wirén et al., Reference Wirén, Nilsson Björkenstam, Grigonytė and Cortes2016).
Naturalistic and experimental studies have shown that VS are linked to language outcomes (Onnis et al., Reference Onnis, Waterfall and Edelman2008; Schwab & Lew-Williams, Reference Schwab and Lew-Williams2016; Waterfall, Reference Waterfall2006; Waterfall et al., Reference Waterfall, Sandbank, Onnis and Edelman2010). Waterfall (Reference Waterfall2006) found that the inclusion of certain verbs and multiword constituents in VS predicts their later appearance in children’s production. Evidence from two-year-old children suggests that repeated words in adjacent sentences are more likely to be learned than those distributed throughout the entire input (Schwab & Lew-Williams, Reference Schwab and Lew-Williams2016). Onnis et al. (Reference Onnis, Waterfall and Edelman2008) showed that adults exposed to utterances structured in VS performed better in a word segmentation task than those hearing the same utterances not structured as VS. Additionally, Onnis et al. (Reference Onnis, Esposito, Venuti and Edelman2021) found that mothers used VS with atypical children with low cognitive abilities at older ages than typically developing children, likely to enhance engagement in the interaction.
Studies using manual coding and automatic algorithms to extract VS have analysed CDS in different languages (Hebrew, English, Chintang, Spanish, Turkish, Swedish). Only Lester et al. (Reference Lester, Moran, Aylin, Allen, Pfeiler and Stoll2022) compared child-surrounding speech with ADS as a baseline in English and Chintang. Results revealed cross-linguistic similarities in how prevalent VS are. Nonetheless, some differences in the proportion of VS as well as in their pragmatic function in child-directed interactions emerged across socioeconomic groups speaking the same language (Alam et al., Reference Alam, Rosemberg, Garber and Stein2022; Tal & Arnon, Reference Tal and Arnon2018).
1.2. Socioeconomic circumstances’ relation to the proportion of words in variation sets in children’s communicative environments
Why might the socioeconomic circumstances of children’s households affect the quantity and use of VS in CDS? Naturalistic studies in North America (Sperry et al., Reference Sperry, Sperry and Miller2019) and Argentina (Alam et al., Reference Alam, Ramirez and Migdalek2021; Rosemberg et al., Reference Rosemberg, Alam, Audisio, Ramírez, Garber and Migdalek2020; Stein et al., Reference Stein, Menti and Rosemberg2023) revealed that multiple interlocutors, including adults and children, as well as overheard speech (OHS) and bystander talk, shape verbal environments in low-SES households. Unlike middle-SES households, low-SES households often include large families with fewer child-centred activities, and children have less access to toys and other child-specific objects (Bradley & Corwyn, Reference Bradley and Corwyn2002; Rosemberg et al., Reference Rosemberg, Alam, Ramírez and Ibañez2023). Children share activities with peers and adults, and input may more often stem from multi-speaker interaction (Alam et al., Reference Alam, Ramirez and Migdalek2021; Sperry et al., Reference Sperry, Sperry and Miller2019).
Consistent with the aforementioned differences in the ebb and flow of daily life in diverse social groups, Tal and Arnon (Reference Tal and Arnon2018) and Alam et al. (Reference Alam, Rosemberg, Garber and Stein2022) provide evidence of an increased use of VS at the very local interactional level in middle-SES households relative to low-SES households. As shown by Alam et al. (Reference Alam, Rosemberg, Garber and Stein2022), child-centred social activities, including book readings as well as organized play with objects, prevalent in middle-SES households, predict both the quantity of VS and their referential use in joint attention contexts to comment on, or elicit information about, the shared focus. Conversely, VS in sequences of interactions aimed to command children’s actions predominate in child solitary activities, more frequent in low-SES households.
1.3. Linguistic and contextual factors that may affect the proportion of variation sets focused on different lexical categories
Comparative research across languages and communities has provided evidence that both the contextual affordances in which the children experience language and specific typological properties of the language of their community may impact the salience of morphosyntactic information in utterances, thus influencing language development.
Certain typological features may influence children’s exposure to content words (Choi, Reference Choi2000; Tardif et al., Reference Tardif, Shatz and Naigles1997; among others). In pro-drop languages, such as Spanish, the grammatical information in verb inflection expresses the subject and allows noun omission; therefore, verbs are more salient than nouns because fewer noun phrases are necessary to communicate the same meaning than in non-pro-drop languages, such as English. In Spanish, word order is relatively flexible; unlike English, verbs can be placed at the beginning or the end of utterances. The relative salience of each type of word may influence vocabulary acquisition. Several studies have established a quite steady association between the quantity of nouns and verbs in CDS and children’s early vocabularies, with a bias towards noun types in non-pro-drop languages, for example, in English, and towards verbs in pro-drop languages, such as Mandarin, Korean, Cantonese, and Tzotzil (De León, Reference De León, Bowerman and Levinson2001; Leung, Reference Leung1998; Tardif et al., Reference Tardif, Shatz and Naigles1997). Yet, studies of Hebrew, Italian, Spanish, Chintang, Japanese, French, and Turkish have failed to find conclusive evidence of the proposed relationship (Adi-Bensaid et al., Reference Adi-Bensaid, Ben-David and Tubul-Lavy2015; Altınkamış et al., Reference Altınkamış, Kern and Sofu2014; Camaioni & Longobardi, Reference Camaioni and Longobardi2001; Jackson-Maldonado et al., Reference Jackson-Maldonado, Peña, Aghara, Nieto and Jackson-Maldonado2011; Ogura et al., Reference Ogura, Dale, Yamashita, Murase and Mahieu2006; Stoll et al., Reference Stoll, Bickel, Lieven, Paudyal, Banjade, Bhatta, Gaenszle, Pettigrew, Rai, Rai and Rai2012).
Other factors than language typology should be considered to explain the composition of input and early vocabularies. As discussed previously, the particular physical, social, and interactional contexts also condition how information is structured and reflected in the way words and utterances are organized. In Rosemberg et al.’s (Reference Rosemberg, Alam, Audisio, Ramírez, Garber and Migdalek2020) study, Argentinian toddlers were exposed to a different proportion of nouns and verbs regarding pragmatic and contextual dimensions associated with their socioeconomic circumstances. Although Spanish was shared by all the families as the common language, the proportion of noun versus verb types was slightly higher in middle-SES households than in low-SES households, particularly in CDS. Conversely, the speech overheard by low-SES children contained a greater proportion of noun types, probably due to overlapping conversations between multiple participants tackling a variety of topics in diverse activities. The fact that middle-SES families have fewer members than low-SES might imply fewer surrounding conversations and fewer nouns to introduce conversational topics. Additionally, the differences in the pragmatics of VS in the microcontext of everyday activities may affect the proportion of VS focused on different lexical categories. Consistent with documented differences in conversational style across SES groups (e.g. Hoff, Reference Hoff2003; Sperry et al., Reference Sperry, Sperry and Miller2019), the greater frequency of VS aimed at commanding actions in low-SES households may involve the repetition of a larger proportion of verbs than nouns. In contrast, VS that expand and elaborate linguistic content in middle-SES households may more often involve the repetition of nouns or adjectives, thereby shaping both the quantitative and qualitative dimensions of children’s exposure to different lexical categories.
It is necessary to take into account that the diverse macro- and micro-social indicators considered or related to the SES index – adults’ income, parents’ education, household density, housing, and the availability of objects – condition children’s living circumstances to a varying degree across countries (Bradley & Corwyn, Reference Bradley and Corwyn2002). This, in turn, may affect how the specific language spoken in the community is deployed in the structure of local interactions in which the child is involved. These interactions are the fabric into which language is embedded and the source from which children can learn the linguistic categories during the socialization process (Rosemberg et al., Reference Rosemberg, Alam, Audisio, Ramírez, Garber and Migdalek2020; Rowe & Weisleder, Reference Rowe and Weisleder2020). However, to our knowledge, there is no previous study that has examined at the local level of interactions whether the quantity of VS and their focus on a certain class of content words (verb, noun, or adjective) are jointly related to SES and the language of the community.
1.4. The present study
The research reviewed above has revealed how VS structure the speech directed to children from different language communities. Only one study has provided evidence of the pre-eminence of VS in CDS as compared to ADS (Lester et al., Reference Lester, Moran, Aylin, Allen, Pfeiler and Stoll2022). Two particular studies (Alam et al., Reference Alam, Rosemberg, Garber and Stein2022; Tal & Arnon, Reference Tal and Arnon2018) have shown SES effects on the quantity of VS in CDS. Despite analysing CDS in a variety of languages, none of these studies have examined whether typological differences of the language – specifically its pro-drop versus non-pro-drop status – are associated with caregivers’ production of VS primarily focused on a certain lexical category. Nonetheless, cross-linguistic research (e.g. Tardif et al., Reference Tardif, Shatz and Naigles1997) has shown differences in the quantity of nouns and verbs that children from different communities are exposed to depending on whether their community speaks a pro-drop language or not. Additionally, the lexical composition of CDS can also be affected by the types of activities and the interactional patterns that characterize the household environments of children living in different socioeconomic circumstances (Rosemberg et al., Reference Rosemberg, Alam, Audisio, Ramírez, Garber and Migdalek2020, Reference Rosemberg, Alam, Ramírez and Ibañez2023).
Taken together, results jointly raise the question of whether both the language spoken in the community and SES are related to the prevalence of VS in CDS and their focus on different lexical categories. This inquiry may be particularly pertinent in light of evidence linking the lexical composition of CDS to children’s early lexical development and highlighting the role of VS in supporting children’s learning (Onnis et al., Reference Onnis, Waterfall and Edelman2008, Reference Onnis, Esposito, Venuti and Edelman2021). Hence, the present investigation examines this topic in naturalistic corpora collected in low- and middle-SES households of infants and toddlers learning either North American English – a non-pro-drop language – or Argentinian Spanish – a pro-drop language. We seek to address the following questions:
-
˗ Are VS more characteristic of CDS than of ADS?
-
˗ How does SES relate to the prevalence of VS in CDS in Argentinian Spanish and North American English, as indexed by (a) the proportion of words in VS, (b) the proportion of utterances in VS, and (c) the proportion of turns containing VS?
-
˗ Are there differences in the proportion of VS in CDS anchored in different lexical categories (nouns, verbs, and adjectives), and do these differences vary by community language? Does SES moderate these cross-linguistic differences?
Based on previous studies, we formulated a set of a priori hypotheses corresponding to the associations and interactions tested in our models. First, in line with Lester et al. (Reference Lester, Moran, Aylin, Allen, Pfeiler and Stoll2022), we hypothesized that VS would be a more characteristic feature of CDS than of ADS. ADS was included only as a contrast register to establish differences in the overall occurrence of VS, as existing research does not provide a theoretical basis for predicting lexical-category-specific patterns in VS in ADS. All subsequent hypotheses focused only on CDS.
Within CDS, we expected a greater proportion of words and utterances included in VS as well as a higher proportion of turns including VS in middle-SES than in low-SES in both Argentinian and North American households (Alam et al., Reference Alam, Rosemberg, Garber and Stein2022; Tal & Arnon, Reference Tal and Arnon2018). Given evidence that the lexical composition of CDS differs across pro-drop and non-pro-drop languages (Tardif et al., Reference Tardif, Shatz and Naigles1997), we hypothesized an interaction between the language of the community and the lexical category, such that the quantity of VS anchored in nouns, verbs, and adjectives would differ according to the language spoken in the community. Because caregivers’ interactional patterns and the types and frequency of everyday activities vary systematically across socioeconomic circumstances (Rosemberg et al., Reference Rosemberg, Alam, Audisio, Ramírez, Garber and Migdalek2020; Rowe & Weisleder, Reference Rowe and Weisleder2020; Sperry et al., Reference Sperry, Sperry and Miller2019), we further expected a three-way interaction involving SES, lexical category in CDS, and language of the community. Finally, given well-established developmental changes in CDS, child age was included as a control variable across all these hypotheses.
2. Method
2.1. Corpus
The data analysed in this study consist of 101 long-form audio recordings of infants’ and toddlers’ naturalistic household environments, included mostly in a singular cross-cultural meta-corpus, Analyzing Child Language Experiences around the World (ACLEW, Soderstrom et al., Reference Soderstrom, Casillas, Bergelson, Rosemberg, Alam, Warlaumont and Bunce2021). Even though each corpus was initially collected to fulfil specific research objectives, all of them share the intention to capture infants’ everyday, real-world experiences using long-form audio methods. However, they differ in the length per participant as well as the number, gender, age, and SES of the participants recorded. To examine the prevalence of VS in CDS compared to ADS and to assess whether SES and the language of the community are associated with (a) the proportion of child-directed words and utterances included in VS, (b) the proportion of turns containing VS, and (c) the lexical categories in which they are anchored, we analysed naturalistic recordings from two culturally and linguistically specific populations, North America and Argentina. The sample comprised 51 Argentinian Spanish-speaking families from Buenos Aires (Rosemberg et al., Reference Rosemberg, Alam, Stein, Migdalek, Menti and Ojea2015) and 50 North American English-speaking families coming from three different corpora: 13 recordings from Winnipeg, Canada McDivitt & Soderstrom (Reference McDivitt and Soderstrom2016), and the rest from the United States (17 from California and 20 from New York) (Bergelson, Reference Bergelson2016; Warlaumont et al., Reference Warlaumont, Pretzer, Mendoza, Schneider, Mutrie, Lopez, Walle and Kello2024).
Age, gender, and SES were used as parameters to select the specific audio recordings to be analysed. We included only monolingual families representing both ends of the SES spectrum, indexed by mother education. The middle-SES group was composed of families in which at least one of the parents has completed a university degree or similar (e.g. a teaching degree), which translates into at least four years of further education after secondary school. In contrast, in low-SES families, adults had at most completed secondary school. SES groups were balanced in terms of age (months): Argentinian children – low SES, M = 17.08 (SD = 4.88); middle SES, M = 15.59 (SD = 5.81); North American children – low SES, M = 9.94 (SD = 5.27); middle SES, M = 8.69 (SD = 4.14). Spanish was the first language and the one used in everyday interactions in all the Argentinian families, and English in the North American sample.
2.2. Procedures
2.2.1. Data collection
The Argentinian and North American data were collected following a similar procedure: caregivers were asked to have their children wear vests equipped with digital devices in order to record every natural interaction (at home or during occasional outings) without the presence of the researcher. Families were asked to interact as they normally would. Interactions were audio-recorded for a period that lasted between four and sixteen hours.
2.2.2. Sampling procedure
In the ACLEW project, thirty minutes of each audio recording were selected using one of two sampling procedures:
-
1) We randomly selected 15 2-minute segments from 26 Argentinian children and 27 North American children. For each 2-minute segment, the 2 preceding minutes and the 1 minute following were considered as context. The only restriction on the segment selection was that the 5 minutes of the 15 segments could not overlap. This periodic sample of the language environment gives a representative picture of variation in children’s language experiences over the course of a day at home.
-
2) We selected 15 high-volubility 2-minute segments corresponding to 23 additional recordings from the North American sample and 25 from the Argentinian corpus. Each of these recordings corresponded to a child that matched one of the children in the random sample in age, gender, and mother’s education. Additionally, we excluded any participants living in the same home. The high-volubility segments were identified using a 2-step process. First, a custom automated process was used to identify segments in the recordings that potentially contained a high density of speech. Second, these regions were roughly assessed by trained annotators to determine whether the clip met the selection criteria related to child vocalizations and amount of adult speech. Segments that exclusively include electronic media were discarded. Each of the segments was vetted according to the following criteria: (a) it included at least five target-child vocalizations (canonical and non-canonical babbling or speech; not crying, laughing, or eating-related sounds) that corresponded to the target child; (b) it contained at least five adult–child or child–adult turns. A turn was defined as an adult speaking followed within 2 seconds by a vocalization from the target child or vice versa; (c) to be included, the second speaker’s utterance had to be temporally and pragmatically related to the preceding utterance; (d) the segment included at least five near and clear adult vocalizations (any adult). This sampling method provides a sample composed of interactional data designed to capture periods of sustained, reciprocal interaction.
In the present study, we included both sampling types in accordance with the standardized ACLEW protocol, which was applied consistently across all corpora. Because the same selection criteria were used for all participants, including both random and high-volubility segments, this ensures comparability across communities without introducing differential sampling bias. In the analyses, sampling type was included as a covariate to account for potential differences in interactional density.
2.2.3. Transcription and coding
The 50.5 sampled hours were annotated using the ELAN software (Wittenburg et al., Reference Wittenburg, Brugman, Russel, Klassmann, Sloetjes, Calzolari, Choukri, Gangemi, Maegaard, Mariani, Odijk and Tapias2006) and transcribed using an adaptation of the CHATFootnote 1 format (Codes for Human Analysis of Transcripts, MacWhinney, Reference MacWhinney2000). The speech was segmented into utterances. To segment utterances, we considered interactional structure (e.g. turn-taking), a pause longer than 2 seconds, prosodic contour, and the syntactic structure.
To guarantee transcription reliability, a second coder rechecked for word orthographic accuracy, utterance segmentation, and speaker and addressee coding (see below) and reviewed fragments that were less intelligible due to the presence of multiple speakers, electronic speech, or outdoor settings.
Each of the selected segments was annotated using the full ACLEW Annotation Scheme (https://osf.io/b2jep/, Casillas et al., Reference Casillas, Bunce, Soderstrom, Rosemberg, Migdalek, Alam, Stein and Garrison2017; Soderstrom et al., Reference Soderstrom, Casillas, Bergelson, Rosemberg, Alam, Warlaumont and Bunce2021). This system, implemented in ELAN, was developed jointly across the contributing laboratories. It structures the segmentation of speech as well as the tagging of children’s linguistic environment and their own vocal maturity, allowing for consistency across the laboratories.
Research assistants across all sites were trained according to a unified protocol. Training materials consisted of a set of tutorials, developed by the research team, covering the basics of ELAN, the ACLEW DAS coding conventions, and the adaptation of the CHAT format used in the project. This tutorial was designed to assess research assistants’ readiness to apply the ACLEW DAS to real data. This training process ensured that all research assistants have received standardized training and are being held to as consistent performance standards as possible across coders and labs.
The assessment included a series of gold standard training and test files in both English and Spanish, against which research assistants were compared. Each gold standard file was initially annotated and transcribed separately by two experienced annotators who then produced a consensus file. This consensus file was subsequently reviewed by two supervisory annotators to generate a gold standard file. Prior to annotating the project data, all research assistants were required to pass the gold standard tests in both Spanish and EnglishFootnote 2. The tests included the use of a web app developed to automate comparison to the gold standard (https://github.com/aclew/ACLEW-GoldStandard). The application computes segmentation overlap and tag-level accuracy and generates a weighted score indicating whether the trainee has passed, as well as an error report indicating specific discrepancies.
For the present study, we consider only two elements of the ACLEW DAS: the coding of the speaker (adult/child/unknown, male/female/unknown) and the addressee of the utterance (the target child, a non-target child, adult, mixed-age, animal, other, unknown). The reliability protocol called for a second naive annotator to apply the coding to a 1-minute randomly selected segment.Footnote 3
To analyse the morphological composition of the utterances in the sample that allowed the identification of nouns, verbs, and adjectives, CLAN’s MOR tool (MacWhinney, Reference MacWhinney2000) was used.
2.2.4. Automatic extraction of variation sets
The development of tools for automatic extraction made possible the analysis of VS in large corpora of speech (Brodsky et al., Reference Brodsky, Waterfall, Edelman, McNamara and Trafton2007; Li & Onnis, Reference Li and Onnis2022; Waterfall et al., Reference Waterfall, Sandbank, Onnis and Edelman2010; Wirén et al., Reference Wirén, Nilsson Björkenstam, Grigonytė and Cortes2016). The first algorithm developed by Brodsky et al. (Reference Brodsky, Waterfall, Edelman, McNamara and Trafton2007) compares the degree of dissimilarity that successive strings show. According to Levenshtein (Reference Levenshtein1966), the distance between two strings was established considering the number of edit operations required to transform one utterance into another. Wirén et al.’s (Reference Wirén, Nilsson Björkenstam, Grigonytė and Cortes2016) algorithm is also based on the comparison of strings. It accepts as part of VS exact verbal repetitions, considering the fact they may still show variation in prosodic or in the non-verbal cues accompanying them. Their algorithm allows up to two intervening utterances and interventions from the child.
In line with the aforementioned studies, our working definition considers VS as a sequence within an interactional unit composed of two or more consecutive utterances directed either to the target child or to an adult, where the second utterance partially repeats the previous one (see below). We developed an automatic algorithm for VS extraction (Garber, Reference Garber2019) that, instead of comparing strings, parses MOR tiers from CLAN’s CHAT files (MacWhinney, Reference MacWhinney2000). This increases its precision and, at the same, time allows for the comparison of noun, verb, and adjective lexemes in the successive utterances.
The nouns identified included common nouns and kinship terms. Proper names were excluded. Adjectives were all included. The verb category included all the main verbs, referring to physical and mental actions. Copulas and auxiliaries – for example, those that make up compound verbs – were excluded. For instance, in the case of Spanish periphrastic verbs such as tiene que comer “she has to eat,” está comiendo “she is eating,” va a comer “she is going to eat,” we included the non-finite verb forms (i.e. infinitives, gerunds, and participles), as they contribute the most to the meaning of the construction. In contrast, the auxiliary verb only conveys grammatical information and certain meanings that qualify the action (RAE, 1983). Similarly, in English phrases like “has to eat,” “is eating,” or “is going to eat,” we included the non-finite verb forms (i.e. infinitives, gerunds, and participles). In Argentinian Spanish we have the verb dale , whose literal translation would be “give her” but which is commonly used as “come on” or “ok”; this word was also excluded as it is highly repeated in everyday talk. Similarly, in English, we excluded let us.
Given the specificity of naturalistic data, where several speakers participate and overlap their speech, following Wirén et al. (Reference Wirén, Nilsson Björkenstam, Grigonytė and Cortes2016), our working definition of VS allowed, in the case of CDS, one intervening utterance from the child, one utterance from the speaker that did not have a word in common with the sequence of variation set, one intervention from another speaker directed to the child, as well as three other overlapping interventions not addressed to the child, all in a time frame under 5000 ms. In the case of VS in ADS, the algorithm allowed, also in a time frame under 5000 ms, one intervention from the speaker to another adult that did not have words in common with the VS and up to three utterances from another speaker not directed to the child, as well as one intervening utterance from another speaker directed to the child.
2.2.5. Quantitative measures of variation sets
Considering that the proportion of CDS and ADS in household linguistic environments can vary according to different socioeconomic contexts (Rosemberg et al., Reference Rosemberg, Alam, Audisio, Ramírez, Garber and Migdalek2020; Stein et al., Reference Stein, Menti and Rosemberg2023) and language communities (Lester et al., Reference Lester, Moran, Aylin, Allen, Pfeiler and Stoll2022), we measured the prevalence of VS in household linguistic environments by comparing the proportion of word tokens included in VS in CDS and ADS. Then, in light of previous research showing the impact of speech directly addressed to children for language development (e.g. Soderstrom, 2007), we focused on VS in CDS.
Following previous research (Alam et al., Reference Alam, Rosemberg, Garber and Stein2022; Tal & Arnon, Reference Tal and Arnon2018), we assessed VS’ prevalence in CDS, taking into account the proportion of words and utterances in VS. Given that the utterance length could have an effect on both words in VS and utterances in VS, we controlled this effect through a third measure, the proportion of turns in CDS that include VS. Secondly, to estimate SES and language community effects in the amount of VS anchored in different lexical categories, we calculated the proportion of VS that repeat verbs, nouns, and adjectives over the total amount of VS for each child. We also considered differences in the proportion of VS anchored in each lexical category. In cases where a VS was anchored in both a noun and a verb, the set was counted separately for each lexical category. To calculate this last proportion, we considered the total number of tokens in each lexical category.
2.3. Data analysis
All statistical analyses were conducted in R with the betareg package (Cribari-Neto & Zeileis, Reference Cribari-Neto and Zeileis2010; R Core Team, 2017), and all figures were generated with ggplot2 (Wickham & Wickham, Reference Wickham2016). Beta regression was chosen as the primary statistical approach because it is specifically designed to model dependent variables that are proportions or rates bounded between 0 and 1. To meet the assumptions of beta regression, the dependent variables were transformed to ensure they fell strictly within the (0, 1) interval using min–max normalization and adjusted using the transformation (y(n − 1) + 0.5)/n proposed by Cribari-Neto in the betareg package documentation to avoid boundary values, which were nonetheless very infrequent in the dataset. This adjustment prevents issues related to boundary values (0 and 1), which are not supported by the beta distribution. Beta regression models not only estimate the mean of the dependent variable but also incorporate a precision parameter (phi) to account for potential heteroscedasticity or overdispersion in the data. This precision parameter models the variability of the dependent variable, allowing for a more flexible and accurate representation of the data structure. In our analyses, we used a variable dispersion model to account for potential differences in variability across groups or conditions, ensuring that the precision parameter was appropriately estimated for each subset of the data.
3. Results
3.1. Descriptive analysis
We begin by providing an overview of the entire CDS dataset for each language community and SES in Table 1, along with a description of the VS found within CDS.
Mean number and standard deviation of utterances, total words, nouns, verbs, and adjectives, VS, utterances and words in VS, and noun-based, verb-based, and adjective-based VS in CDS per 30-minute recording, across children, by language community, and SES. Note that these descriptive statistics combine data from the random and the high-volubility sample

Table 1. Long description
Mean Number and Standard Deviation of utterances, total words, nouns, verbs, and adjectives, variation sets, utterances and words in variation sets, and noun-based, verb-based, and adjective-based variation sets in CDS per 30-minute recording, across children, by language community, and SES. Note that these descriptive statistics combine data from the random and the high-volubility sample.
On average, children from middle-SES backgrounds in the Spanish-speaking community hear more words, utterances, nouns, verbs, and adjectives addressed to them in CDS than their low-SES counterparts. These SES differences are also reflected at the micro-level of interactions, specifically in the VS included in CDS. In contrast, no systematic differences are observed in CDS or in the quantitative characteristics of VS in the English-speaking community.
Table 2 reports the quantity of words and utterances in ADS for each language community and SES, along with the quantity of VS and the proportion of words and utterances included in the VS in ADS.
Mean number and standard deviation, total words, VS, and utterances and words in VS in ADS per 30-minute recording across children, by language community, and SES. Note that these descriptive statistics combine data from the random and the high-volubility sample

Table 2. Long description
The table is divided into two main columns: Spanish-speaking community and English-speaking community. Each community is further subdivided by Socioeconomic Status (S E S) into Low and Middle groups.
For the Spanish-speaking community:
* Low S E S (N = 24): All A D S Utterances mean 227.25 (sd 143.81), Words mean 634.12 (sd 478.93). V S mean 6.00 (sd 4.98), Utterances in V S mean 13.41 (sd 10.80), Words in V S mean 89.16 (sd 75.38).
* Middle S E S (N = 27): All A D S Utterances mean 130.15 (sd 98.53), Words mean 451.52 (sd 373.52). V S mean 4.25 (sd 4.37), Utterances in V S mean 9.70 (sd 9.76), Words in V S mean 71.70 (sd 76.87).
For the English-speaking community:
* Low S E S (N = 17): All A D S Utterances mean 257.00 (sd 201.76), Words mean 882.11 (sd 857.15). V S mean 3.47 (sd 3.12), Utterances in V S mean 7.94 (sd 7.51), Words in V S mean 64.64 (sd 71.10).
* Middle S E S (N = 33): All A D S Utterances mean 218.27 (sd 131.36), Words mean 761.48 (sd 535.94). V S mean 5.81 (sd 4.79), Utterances in V S mean 13.42 (sd 11.57), Words in V S mean 107.78 (sd 113.10).
As shown in Table 2, in the Spanish-speaking community, the number of words, utterances, and VS is higher in the ADS in low-SES households than in middle-SES households. In the English-speaking community, the pattern is similar, though less pronounced. However, the distribution of data for VS in the English-speaking community is the opposite: ADS in middle-SES households exhibits a greater number of VS, which include a greater quantity of words and utterances.
3.2. Regression analysis
To address our three research questions, we fitted a series of beta regression models. Across all models, SES (low/middle), language of the community (English/Spanish), lexical category (noun/verb/adjective), register (CDS/ADS), sampling type (random/high volubility) were included as dummy-coded factorial variables. Reference levels were low SES, English for the language of the community, noun for lexical category, ADS for register, and high volubility for sampling type. We only included interactions between these factors when we had a strong a priori hypothesis. In all models, age was included as a covariate (centred and standardized from age in months).
To assess the sensitivity of the fitted beta regression models, we conducted a simulation-based power analysis. Using the estimated coefficients from the fitted model, we generated 2000 Monte Carlo replicates of the response variable assuming a beta distribution parameterized by the model-implied mean and precision. For each simulated dataset, the model was refitted using the same specification, and Wald tests were computed for the coefficients of interest in the mean sub-model. Statistical power was estimated as the proportion of simulations in which the null hypothesis was rejected at the nominal significance level (α = 0.05). This procedure provides an estimate of the probability of detecting effects of the magnitude observed in the fitted model, given the sample size and distributional characteristics of the data.
-
1. To examine whether VS are more characteristic of CDS than of ADS, we specified a model in which register (CDS versus ADS) was the focal predictor, while SES, language (Spanish versus English), and age were included as covariates to account for potential confounding variation. Word_Proportion ~ SES + Register + Language + Age
-
2. To further investigate the impact of SES on the prevalence of VS in CDS, we implemented six beta regression models, three for each language community. The dependent variables in these models included: (a) the proportion of words in VS, (b) the proportion of utterances in VS, and (c) the proportion of turns including VS. The recordings from which the samples were drawn vary in length across participants and sampling procedures, introducing potential biases analogous to those observed in type–token ratio (TTR) measures. As corpus length increases, repetition of frequent items also increases, leading to lower TTR values; a similar effect may apply to the prevalence of VS. For this reason, all models included both recording length and sampling type (random versus high-volubility) as control variables. Sampling type was included to adjust for potential structural differences across samples. Importantly, all comparisons across registers, languages, and SES groups were conducted while holding these sampling-related factors constant. To account for multiple comparisons across the three outcome measures for each language, p-values were adjusted using a Bonferroni correction. Word_Proportion ~ SES + Age + Sampling + Recording Length; Utterance_Proportion ~ SES + Age + Sampling + Recording Length; Turn_Proportion ~ SES + Age + Sampling + Recording Length
-
3. Lastly, to address whether there are differences in the proportion of VS in CDS anchored in different lexical categories (nouns, verbs, and adjectives) and whether these differences vary by community language, as well as whether SES moderates these cross-linguistic differences, we implemented a beta regression model. Multilevel beta models including random intercepts for child yielded near-zero variance components and did not improve model fit. For reasons of parsimony and model stability, fixed-effects beta regression models are therefore reported. The dependent variable was the proportion of VS anchored in each lexical category, calculated as the number of VS anchored in nouns, verbs, or adjectives divided by the total number of VS in CDS. This specification allowed us to examine differences across lexical categories, cross-linguistic variation, and SES-related moderation, while controlling for age. VS_Proportion ~ (Lexical_Category * Language) + (SES: Lexical_Category: Language) + Age
3.2.1. Are VS more characteristic of CDS than of ADS?
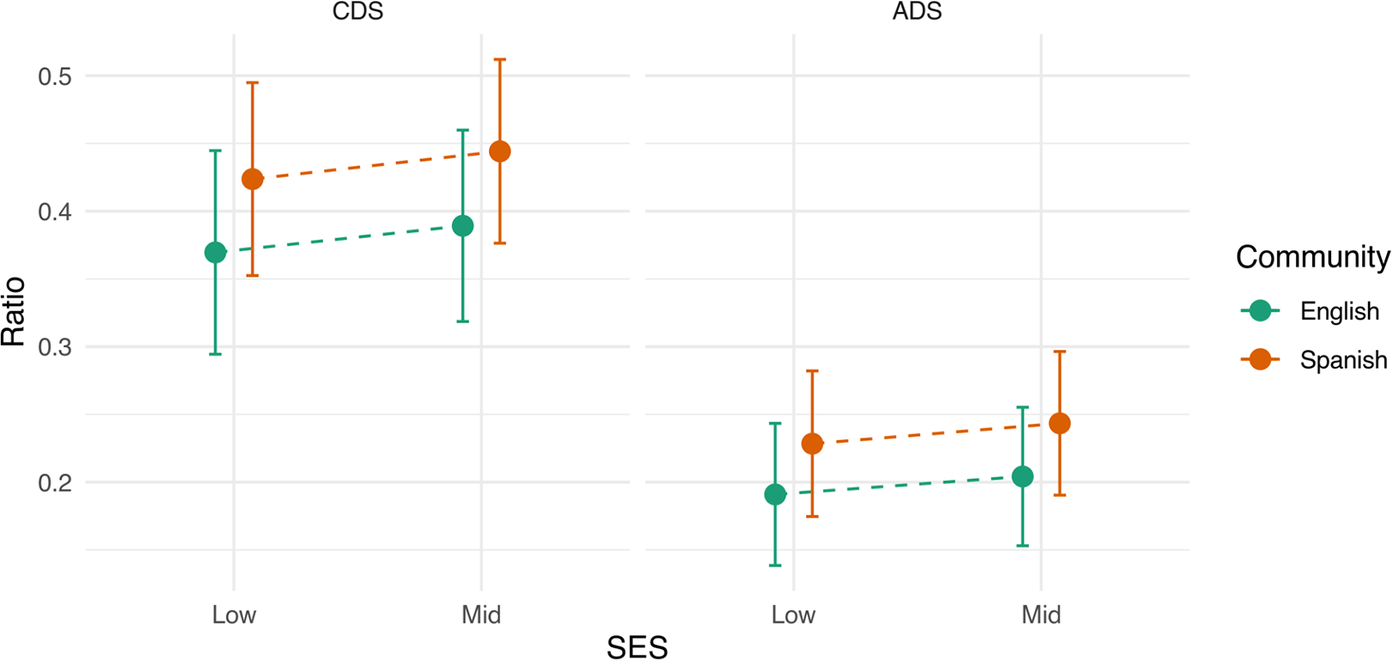
Figure 1 illustrates the proportion of words within VS as a function of the register (CDS versus ADS). The language of the community and SES were included as covariates. Within both language communities and across both social groups, the proportion of words in VS relative to those not in VS is higher in CDS than in ADS. Beta regression analysis yielded a significant effect of the register on the proportion of words within VS: CDS showed a significantly higher proportion of words in VS than ADS (see Table 3). According to the simulation-based sensitivity analysis described above, the fitted sub-model showed a very high probability of detecting effects of the observed magnitude (estimated power = 0.99). The precision sub-model also revealed higher precision values for the Spanish sample, suggesting greater consistency in the use of VS across observations in this language community.
Proportion of words aggregated by SES, community, and register (model-estimated marginal means).

Beta regression model predicting the proportion of words in CDS versus ADS

Table 3. Long description
Beta regression model predicting the proportion of words in CDS versus ADS. The interpretation of the regression table is provided below.
Note: *, **, and *** indicate statistical significance at the p < 0.05, p < 0.01, and p < 0.001 levels, respectively. The symbol − indicates a negative estimate/coefficient.
3.2.2. The prevalence of VS in CDS: SES differences
To examine the amount of CDS structured as VS in each SES group, we considered three different ratios: the proportion of child-directed words and of utterances included in VS, as well as the proportion of turns including VS. Age, as mentioned, recording length, and type of sampling – random or high volubility – were included as covariates in all the models. To account for multiple comparisons across the three outcome measures, p-values were adjusted using a Bonferroni correction.
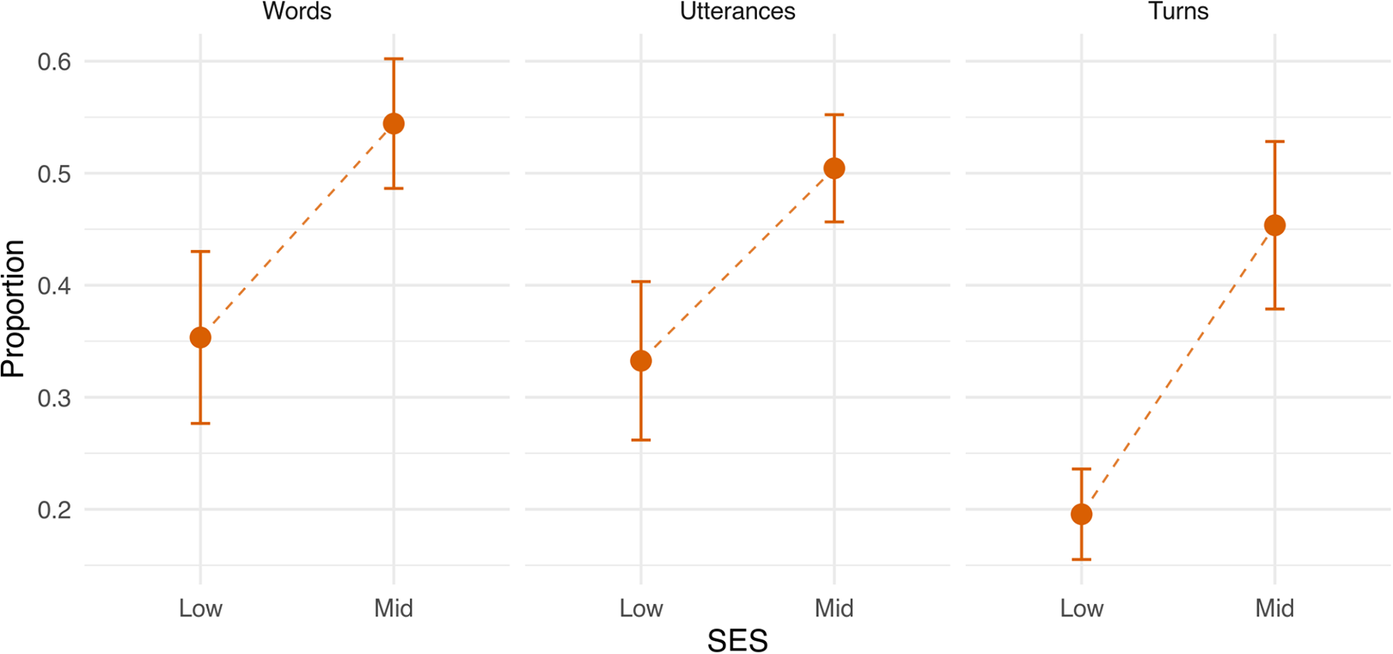
As shown in Figure 2, CDS in middle-SES Argentinian households tended to include a higher prevalence of VS than those addressed to children in low-SES households. This tendency was observed across the three measures, with middle-SES CDS showing higher estimated proportions of words, utterances, and turns including VS. The sensitivity analysis indicated a high probability of detecting the estimated effect (average power = 0.98). Child age was positively associated with the proportion of utterances in VS (power = 0.71, moderate probability of detecting the estimated effect). Recording length emerged as a significant predictor only for the proportion of turns including VS (power = 0.79, moderate probability of detecting the estimated effect) (Table 4).
VS ratios aggregated by SES for Argentinian Spanish community (model-estimated marginal means).

Beta regression models predicting the proportion of words and utterances in VS and of VS within turns in Argentinian Spanish CDS

Table 4. Long description
Beta Regression models predicting the proportion of words and utterances in variation sets and of variation sets within turns in Argentinian Spanish CD. The interpretation of the regression table is provided below.
The precision sub-model indicated differences in variability associated with SES. Specifically, dispersion in the proportion of utterances was greater in low-SES CDS, whereas dispersion in the proportion of turns including VS was higher in middle-SES CDS. This sub-model also revealed a sampling-type effect restricted to the proportion of turns including VS, with random samples showing higher precision values (Table 4).
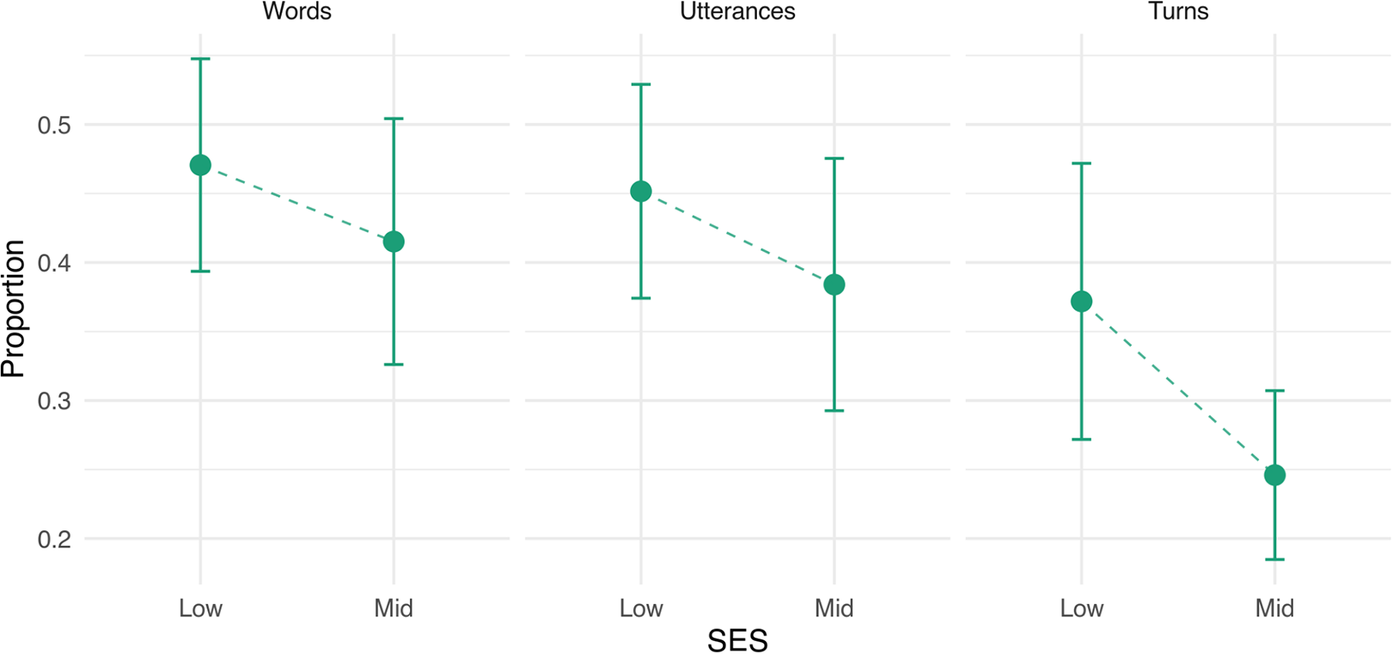
Figure 3 and the regression analysis reported in Table 5 point to a different result in the North American English community. Low-SES households showed higher estimated values across all three VS measures. However, SES differences did not reach statistical significance. In this language community, recording length was positively associated with all three measures of VS prevalence, with high probability for detecting effects of the observed magnitude (average estimated power = 0.81). The precision sub-model suggested greater dispersion in the proportion of words in VS and in the proportion of utterances including VS in middle-SES CDS compared to low-SES CDS. It also revealed greater dispersion in proportion of words when the sampling was random and in proportion of turns when the recordings were longer.
VS ratios aggregated by SES for North American English community (model-estimated marginal means).

Beta regression models predicting the proportions of words and utterances in VS and of VS in turns in North American English CDS

Table 5. Long description
Beta Regression models predicting the proportions of words and utterances in variation sets and of variation sets in turns in North American English CDS. The interpretation of the regression table is provided below.
3.2.3. Are there differences in the proportion of VS in CDS anchored in different lexical categories?
Figure 4 illustrates the distribution of VS anchored in each lexical category, nouns, verbs, and adjectives, in the CDS of low and middle-SES Argentinian Spanish-speaking and North American English-speaking households. In both language communities, VS were predominantly anchored in verbs, followed by nouns, and were rarely associated with adjectives.
Proportion of VS anchored within each lexical category, aggregated by community and SES (model-estimated marginal means).

A beta regression analysis was fitted to assess potential cross-linguistic differences in the proportion of VS anchored in different lexical categories and whether SES moderates these cross-linguistic differences (see Table 6). Results showed that adjective-based VS were less prevalent than those anchored in nouns, with the sensitivity analysis showing very high probability of detecting an effect of the observed magnitude (power = 0.98), particularly in Spanish CDS (power = 0.74, moderate probability), as depicted in Figure 4. Furthermore, the interaction between language community, SES, and lexical category showed a higher proportion of VS anchored in adjectives in middle-SES Spanish CDS compared to low-SES Spanish CDS (power = 0.7, moderate probability). The interaction between language community and lexical category also showed a marginally significant effect: VS that repeat verbs (as compared to VS repeating nouns) were more probable in the Spanish-speaking households than in those speaking North American English (power = 0.49, low probability). VS anchored in nouns in English CDS were less prevalent in the middle SES than in the low SES (power = 0.97, very high probability). This SES effect on noun VS was not observed in the Spanish-speaking community.
Beta regression models predicting the ratio of VS anchored in each lexical category

Table 6. Long description
Beta Regression models predicting the ratio of variation sets anchored in each lexical category. The interpretation of the regression table is provided below.
It is worth noting that the precision model also showed a positive main effect of age and a negative main effect of Spanish CDS. In Spanish-speaking households, VS anchored in verbs and nouns showed less dispersion in middle SES than low SES. On the contrary, in the English-speaking community, VS anchored in nouns and verbs showed higher dispersion in low-SES families than in the middle-SES households. The pseudo R2 showed a good fit (0.32).
4. Discussion
This study adopted a naturalistic perspective to investigate the use of VS in the speech addressed to children as compared to that directed to adults in two different linguistic communities, North American English and Argentinian Spanish, two languages that differ in their pro-drop status. We examined SES differences in VS in CDS – measured by the proportion of words and utterances including VS and by the proportion of turns containing VS – in each linguistic community. Additionally, we analysed whether the linguistic community was associated with the proportion of VS anchored in different lexical categories (nouns, verbs, and adjectives) and whether SES modulates these cross-linguistic patterns. In line with previous research (Küntay & Slobin, Reference Küntay, Slobin, Slobin, Gerhartd, Kyratzis and Guo1996, Reference Küntay and Slobin2002; Waterfall, Reference Waterfall2006; Wirén et al., Reference Wirén, Nilsson Björkenstam, Grigonytė and Cortes2016), our findings revealed that VS are a pervasive feature of speech addressed to young children and occur more frequently in CDS than in adult-directed conversations. To achieve a more fine-grained understanding of the microstructure of household linguistic environments, we compared the proportion of VS in speech directly addressed to children to that directed to adults in the same interactional contexts, allowing us to isolate differences attributable to register rather than to situational variation. This contrasts with prior work from Lester et al. (Reference Lester, Moran, Aylin, Allen, Pfeiler and Stoll2022), which has compared child-surrounding speech to ADS drawn from different interactional situations. Our analysis demonstrated that the positive relationship between CDS and VS holds cross-linguistically and across socioeconomic groups.
Consistently with previous analysis of CDS in a smaller sample of Argentinian naturalistic household environments (Alam et al., Reference Alam, Rosemberg, Garber and Stein2022) and in British and Hebrew interactions collected in brief play quasi-experimental situations (Tal & Arnon, Reference Tal and Arnon2018), the Argentinian CDS data revealed higher values across the three measures of VS – words, utterances, and interactional turns – in the middle-SES than in the low-SES households. Importantly, the inclusion of an additional measure in the present study – the proportion of interactional turns containing VS – yielded a similar SES pattern, indicating that these differences are unlikely to be driven by group differences in CDS utterance length. Results from the naturalistic North American English corpus, however, did not mirror the results from the Argentinian corpus, nor did they replicate previous findings from Tal and Arnon’s (Tal & Arnon, Reference Tal and Arnon2018) quasi-experimental study. In this corpus, SES-related differences were not statistically reliable.
What factors might account for these discrepancies between the Argentinian and North American samples analysed in this study? Macro- or micro-social indicators, such as housing conditions, household density, income level, activity types, and the availability of objects, which shape children’s everyday circumstances, may be differently associated with parental education – the proxy for SES used in this study – across populations. As Psaki et al. (Reference Psaki, Seidman, Miller, Gottlieb, Bhutta and Ahmed2014) note, although parental education is a central component of SES, its implications for access to resources are not uniform across contexts. Social, political, and cultural factors that structure societies in specific ways may moderate the relationship between parental education and proximal factors affecting children’s language experiences (Rowe & Weisleder, Reference Rowe and Weisleder2020). Consistent with this view, Frank et al. (Reference Frank, Braginsky, Yurovsky and Marchman2021) found that, although child vocabulary differed as a function of maternal education across 12 different language corpora, the magnitude of these differences varied substantially by country.
Taken together, our findings suggest that socially or culturally mediated differences may influence how the specific language spoken in the community is deployed in the structure of local interactions involving children. In the Argentinian sample, these dynamics were associated with a greater prevalence and stability of VS across dimensions in the middle-SES households. In contrast, in North American English households, low-SES CDS showed higher estimated mean values across all three measures of VS; however, these differences did not reach statistical significance. The precision sub-model, in turn, indicated greater variability in the proportion of words and utterances in VS, pointing to differences in how caregivers organize repetition and reformulation within interaction. Thus, while average levels did not differ reliably as a function of SES, the degree of variability around those averages did. Overall, these patterns indicate that SES-related variation in CDS may be shaped by distinct sociocultural and interactional ecologies across contexts, underscoring the need for future work that directly examines household composition, activity structure, and material resources in a comparative cross-cultural framework.
4.1. Variation sets and lexical categories
Given extant evidence on the impact of the lexical composition in CDS on children’s early lexical acquisition (Choi, Reference Choi2000; Tardif et al., Reference Tardif, Shatz and Naigles1997) and the role of VS in vocabulary development (Waterfall, Reference Waterfall2006) and supporting children’s learning (Onnis et al., Reference Onnis, Waterfall and Edelman2008, Reference Onnis, Esposito, Venuti and Edelman2021), we examined the proportion of VS anchored in different lexical categories.
Overall, across languages and SES groups, adjective-based VS were less frequent than those anchored in nouns and verbs. In our data, the proportion of adjective-based VS in the CDS addressed to Spanish-speaking toddlers was even lower than in the English CDS, with a significant difference between language communities. This pattern is consistent with the findings of Quiroga et al. (Reference Quiroga, Rosemberg and Alam2023), which show that adjectives are significantly less frequent than nouns and verbs in the CDS addressed to Spanish-speaking four-year-old children from different SES backgrounds. It also aligns with the optional nature of adjectives, where they typically function as noun modifiers, adding descriptive features or specifying referents in discourse (Di Tullio, Reference Di Tullio1997). Although adjectives in Spanish generally appear after the noun ( un perro pequeño, la muñeca nueva ), their position is flexible. This, along with their morphological variability, may make their structure less predictable than in English, where adjectives have a fixed position before the noun (“the small dog”, “the new doll”) and an invariant morphological form. These factors could contribute to explaining cross-linguistic differences in frequency of adjective-based VS in CDS.
Additionally, in the Spanish language community, verb-based VS were marginally more frequent than those anchored in nouns, a pattern that may be related to the pro-drop status of Spanish. The higher prevalence of verbs over nouns in Spanish is explained by its pro-drop nature, which allows for the omission of nouns, unlike English (Tardif, Reference Tardif, Shatz and Naigles1997). Thus, the ratio of verbs to nouns in children’s CDS tends to be higher (Rosemberg et al., Reference Rosemberg, Alam, Audisio, Ramírez, Garber and Migdalek2020), potentially increasing the likelihood of verbs being repeated in VS.
4.2. SES, language community, and VS based in different lexical categories
The interaction between lexical category, language community, and SES suggests that SES-related differences in households’ activities and pragmatic contexts may modulate the relationship between language typology and lexical category. Specifically, SES was associated with differences in the lexical anchoring of VS across communities. In the North American English sample, middle-SES CDS showed proportionally fewer noun-based VS relative to verb-based VS. In the Argentinian Spanish sample, middle-SES CDS showed a higher proportion of VS anchored in adjectives compared to low-SES CDS. In English, a non-pro-drop language in which subjects are not typically omitted, children are exposed to a higher ratio of nouns over verbs (e.g. Tardif et al., Reference Tardif, Shatz and Naigles1997). Against this background, the relative reduction of noun-based VS in middle-SES CDS suggests a shift towards lexical categories that are less dominant in the input. In the Argentinian Spanish community, no significant SES differences were found in the proportion of VS anchored in nouns and verbs. However, middle-SES CDS, as compared to low-SES CDS, showed a higher proportion of VS anchored in adjectives, which, as noted, are less frequent in Spanish CDS (Quiroga et al., Reference Quiroga, Rosemberg and Alam2023).
In both language communities, middle-SES caregivers may use lexical self-repetitions in different morphosyntactic contexts to clarify meanings, offering children richer information about how these linguistic forms can be combined and used, and supporting their understanding of these forms. As noted by Schwab and Lew-Williams (Reference Schwab and Lew-Williams2016) and Rowe and Weisleder (Reference Rowe and Weisleder2020), among others, middle-SES parents, compared to low-SES parents, are more likely to view their role as involving the transmission of skills and knowledge that prepare children for school. They often regard child rearing as an opportunity to scaffold children’s learning and tend to engage in more structured linguistic interactions. Consistent with this perspective, Küntay and Slobin (Reference Küntay, Slobin, Slobin, Gerhartd, Kyratzis and Guo1996, Reference Küntay and Slobin2002) suggest that caregivers may provide their children more frequent repetitions and reformulations to enhance comprehension when they perceive misunderstandings. While this interactional orientation appears across language communities, the linguistic resources through which it is realized may vary as a function of language-specific properties, particularly pro-drop versus non-pro-drop status, which may shape the lexical categories emphasized in VS. More broadly, these findings suggest that similarities in caregivers’ communicative goals across sociocultural groups may coexist with cross-linguistic differences in the linguistic pathways through which these goals are enacted in everyday interactions.
4.3. Limitations and future directions
While naturalistic home recordings provide ecologically valid data, they also have limitations. One key limitation is the absence of visual information, which could have offered further insights into how VS are woven into the micro-interactional structure of the pragmatic contexts of everyday activities and housing arrangements across different SES circumstances among the studied populations. Video recordings could have provided this missing information; however, they also come with constraints. Battery life limits extended recordings, and handheld cameras require an observer’s presence, potentially making the situation less natural. As Bergelson et al. (Reference Bergelson, Amatuni, Dailey, Koorathota and Tor2019) point out, even naturalistic video recordings without an observer can distort children’s everyday linguistic experience by inflating input measures of quantity and diversity, as well as influencing the types of words and syntactic structures used in interactions.
It is also important to note that these samples will not reflect the full diversity of culture and family experiences within Argentina and North America, nor have we measured or reported all the ways that these groups differ from each other. Therefore, our conclusions regarding the reasons for the group differences we have found must necessarily be preliminary in nature.
Another limitation is the potential for self-selection bias. Within each corpus, not all families consent to home recordings, which may affect generalizability. Additionally, as reported in the Results, recording length was significantly associated with some measures of VS prevalence. This indicates that methodological factors inherent to naturalistic corpora, such as differences in recording duration, can influence observed distributions. Importantly, however, these methodological considerations do not account for the overall pattern of SES-related differences across communities but rather highlight the need for careful cross-corpus comparison. The robustness of the present findings is further supported by the scope of the dataset, which comprised 50.5 hours of transcribed speech drawn from long-form recordings of 101 participants and analysed using both random and high-volubility sampling procedures.
5. Conclusion
To sum up, the results of this study help us to understand how social and linguistic factors shape the early language experiences through which children learn language. They provide evidence that SES and the language of the community influence how interlocutors organize the information for young children at the local level of interactions in household communicative environments. The partial self-repetitions of lexical items in successive utterances that constitute VS highlight some words over others (via self-repetitions of nouns, verbs, or adjectives in specific syntactic contexts). How language is deployed in interactions with children likely influences the language analysis that children perform and their language development trajectories, particularly in relation to the acquisition of different lexical categories.
Acknowledgements
We thank Elika Bergelson and Anne Warlaumont for contributing their datasets to this project. All authors have agreed to the byline order and to the submission of the manuscript in this form. Treatment of all subjects in this study was in accordance with ethical standards. We would like to especially thank the children and their families who participated in the recordings and made this research possible.
Funding statement
This work received funding from CONICET, Argentina’s National Research Council, granted to first author Celia Rosemberg, PIP 80/2015, PIP 702/21, and a MINCyT grant, PICT 02896/2019, and by the Social Sciences and Humanities Research Council of Canada (435-2015-0628, 869-2016-0003) and the Natural Sciences and Engineering Research Council of Canada (501769-2016-RGPDD) to Melanie Soderstrom.






 Open access

