




No CrossRef data available.
TESTING GOODNESS OF FIT BASED ON DENSITIES OF GARCH INNOVATIONS
Published online by Cambridge University Press: 15 March 2006
Abstract
Testing goodness (or lack) of fit for distributions of observable and nonobservable random variables is one of the main topics in statistics. When they exist, the corresponding density functions and their shapes allow researchers to easily recognize the underlying distribution functions. The present paper is concerned with the densities of (unobservable) generalized autoregressive conditional heteroskedasticity (GARCH) innovations and also with developing goodness-of-fit tests for the densities. Specifically, we construct and investigate large-sample properties of a kernel-type density estimator for GARCH innovations based on (observable) residuals.The authors sincerely thank the Co-Editor Oliver Linton and three anonymous referees for constructive criticism and suggestions that helped us to prepare a much revised version of the original manuscript. The feedback by participants of the Conference on Statistical Models for Financial Data at the University of Graz in May 2004 is also greatly appreciated. The research of the first author was partially supported by NSF grant INT-0223262 and NATO grant PST.EAP.CLG 980599. The research of the second author was partially supported by a Discovery Research Grant from the Natural Sciences and Engineering Research Council (NSERC) of Canada.
Information
- Type
- Research Article
- Information
- Copyright
- © 2006 Cambridge University Press
1. INTRODUCTION
Testing assumptions about the distribution of observations or nonobservable errors is one of the main topics in statistics. The theory of empirical processes provides a very elegant way to obtain the limiting distributions of several statistics, including those of the Cramér–von Mises, Kolmogorov–Smirnov, and Kuiper statistics. For a thorough review of empirical processes based on independent random variables we refer to the monograph by Shorack and Wellner (1986).
The results on empirical processes have been extended to several forms of dependence, including martingales and mixing sequences. The empirical processes based on autoregressive moving average (ARMA) innovations have been studied by Bai (1994), Koul (2002), and others (cf. references therein). Interestingly, the limit of the empirical processes of ARMA residuals is the same as that of independent and identically distributed random variables. The limiting distribution of the empirical processes of autoregressive conditional heteroskedasticity (ARCH) residuals was investigated by Horváth, Kokoszka, and Teyssière (2001). In this case the limiting process is different from that for independent random variables. These results have been extended to the generalized autoregressive conditional heteroskedasticity (GARCH) case by Berkes and Horváth (2001). The monograph edited by Dehling, Mikosch, and Sørensen (2002) contains a number of papers on empirical process techniques for dependent data.
Starting with the fundamental papers by Rosenblatt (1956) and Parzen (1962), density estimation has become a popular topic. Indeed, looking at the shape of a density function, it is much easier to recognize the underlying distribution. Densities are frequently used for hypothesis testing, separating distributions, and so on. We refer to the monographs by Devroye (1987), Silverman (1986), and Simonoff (1998), and to the references therein, for numerous applications of the methodology of density estimation.
Bickel and Rosenblatt (1973) obtained the limiting distribution of the L2-distance between kernel density estimators and the corresponding densities. Their result can be considered an analogue of the Cramér–von Mises statistic for densities. Their results were subsequently extended by Csörgő and Horváth (1988) to Lν-distances for arbitrary 1 ≤ ν < ∞. In the case of autoregressive (AR) sequences, Lee and Na (2002) showed that the L2-norm of the difference between kernel-type density estimators of residuals and errors is so small that the theory developed for independent and identically distributed random variables (cf. Bickel and Rosenblatt, 1973) can be used in this context also. The results of Lee and Na (2002) were subsequently extended by Horváth and Zitikis (2004) to the Lν-norms for any 1 ≤ ν < ∞.
In the present paper we consider the problem of estimating the densities of GARCH innovations and, subsequently, produce goodness-of-fit tests for the densities. It should be noted at the outset that because the innovations are not observable, the task of constructing density estimators and investigating their properties is technically complex. We also point out that, as we shall see later in the paper, the limit of the L1-norm of the kernel-type density estimator based on GARCH residuals is different from that of the L1-norm of the density estimator based on independent and identically distributed innovations. Hence, when formulating our results in Section 3, we shall notice differences between the two cases ν = 1 and 1 < ν < ∞. In the next section we shall introduce the necessary notation and rigorous formulation of the problem and will also define a kernel density estimator to be considered in Section 3.
2. NOTATION, GENERAL ASSUMPTIONS, AND THE ESTIMATOR
Let {yk,−∞ < k < ∞} be a GARCH(p,q) process (cf. Bollerslev, 1986) defined by the equations


where ω > 0, αi ≥ 0, and βj ≥ 0 are unknown parameters and εk, −∞ < k < ∞, are independent and identically distributed random variables. The p ≥ 1 and q ≥ 1 can be any integers. However, by including extra terms with zero coefficients in equation (2.2) we can always achieve the condition min(p,q) ≥ 2, which we shall need in our considerations that follow.
Bougerol and Picard (1992a, 1992b) have found necessary and sufficient conditions for the existence of a unique stationary solution of (2.1) and (2.2) for arbitrary p ≥ 1 and q ≥ 1. Nelson (1991) has solved the problem when p = 1 and q = 1. For the completeness of our presentation, we now state the conditions of Bougerol and Picard (1992a, 1992b). Let

Define the (p + q − 1) × (p + q − 1) matrix An, written in block form, by

where Iq−1 and Ip−2 are identity matrices of size q − 1 and p − 2, respectively. The top Lyapunov exponent γL associated with the sequence {An,−∞ < n < ∞} is

assuming that the expectation

is finite, where the norm

of a matrix M is defined by

with the usual (Euclidean) norm ∥·∥. Bougerol and Picard (1992a, 1992b) show that when

, then equations (2.1) and (2.2) have a unique strictly stationary nonanticipative solution if and only if γL < 0. (“Nonanticipative solution” means that {σk2,k ≤ i} and {εk,k ≥ i} are independent for all −∞ < i < ∞.) Hence, throughout the rest of the present paper we assume γL < 0 and work with the aforementioned stationary solution of equations (2.1) and (2.2).
Suppose that the random variables εk have a density function (with respect to the Lebesgue measure), which we denote by f. The behavior of f can assist the researcher in finding efficient estimators for the parameters of the GARCH process (cf. Drost and Klaassen, 1997; Berkes and Horváth, 2004). Because f is rarely known in practice, one may need to construct an empirical estimator for the density f and then investigate its statistical properties. Note in this regard that if εk were observable, then one could use, for example, the classical kernel-type density estimator

where h = hn ↓ 0 is the so-called bandwidth and K is the kernel. The function K is usually assumed to be a density function with compact support; we also assume this throughout the present paper.
Because in GARCH models we only observe y1,…,yn, the estimator fn(x) is not practical. To circumvent the problem, we use the residuals (estimated innovations) instead of the unobservable ε1,…,εn. To start with, we use equation (2.1) and write εk = yk /σk for every k = 1,…,n. Then we construct estimators

using y1,…,yn (we shall discuss this later in this section) and define n new random variables (so-called residuals) by

Finally, we define an estimator

of f by

The main goal of this paper is to present assumptions under which the appropriately normalized Lν-norm

has a nondegenerate limiting distribution. We note in passing that the results of this paper hold for weighted Lν-norms also, that is, when dx on the right-hand side of (2.3) is replaced by w(x) dx with any nonnegative bounded function w.
We shall now show that our goal stated in the previous paragraph is actually simpler. Namely, Bickel and Rosenblatt (1973), Csörgő and Horváth (1988), and Beirlant and Mason (1995) have proved that the appropriately centered and scaled νth power of

has asymptotically standard normal distribution. (We refer to these papers for results and assumptions because they are too lengthy to be recorded here.) Hence, the asymptotic behavior of

is established if we show that the quantity

converges to 0 in probability. Interestingly, this result holds when 1 < ν < ∞ but fails when ν = 1. We shall discuss this phenomenon in greater detail in the next section.
We shall now define the aforementioned estimator

of σk and in this way complete the definition of

. Let θ = (ω,α1,…,αp,β1,…,βq) be the vector of all the unknown parameters of the GARCH(p,q) process. We assume that αi > 0 and βj > 0. Note that the assumption γL < 0 implies β1 + ··· + βq < 1. Let ρ, u, and u be such that β1 + ··· + βq < ρ < 1 and 0 < u < u ≤ qu < ρ. Define U as the set of the vectors u = (x,s1,s2,…,sp,t1,t2,…,tq) whose all coordinates are not smaller than u, and not larger than u, and such that t1 + t2 + ··· + tq ≤ ρ. We also choose u and u such that θ is in the interior of the set U. (The preceding assumptions are standard in the literature on GARCH models.)
We continue with the well-known (cf., e.g., Berkes, Horváth, and Kokoszka, 2003) equality

where wk : Rp+q+1 → [0,∞) are (random) functions defined by

The functions ci(u) : Rp+q+1 → [0,∞) are deterministic and known. For explicit definitions of these functions and their properties we refer to Berkes et al. (2003). In the present paper we use the following property (cf. Berkes et al., 2003, Sect. 3):

where ρ ∈ (0,1) is from the definition of U.
Next, using the observations y1,…,yn, we construct an estimator θn of θ such that

where ∥·∥ denotes the (usual) Euclidean norm in the space R1+p+q. We point out that, unless explicitly mentioned otherwise, throughout the current paper we only use property (2.5). Thus, any estimator θn satisfying (2.5) could be used. For example, Horváth and Liese (2004) study M-type robust estimators. Drost and Klaassen (1997) and Berkes and Horváth (2004) introduce estimators that are more efficient than the widely used quasi-maximum likelihood estimator.
Replacing θ on the right-hand side of (2.4) by θn, we obtain the quantity

The variables

are not of practical use for estimating σk because the functions wk(u) depend on the infinite sequence {yj : −∞ < j ≤ k − 1}, whereas only y1,…,yn are observed and can therefore be used for constructing estimators. To circumvent the problem, we follow Berkes et al. (2003) and introduce truncated versions of the previously defined functions wk(u) by
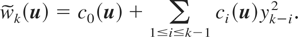
The desired estimator

is given by the formula

which completes the rigorous definition of the kernel-type density estimator

. The next section is devoted to asymptotic properties of the estimator

and, in turn, to constructing goodness-of-fit tests.
3. MAIN RESULTS
As we have noted in the previous section, our goal in this paper is to understand the asymptotic behavior of the quantity Θn. The first result, Theorem 3.1, provides an approximation of Θn by the Lν-norm of a very simple stochastic process:

where xT is the transpose of the vector x, K(1) is the first derivative of the kernel K (we assume throughout that the kernel K is differentiable), and wk(1)(θ) is the vector of the partial derivatives of wk(θ). We note at the outset that when proving the following results we shall use some lemmas from Berkes et al. (2003), where they require that, for some δ > 0,

when t ↓ 0. Hence, we also assume (3.1) throughout the paper.
THEOREM 3.1. Let 1 ≤ ν < ∞. Let the bandwidth h ↓ 0 be such that nhA → ∞ for some A ≥ max(2 + 1/ν, 3 − 1/ν). Furthermore, let the kernel K have finite support and be R ≥ 2 times differentiable, where R is an integer such that R ≥ (A + 1 − 1/ν)/(A − 2). Assume that E(|ε0|max(ν(R−1),2R−1)(1+δ)) < ∞ for some δ > 0. Furthermore, assume that the density f is differentiable and ∫R(fν(x) + | f(1)(x)|ν)(1 + |x|ν(R−1)) dx < ∞, where f(1) is the first derivative of f. Then

The assumption that nhA → ∞ for some A ≥ max(2 + 1/ν, 3 − 1/ν) is weaker than similar assumptions used to establish the asymptotic normality of Lν-norms of kernel-type density estimators (cf. Bickel and Rosenblatt, 1973; Csörgő and Horváth, 1988; and Beirlant and Mason, 1995). For example, the “optimal” case h = cn−1/5 is covered by our results, in which case we can choose R = 2 and thus work with two times differentiable kernels. Indeed, with the preceding “optimal” choice of h, we have nhA → ∞ provided that A < 5. Note that the assumption R ≥ (A + 1 − 1/ν)/(A − 2) is equivalent to (2R + 1 − 1/ν)/(R − 1) ≤ A, which in the case R = 2 becomes 5 − 1/ν ≤ A. The latter observation suggests choosing A = 5 − 1/ν, which satisfies the requirement A < 5 for every 1 ≤ ν < ∞. Note also that when R = 2, then the moment condition on ε0 in the two most popular cases ν = 1 and ν = 2 reduces to the condition E(|ε0|3(1+δ)) < ∞ with some δ > 0, which is a weak one.
THEOREM 3.2. Let 1 < ν < ∞ and assume that all the conditions of Theorem 3.1 are satisfied. Then we have that

Consequently, Θn →P 0 for any 1 < ν < ∞.
We shall now show how the statement Θn →P 0 for any 1 < ν < ∞ can be used to produce goodness-of-fit tests for densities of GARCH innovations. First we note that such tests are of interest. For example, in the literature it is sometimes assumed that εk's are standard normal random variables. Hence, it is desirable to have a test to check the assumption. Furthermore, the assumption plays an important role when establishing efficiency of the quasi-likelihood method for parameter estimation in GARCH models. Hence, and more generally, we are interested in checking if the density of εk is f0, a specified density function. To proceed with the discussion, we need to introduce additional notation. With

denoting a standard Gaussian random variable, let

where

Under certain additional assumptions, Csörgő and Horváth (1988) proved that

Hence, in view of statements Θn →P 0 and (3.4), we have that, for any 1 < ν < ∞,

Note in passing that, as expected, statement (3.5) implies Lν-consistency of the estimator

; that is, we have the convergence

, provided that h → 0 and nh → ∞, which are usual assumptions in kernel density estimation; they are obviously satisfied in the context of the present paper (cf. the formulation of Theorem 3.1). To proceed with our main discussion, we choose a specific density function f0 and state the following hypotheses:

In view of statement (3.5), under the null hypothesis H0 the test statistic Tn(f0) converges in distribution to

. Under the alternative H0, the statistic Tn(f0) converges in probability to infinity, because we indeed have nν/2h(ν−1)/2 → ∞ as a result of the earlier noted nh → ∞. This concludes our main discussion concerning the case 1 < ν < ∞, but there will be more on the topic after Theorem 3.3.
We shall now investigate the case ν = 1. For this reason we need to require from the estimator θn slightly more than has been stated in (2.5). Namely, we assume that

converges in distribution; denote the limit random vector by ξ. Such results have been established by several authors for different types of estimators θn. Lee and Hansen (1994) and Lumsdaine (1996) proved this convergence for the quasi-maximum likelihood estimator in GARCH(1,1) models. These results were extended by Berkes et al. (2003) to GARCH(p,q) sequences and by Kristensen and Rahbek (2003) to ARCH(q) sequences. Baillie and Chung (2002) used estimators based on autocorrelations. Efficient estimators were considered by a number of authors, and we refer here to Linton (1993), Drost and Klaassen (1997), and Berkes and Horváth (2004) and to references in those papers. Horváth and Liese (2004) proved the convergence in distribution of

for M-estimators. We note that in all those cases ξ is a nondegenerate p + q + 1-dimensional normal random vector.
THEOREM 3.3. Let ν = 1 and assume that the conditions of Theorem 3.1 are satisfied. Furthermore, assume that

, where

means convergence in distribution. Then

where

Consequently,

when ν = 1.
To understand the reason why Θn is asymptotically nondegenerate when ν = 1 and degenerate when ν > 1, we shall present a string of approximate equalities that will explain the phenomenon and will also clarify the main idea of the (somewhat involved) proofs in Section 4. Thus, using the mean-value theorem and deferring other details of proof until the next section, we write the approximate equalities

If we multiply the right-hand side of (3.7) by

, then it will converge in distribution to a nondegenerate random variable, provided that ξ in Theorem 3.3 is nondegenerate. Hence,

is asymptotically nondegenerate. This explains why Θn has an asymptotically nondegenerate limit distribution when ν = 1. On the other hand, when 1 < ν < ∞, then the normalizing constant

is of the order

, and therefore the right-hand side of (3.7) converges to 0 in probability. This explains why in Theorem 3.2 we have Θn →P 0 for any 1 < ν < ∞.
4. PROOFS
We start with the note that, throughout the proofs, c denotes an unimportant constant whose value may change from line to line. Next we formulate two auxiliary lemmas that we shall constantly use subsequently. When formulating the lemmas, we use the notation

LEMMA 4.1. If E(|ε02|γ) < ∞ for some γ > 0, then E(S0κ) < ∞ for any 0 < κ < γ.
Proof. This is Lemma 5.1 in Berkes et al. (2003). █
LEMMA 4.2. If E(|ε02|γ) < ∞ for some γ > 0, then E(S0,iκ) < ∞ for any κ > 0 and for both i = 1,2.
Proof. This follows from Lemma 2.3 in Berkes et al. (2003). █
Now we start the proofs of the three theorems. The proofs contain a number of lemmas. The following lemma allows us to reduce our consideration of the norm

to the corresponding properties of

, where

is defined by

with

for all k = 1,…,n.
LEMMA 4.3. If the conditions of Theorem 3.1 are satisfied, then

Proof. Using the mean-value theorem, we have

where ξk is a random variable between

. We shall now estimate

. First we write the difference as

Note that

. In the event θn ∈ U (and we only need to consider this event because its complement is of negligible probability) we have that c0(θn) ≥ infu∈U c0(u) > 0. Furthermore,

. In view of these notes we have that

does not exceed

. Berkes et al. (2003, Sect. 3) proved that supu∈U ci(u) ≤ cρi/q, where ρ ∈ (0,1) is from the definition of U. Hence,

The sum [sum ]0≤i<∞ ρi/qy−i2 is finite almost surely (cf. Berkes et al., 2003). Therefore, from bound (4.3) and equality (4.2) we have that

Using this bound, the Hölder inequality, and also the notation

, we obtain

The integral on the right-hand side of (4.5) cannot be larger than c|h|. This can be checked by first changing the variable of integration x into ξk + xh and then using the fact that the first derivative K(1) of K has a bounded support. Therefore,

To complete the proof of statement (4.1), we need to show that the quantity on the right-hand side of (4.6) converges to 0 in probability. Because ν ≥ 1 and nh3−1/ν → ∞ by assumption, we only need to check that the sum [sum ]1≤k≤n vk is of the order

. This follows if the sum [sum ]1≤k≤n E(vk) is asymptotically bounded. We estimate the latter sum by

. The moment E(εk2) [= E(ε02)] is finite. Furthermore, E(Sk) [= E(S0)] is finite by Lemma 4.1 if E(|ε02|(1+δ)) < ∞ for some δ > 0. The latter moment is finite because we assume E(|ε0|(R−1)max(2,ν)(1+δ)) < ∞. The sum [sum ]1≤k≤n ρk/q converges because ρ ∈ (0,1). This completes the proof that the right-hand side of (4.6) converges to 0 in probability. The lemma is proved. █
As we already noted, Lemma 4.3 reduces our consideration of the asymptotic behavior of

to the corresponding properties of the norm

. Using the Taylor formula, we have that

where R ≥ 2 is an integer specified in the formulation of Theorem 3.1 and

with ξk denoting a random variable between

. It is clear from representation (4.7) that we only need to consider the asymptotics of ∥Dn,r∥ν and ∥Dn,R*∥ν. We start with ∥Dn,R*∥ν because it is the latter term that determines the value of R given in Theorem 3.1.
LEMMA 4.4. If the conditions of Theorem 3.1 are satisfied, then

Proof. Using the Hölder inequality, we have that

The integral ∫R|K(R)((x − ξk)/h)|ν dx does not exceed ch because the function K(R) has a compact support. Consequently, ∥Dn,R*∥ν does not exceed

. It is natural to expect that the sum

is of the order

. Now taking this statement for granted (cf. (4.9), which follows, for a proof), we obtain that ∥Dn,R*∥ν ≤ cnh1/ν. This yields (4.8) provided that nh(2R+1−1/ν)/(R−1) tends to infinity. For the latter statement to hold in view of the assumption nhA → ∞, we need to have (2R + 1 − 1/ν)/(R − 1) ≤ A or, equivalently, R ≥ (A + 1 − 1/ν)/(A − 2). But this has been assumed. Hence, statement (4.8) holds.
To complete the proof of the lemma, we need to verify that

First we note that

where θ* satisfies ∥θ* − θ∥ ≤ ∥θn − θ∥. Hence, we can assume θ* ∈ U without loss of generality because the probability of the opposite event is negligible. It follows from (4.10) that

does not exceed

. Because

does not depend on k and is of the order

, we therefore have (4.9) provided that

. The latter follows if

, which we are now to prove.
The random variable εk is independent of Sk and Sk,1. Therefore,

does not exceed the product of E(|εk|R) and E(SkR/2Sk,1R). We estimate the latter expectation using the Hölder inequality. Hence, for any δ0 > 0, we have that

The right-hand side of (4.11) does not depend on k, and so we only need to check that it is finite. In view of Lemma 4.1, the expectation E(S0R(1+δ0)/2) is finite when E(|ε0|R(1+δ)) < ∞ and 0 < δ0 < δ. The latter expectation is finite because of the assumption E(|ε0|(R−1)max(2,ν)(1+δ)) < ∞. This also implies that the expectation E(|ε0|R) on the right-hand side of (4.11) is finite. To check that the expectation E(S0,1R(1+δ)/δ) is finite, we use Lemma 4.2. This finishes the proof that

. Statement (4.9) follows, which also completes the proof of the lemma. █
From Lemma 4.4 we have that

We note that the functions Dn,r(x) are nicer than Dn,R*(x) from a technical point of view. Indeed, the functions Dn,r(x) do not have variables like ξk inside them, and therefore they allow us to employ additional technical tools such as martingale theory. Before going into detailed considerations, however, we first simplify statement (4.12) by replacing the functions Dn,r(x) by even simpler functions Δn,r(x) defined by

LEMMA 4.5. If the conditions of Theorem 3.1 are satisfied, then for any 1 ≤ r ≤ R − 1 we have that

Proof. Just as in the proof of Lemma 4.4 we showed that ∥Dn,R*∥ν does not exceed

, we now have that ∥Dn,r − Δn,r∥ν does not exceed

. This time, however, we need a more careful analysis of the difference

than the analysis in the proof of Lemma 4.4. It follows from the Taylor formula that there exists ξk satisfying the property ∥ξk − θ∥ ≤ ∥θn − θ∥ and such that

equals Mk + cn−1/2Rk with the remainder term

Hence,

does not exceed cn−1/2(|Mk|r−1|Rk| + |Rk|r), which implies the bounds

We note that

, which we can easily verify following the arguments starting with (4.10). Consequently, ∥Dn,r − Δn,r∥ν is of the order

. From this we obtain that (4.13) is a consequence of nh2+1/r−1/(rν) → ∞. Note that, for any r ≥ 1, the quantity 2 + 1/r − 1/(rν) does not exceed 3 − 1/ν. Because nh3−1/ν → ∞ by assumption, we have nh2+1/r−1/(rν) → ∞. This completes the proof of the lemma. █
From Lemma 4.4 we have the following result:

We note that the first summand (when r = 1) (1/n3/2h2)Δn,1(x) in (4.14) is similar to the function gn(x), and so we expect it to play a role when ν = 1. Based on this observation, we can now guess how we shall proceed with the following proof. When 1 < ν < ∞, from (4.14) we obtain the statement

We need to show that the right-hand side of (4.15) converges to 0 in probability. When ν = 1, then from (4.14) we have the following statement (note that cr = 1/r! and thus c1 = 1):

We need to show that the right-hand side of (4.16) converges to 0 in probability. In summary, we need to show that

for every 1 ≤ r ≤ R − 1 when 1 < ν < ∞, and for every 2 ≤ r ≤ R − 1 when ν = 1.
When proving (4.17), we shall work with the coordinates of the following vectors:

We write

where

Furthermore, denote

We have

It follows from (2.5) that

. Consequently, we obtain from (4.19) that statement (4.17) holds provided that, for any j1,…,jr ∈ {1,…,p + q + 1}, we have

Statement (4.20) will turn out to be true for every 1 ≤ r ≤ R − 1 and 1 ≤ ν < ∞ except when both r and ν are equal to 1.
We shall prove (4.20) in two steps. Namely, we shall first prove it (cf. Lemma 4.6, which follows) with gr,k(x) replaced by E(gr,k(x)) [= E(gr,0(x))] and then (cf. Lemma 4.7, which follows) with gr,k(x) replaced by the centered version

The proof in the first case will be a straightforward mathematical computation, whereas the proof in the second case will be more involved.
LEMMA 4.6. If the conditions of Theorem 3.1 are satisfied, then we have

for every 1 ≤ r ≤ R − 1 and 1 ≤ ν < ∞ except when both r and ν are equal to 1.
Proof. The sum [sum ]1≤k≤n νk(j1,…,jr) is of the order

. This fact can be checked by noting that the expected value of |νk(j1,…,jr)| does not depend on n and is finite provided that the expectations E(|S0|r(1+δ0)/2) and E(|S0,1|r(1+δ0)/δ0) are finite for some δ0 > 0. We have already proved (cf. the discussion following (4.11)) that the two expectations are finite when r = R. Thus, the expectations are finite for any 1 ≤ r ≤ R − 1.
We shall prove subsequently (cf. (4.23), which follows) that the integral ∫R|E(gr,0(x))|ν dx does not exceed ch2ν. Hence, statement (4.22) should hold provided that nr−1h2r−3+1/ν → ∞. When r = 1, then the latter statement holds indeed because ν > 1 and h → 0. When r ≥ 2, then we write the statement as nh(2r−3+1/ν)/(r−1) → ∞ and note that (2r − 3 + 1/ν)/(r − 1) ≤ 3 − 1/ν for any ν ≥ 1. Because nh3−1/ν → ∞ by assumption, Lemma 4.6 follows.
To finish the proof of Lemma 4.6, we need to check that

We write the expectation E(gr,0(x)) as an integral with respect to the density f and then change the variable of integration. This proves that the expectation E(gr,0(x)) equals h ∫R(x − zh)rK(r)(z) f (x − zh) dz and thus in turn equals h(Γ1(x) + Γ2(x)), where

This implies that ∫R|E(gr,0(x))|ν dx does not exceed the sum of chν∫R|Γ1(x)|ν dx and chν∫R|Γ2(x)|ν dx. Hence, we have bound (4.23) provided that, for both i = 1 and i = 2,

To prove (4.24) when i = 1, we first write Γ1(x) as f (x)∫R((x − zh)r − xr)K(r)(z) dz. Next, we estimate |(x − zh)r − xr| by ch|z|(|x|r−1 + |z|r−1). Because K(r) has a bounded support, |Γ1(x)| does not exceed chf (x)(1 + |x|r−1). Consequently,

The integral on the right-hand side of (4.25) is finite by assumption. This concludes the proof of (4.24) when i = 1.
We shall now prove (4.24) when i = 2. We write

Using the Hölder inequality, we have the bounds

The latter bound gives the following one:

Because the integral ∫R| f(1)(x)|ν(1 + |x|ν(R−1)) dx is finite and the support of K(r) is bounded, we obtain from (4.26) that bound (4.24) holds when i = 2. This completes the proof of (4.23) and of the lemma also. █
LEMMA 4.7. If the conditions of Theorem 3.1 are satisfied, then for any values of the indices j1,…,jr ∈ {1,…,p + q + 1} we have that

Proof. Let

denote the σ-algebra generated by {εk,k ≤ [ell ]}. The stochastic process

is a martingale. Thus, from Theorem 2.11 of Hall and Heyde (1980, p. 23) we have the bound

The right-hand side of the preceding bound equals Ψ1Ψ2(x)ν/2 + cΨ3(x), where

Therefore, statement (4.27) holds if

To verify (4.28), we need to obtain appropriate bounds for Ψ1 and for the two integrals with Ψ2 and Ψ3. This we do subsequently.
We shall prove that Ψ1 ≤ cnν/2 when 1 ≤ ν < 2. Because ν/2 < 1, in the definition of Ψ1 we take the expectation E inside {…}ν/2. This implies that Ψ1 does not exceed np/2{E(ν02(j1,…,jr))}ν/2. The expectation E(ν02(j1,…,jr)) is finite provided that E(S0r(1+δ0)) and E(S0,12r(1+δ0)/δ0) are finite for some δ0 > 0. The expectation E(S0r(1+δ0)) is finite because of Lemma 4.1 and the moment assumption E(|ε0|(R−1)2(1+δ)) < ∞ with δ > δ0. The expectation E(S0,12r(1+δ0)/δ0) is finite because of Lemma 4.2. We have therefore proved that Ψ1 ≤ cnν/2 holds when 1 ≤ ν < 2.
We shall now prove that Ψ1 ≤ cnν/2 when ν ≥ 2. Because ν/2 ≥ 1, we need to proceed differently than before. First we note that {[sum ]1≤k≤n νk2(j1,…,jr)}ν/2 does not exceed nν/2−1 [sum ]1≤k≤n|νk(j1,…,jr)|ν. Hence, Ψ1 does not exceed nν/2E(|ν0(j1,…,jr)|ν). This implies that Ψ1 ≤ cnν/2 provided that the expectation E(|ν0(j1,…,jr)|ν) is finite. The latter follows if the expectations E(S0rν(1+δ0)/2) and E(S0,12rν(1+δ0)/δ0) are finite. The first expectation is finite by Lemma 4.1 due to E(|ε0|(R−1)ν(1+δ)) < ∞ for some δ > 0. The expectation E(S0,12rν(1+δ0)/δ0) is finite by Lemma 4.2. This completes the proof of Ψ1 ≤ cnν/2 for any ν ≥ 1.
We shall now estimate the integral ∫R Ψ2(x)ν/2 dx. First we note that Ψ2(x) does not exceed E(|gr,0(x)|2). We shall prove in Lemma 4.8 that when α = 2, β = ν/2, and ν ≥ 1, then the integral ∫R|E(gr,02(x))|ν/2 dx does not exceed chν/2, and so the same upper bound holds for ∫R Ψ2(x)ν/2 dx.
Given the bounds obtained so far, we have that Ψ1 ∫R Ψ2(x)ν/2 dx does not exceed cnν/2hν/2. Hence, the quantity in (4.28) with, for a moment, the integral of Ψ3 deleted converges to 0 provided that nh2+1/(νr) → ∞. But the latter holds for any r ≥ 1 because nh2+1/ν → ∞ by assumption. Hence, to finish the proof of statement (4.28), we only need to show that

Using a bound for the expectation of the largest order statistic from Lai and Robbins (1976), we get that, for any d ≥ 1,

(We shall choose d subsequently.) Next, we express the expectation on the right-hand side of (4.30) as follows:

where the σ-algebra

is the same as before. We shall now discuss the expectations on the right-hand side of (4.31) in detail.
The first expectation on the right-hand side of (4.31) is finite provided that the two expectations E(S0rνd(1+δ0)/2) and E(S0,1rνd(1+δ0)/δ0) are finite for some δ0 > 0. The finiteness of E(S0,1rνd(1+δ0)/δ0) follows from Lemma 4.2 independently of the value of d ≥ 1. The finiteness of E(S0rνd(1+δ0)/2) depends on d. Therefore, we now state the choice of d that will be suggested by our calculations that follow. Namely, we have

If d = 1, then the expectation E(S0rνd(1+δ0)/2) equals E(S0rν(1+δ0)/2). We have already verified that the latter expectation is finite because E(|ε0|(R−1)ν(1+δ)) < ∞ for some δ > 0, when ν ≥ 2. If d = 2/ν, then E(S0rνd(1+δ0)/2) equals E(S0r(1+δ0)). We already proved that the latter expectation is finite because E(|ε0|(R−1)2(1+δ)) < ∞ for some δ > 0, when 1 ≤ ν < 2.
In view of the notes in the previous paragraph and the fact that the expectation E(|Gr,0(x)|νd) does not exceed cE(|g0(x)|νd), we have from (4.30) and (4.31) that the function Ψ3(x) does not exceed cn1/d(E(|gr,0(x)|νd))1/d. This in turn implies that ∫R Ψ3(x) dx does not exceed cn1/d∫R|E(|gr,0(x)|νd)|1/d dx. With the notations α = νd and β = 1/d, the latter integral equals ∫R|E(|gr,0(x)|α)|β dx, which we denote by Ξ for brevity.
When 1 ≤ ν < 2, then d = ν/2 and thus α = 2 and β = ν/2. Lemma 4.8, which follows, implies that Ξ ≤ ch1/d. When ν ≥ 2, then d = 1 and thus α = ν and β = 1. Lemma 4.8 again implies the bound Ξ ≤ ch1/d. Hence, the integral ∫R Ψ3(x) dx does not exceed cn1/dh1/d. This implies (4.29) provided that nh1+(r+1/ν)/(r+1−2/(νd)) → ∞. The latter follows if the exponent of h does not exceed A. This is equivalent to

Recall that d has to be at least 1. Because r ≥ 1 and A ≥ 2 + 1/ν by assumption, the ratio in the parentheses on the right-hand side of (4.33) does not exceed 1. Thus, the choice of d given in (4.32) is indeed natural and satisfies condition (4.33). This completes the proof of (4.29) and of the lemma also. █
In the proof of Lemma 4.7 we referred several times to Lemma 4.8. Here now is its formulation, followed by the proof.
LEMMA 4.8. If the conditions of Theorem 3.1 are satisfied, then we have that

for the following sets of parameters:

Proof. We start with the bound

where C > 0 is a finite constant such that that K(r) is 0 outside the interval [−C,C]. Hence, ∫R|E(|gr,0(x)|α)|β dx does not exceed chβI(α,β), where

The lemma is proved if we show that the integral I(α,β) is finite.
When β ≥ 1, then the integral does not exceed c ∫R|x|rαβf (x)β dx. Note that when β ≥ 1, then we have two cases: first, α = 2, β = ν/2, and ν ≥ 2; second, α = ν, β = 1, and ν ≥ 2. In the first case the integral ∫R|x|rαβf (x)β dx is equal to ∫R|x|νrf (x)ν/2 dx, and in the second case it is equal to ∫R|x|νrf (x) dx. The integral ∫R|x|νrf (x)ν/2 dx does not exceed the sum of the integrals ∫R|x|νrf (x) dx and ∫R|x|νrf (x)ν dx. The first integral equals E(|ε0|νr) < ∞, which is finite as we have already noted earlier. The integral ∫R|x|νrf (x)ν dx is finite by assumption.
When 0 < β < 1, we choose any γ > 1 − β and using the Hölder inequality obtain that

where u = 1/(1 − β), v = 1/β, and

The first integral on the right-hand side of (4.36) is finite. To prove that the integral Iγ(α,β) is also finite, we obtain the bound

The integral on the right-hand side of (4.37) is finite provided that E(|ε0|rα+γ/β) < ∞. Because 0 < β < 1, we only need to consider the case when α = 2, β = ν/2, and 1 ≤ ν < 2. Hence, the integral on the right-hand side of (4.37) is finite provided that E(|ε0|(2r−1+2/ν)(1+δ)) < ∞ for some δ > 0. Note that 2r − 1 + 2/ν does not exceed 2R − 1. Hence, the expectation E(|ε0|(2r−1+2/ν)(1+δ)) is finite because E(|ε0|(2R−1)(1+δ)) < ∞ when 1 ≤ ν < 2 by assumption. █
With the preceding lemma we have completed the verification of statement (4.17). In view of (4.15), we therefore have that

for every 1 < ν < ∞. In view of (4.16) we have that, when ν = 1,

We already noted that (1/n3/2h2)Δn,1(x) is very similar to the function gn(x). We now need to establish a more precise relationship between the two random functions. We write the equalities


From (4.40) and (4.41) we have that

where G1,k(x) is defined in (4.21). Lemma 4.7 implies that, for every ν ≥ 1,

Statements (4.38), (4.39), and (4.42) complete the proof of Theorem 3.1. Statements (4.38) and (4.42) complete the proof of Theorem 3.2. To complete the proof of Theorem 3.3, we need an additional argument.
We write the equality

Because the random variables wk(1)(θ)/wk(θ), k ≥ 1, make a stationary and ergodic sequence with finite means (cf. Berkes et al., 2003), by the ergodic theorem we have that n−1 [sum ]1≤k≤n wk(1)(θ)/wk(θ) converges to E(w0(1)(θ)/w0(θ)) almost surely. Next we show that

Before starting the proof of (4.44) we note that the preceding results imply Theorem 3.3 because of the convergence in distribution of

to ξ.
To prove (4.44), we use the arguments following (4.23) with ν = 1 and r = 1, and we express the expectation E(g1,0(x)) as the sum of hΓ1(x) and hΓ2(x), where Γ1(x) = hf (x) and

Hence,

where

From (4.45) we have (4.44) provided that the integrals ∫R|Γ2*(x)|dx and ∫R|Γ2**(x)|dx converge to 0 when h → 0. Using same arguments as those in (4.26), we have that ∫R|Γ2**(x)|dx converges to 0 provided that | f(1)(x)| is integrable, which follows from the assumptions of Theorem 3.1. Using similar arguments and also the Lebesgue dominated convergence theorem, we obtain that ∫R|Γ2*(x)|dx converges to 0 provided that the function (1 + |x|)| f(1)(x)| is integrable, which follows from the assumptions of Theorem 3.1. This finishes the proof of Theorem 3.3.
References
REFERENCES
Bai, J.
(1994)
Weak convergence of the sequential empirical processes of residuals
in ARMA models.
Annals of Statistics
22,
2051–2061.CrossRefGoogle Scholar
Baillie, R.T. &
H. Chung
(2002)
Estimation of GARCH models from the autocorrelations of the squares
of a process.
Journal of Time Series Analysis
22,
631–650.Google Scholar
Beirlant, J. &
D.M. Mason
(1995)
On the asymptotic normality of Lp-norms
of empirical functionals.
Mathematical Methods of Statistics
4,
1–19.Google Scholar
Berkes, I. &
L. Horváth
(2001)
Strong approximation of the empirical process of GARCH
sequences.
Annals of Statistics
11,
789–809.Google Scholar
Berkes, I. &
L. Horváth
(2004)
The efficiency of the estimators of the parameters in GARCH
processes.
Annals of Statistics
32,
633–655.Google Scholar
Berkes, I.,
L. Horváth, &
P. Kokoszka
(2003)
GARCH processes: Structure and estimation.
Bernoulli
9,
201–227.Google Scholar
Bickel, P. &
M. Rosenblatt
(1973)
On some global measures of the deviations of density function
estimates.
Annals of Statistics
1,
1071–1095.Google Scholar
Bollerslev, T.
(1986)
Generalized autoregressive conditional heteroskedasticity.
Journal of Econometrics
31,
307–327.Google Scholar
Bougerol, P. &
N. Picard
(1992a)
Strict stationarity of generalized autoregressive processes.
Annals of Probability
20,
1714–1730.Google Scholar
Bougerol, P. &
N. Picard
(1992b)
Stationarity of GARCH processes and of some nonnegative time
series.
Journal of Econometrics
52,
115–127.Google Scholar
Csörgő, M. &
L. Horváth
(1988)
Central limit theorems for Lp-norms of
density estimators.
Probability Theory and Related Fields
80,
269–291.Google Scholar
Dehling, H.,
T. Mikosch, &
M. Sørensen
(2002)
Empirical Process Techniques for Dependent Data.
Birkhäuser.
Devroye, L.
(1987)
A Course on Density Estimation.
Birkhäuser.
Drost, F.C. &
C.A. Klaassen
(1997)
Efficient estimation in semiparametric GARCH models.
Journal of Econometrics
81,
193–221.Google Scholar
Hall, P. &
C.C. Heyde
(1980)
Martingale Limit Theory and Its Application.
Academic Press.
Horváth, L.,
P. Kokoszka, &
G. Teyssière
(2001)
Empirical process of the squared residuals of an ARCH
sequence.
Annals of Statistics
29,
445–469.Google Scholar
Horváth, L. &
F. Liese
(2004)
Lp-estimators in ARCH models.
Journal of Statistical Planning and Inference
119,
277–309.Google Scholar
Horváth, L. &
R. Zitikis
(2004)
Asymptotics of the Lp-norms of density
estimators in the first-order autoregressive models.
Statistics and Probability Letters
66,
91–103.Google Scholar
Koul, H.L.
(2002)
Weighted Empirical Processes in Dynamic Nonlinear Models.
Springer.
Kristensen, D. &
A. Rahbek
(2003)
Asymptotics of the QMLE for a class of ARCH(q)
models.
Econonometric Theory
21,
946–961.Google Scholar
Lai, T.L. &
H. Robbins
(1976)
Maximally dependent random variables.
Proceedings of the National Academy of Sciences U.S.A.
73,
286–288.Google Scholar
Lee, S.W. &
B.E. Hansen
(1994)
Asymptotic theory for the GARCH(1,1) quasi-maximum likelihood
estimator.
Econometric Theory
10,
29–52.Google Scholar
Lee, S. &
S. Na
(2002)
On the Bickel–Rosenblatt test for first-order autoregressive
models.
Statistics and Probability Letters
56,
23–35.Google Scholar
Lumsdaine, R.L.
(1996)
Consistency and asymptotic normality of the quasi–maximum
likelihood estimator in IGARCH (1,1) and covariance stationary GARCH (1,1)
models.
Econometrica
64,
575–596.Google Scholar
Nelson, D.
(1991)
Conditional heteroskedasticity in asset returns: A new
approach.
Econometrica
59,
347–370.Google Scholar
Parzen, E.
(1962)
On estimation of a probability density function and mode.
Annals of Mathematical Statistics
33,
1065–1076.Google Scholar
Rosenblatt, M.
(1956)
Remarks on some nonparametric estimates of a density
function.
Annals of Mathematical Statistics
27,
832–837.Google Scholar
Shorack, G.R. &
J.A. Wellner
(1986)
Empirical Processes with Applications to Statistics.
Wiley.
Silverman, B.W.
(1986)
Density Estimation for Statistics and Data Analysis.
Chapman and Hall.
Simonoff, J.S.
(1998)
Smoothing Methods in Statistics.
Springer.
 You have
Access
- 8
- Cited by