




No CrossRef data available.
Article contents
PARTIALLY SUPERFLUOUS OBSERVATIONS
Published online by Cambridge University Press: 15 March 2006
Abstract
Necessary and sufficient conditions are established for the second subsample to be partially redundant given the first subsample for the best linear unbiased estimator of a subset of the coefficient vector of a general linear regression model.We thank the Co-editor for his very helpful comments on an earlier draft.
Information
- Type
- NOTES AND PROBLEMS
- Information
- Copyright
- © 2006 Cambridge University Press
1. PROBLEM AND MOTIVATION
Consider the general linear (Gauss–Markov) regression model

where N is the sample size, yi is the dependent variable, xi ≡ (xi1′,xi2′)′ is a K × 1 column vector of explanatory variables (with xi1 being K1 × 1, xi2 being K2 × 1, and K1 + K2 = K), β ≡ (β1′, β2′)′ is a K × 1 vector of coefficients that is partitioned accordingly, and εi is the disturbance term. Suppose that the sample consists of two subsamples; the first one is of size n and the second one is of size m, with n + m = N. The two subsamples can be from different sources, for example, from different surveys. We make the following assumptions.
(A1) E(ε|x1,…,xN) = 0 with ε = (ε1,…,εN)′.
(A2) X1[bull ] = (x1,…,xn)′ is of full column rank.
(A3) var(ε|x1,…,xN) = σ2V, where σ2 is a positive scalar and V is an N × N known positive definite matrix.
Under these assumptions, it is well known that the generalized least squares (GLS) estimator

using the entire sample is the best linear unbiased estimator (BLUE) of β and is thus more efficient than the GLS estimator

of β using the first subsample only; see, e.g., Gourieroux and Monfort (1980, p. 1093). When

are equally efficient (in other words, when

is also BLUE), Gourieroux and Monfort (1980) refer to the second subsample as superfluous observations for the efficient estimation of β. In this note, we wish to extend their result to a subset of the regression coefficients; more specifically, we seek to find the necessary and sufficient conditions for the second subsample to be partially superfluous for the BLUE of β1 alone.
2. SOLUTION AND DISCUSSION
Stacking model (1) over the observations in the first subsample, we have

where

Similarly, stacking model (1) over the observations in the second subsample, we have

where the notation is defined similarly to before. Finally, stacking (2a) over (2b), we have

where

Under assumptions (A1)–(A3), we can estimate β in (3) (or (1)) by GLS using the first subsample alone or using the entire sample. Thus, we define the following two GLS estimators of β:


where V11 = var(ε1).
Gourieroux and Monfort (1980, p. 1093) derived the necessary and sufficient condition for

to have the same finite-sample efficiency (i.e., the second subsample is fully superfluous for the efficient estimation of β):

In this note, we wish to extend their result to a subvector of β. More specifically, we seek to find necessary and sufficient conditions for the second subsample to be partially superfluous for the BLUE of β1 alone.
Under assumptions (A1)–(A3), it is well known that

is BLUE with

is also unbiased with

. Notice that β1 = Sβ, where the selection matrix S is defined as S = (IK1, 0K1×K2). We can then easily obtain


Because

is the BLUE for β in (1),

is always positive semidefinite and equals zero, if, and only if,

, or equivalently,

There are several ways to find the necessary and sufficient conditions for equation (7) to be true; for example, one obvious but “brute-force” approach is to use the partitioned matrix inverse rule for (X′V−1X)−1 and then simplify the resulting expression. In this note, we will use a much simpler and relatively novel approach to finding the necessary and sufficient conditions for (7) to hold; more specifically, we will calculate the rank of the matrix on the left-hand side of (7). For this purpose, we first recall a simple matrix fact: a matrix is a zero matrix if, and only if, its rank is zero. Thus, (7) holds if, and only if,

To find the rank of the left-hand side of (8), we need to use two well-known rank formulas for partitioned matrices due to Marsaglia and Styan (1974).
LEMMA 1. (i) Let A be a nonsingular matrix of order m, let B, C, and D be m × k, l × m, and l × k matrices, respectively. Then

(ii) If M is symmetric positive semidefinite, then

It can now be easily seen from (9) that CA−1B = D if and only if rk(D − CA−1B) = 0, or equivalently

. In fact, any matrix expression involving inverse of matrix can always be rewritten in the form of the Schur complement D − CA−1B. Then, using (9), we can construct the corresponding partitioned matrix consisting of submatrices A, B, C, and D. When the resulting partitioned matrix can be simplified by elementary block matrix operations, we can obtain some nontrivial rank formula for D − CA−1B, and, as a consequence, we can further derive necessary and sufficient conditions for CA−1B = D to be true.
Given Lemma 1, we are now ready to derive the necessary and sufficient conditions for the second subsample to be partially superfluous for the BLUE of β1. We first establish Lemma 2, as follows.
LEMMA 2. Partition the covariance matrix σ2V into a 2 × 2 block matrix, with the (i,j)-block Vij = E(εiεj′) for i,j = 1,2. Then,

Proof. See the Appendix.
Now, using Lemma 2 and the fact that a matrix is a zero matrix if and only if its rank is also equal to zero, we can readily obtain the main result of this note.
THEOREM 3. Under assumptions (A1)–(A3), given the first subsample, the second subsample is partially superfluous for the BLUE of β1 in model (1) if, and only if,

One way to provide an intuition for the necessary and sufficient condition (12) is as follows. Premultiplying (3) by

, we have

or simply written as

where e2 = ε2 − V21V11−1ε1 is the linear projection error of ε2 onto ε1 and thus is uncorrelated with ε1. Now, premultiplying (13b) again by

with M2 = In − X12*(X12*′X12*)−1X12*′, we have

where y2** = y2* − X22*(X12*′X12*)−1X12*′y1*, X21** = X21* − X22*(X12*′X12*)−1X12*′X11*, and e2** = e2 − X22*(X12*′X12*)−1X12*′ε1*. Here we particularly notice that the two regression errors in (14), M2ε1* and e2**, are uncorrelated as a result of cov(e2, ε1*) = 0, var(ε1*) = σ2In, and X12*′M2 = 0. Then, if the error vector of the original regression model (3), (ε1′, ε2′)′, is distributed as multivariate normal, the conditional distribution of y2** given y1 and X is also multivariate normal, its covariance matrix does not depend on β1, and its conditional mean is X21** β1. Thus, by the definition of y2** = (y2 − V21V11−1y1) − X22*(X12*′X12*)−1X12*′V11−1/2y1, we can deduce that the conditional distribution of y2 given y1 and X is also normal, its covariance matrix does not depend on β1, and its conditional mean is V21V11−1y1 + X22*(X12*′X12*)−1X12*′V11−1/2y1 + X21** β1, which does not depend on the unknown parameter vector β1, if, and only if, X21** = 0. Now, let A = A2A1 and Q = I. Then, the linear structure (A,Q) is sufficient for the BLUE of β1 in the sense of Gourieroux and Monfort (1980) if, and only if, X21** = 0, which, by the definition of X21** in (14), is just the necessary and sufficient condition given in Theorem 3. This conditional distribution interpretation of the partially superfluous condition (12) of Theorem 3 is in principle the same as the approach used by Gourieroux and Monfort (1980, p. 1093) for deriving their necessary and sufficient condition for the second subsample to be fully superfluous for the BLUE of the whole parameter vector β.
Remarks.
(1) It is interesting to observe that the necessary and sufficient condition for the second subsample to be partially superfluous for the BLUE of β1 does not depend on V22, as long as the covariance matrix σ2V is positive definite.
(2) Notice that the fully superfluous condition (5) of Gourieroux and Monfort (1980, p. 1093) is X2[bull ] = V21V11−1X1[bull ], which implies X21 = V21V11−1X11 and X22 = V21V11−1X12. Thus, we can easily see that the fully superfluous condition (5) is sufficient but not necessary for the partially superfluous condition (12).
APPENDIX
Proof of Lemma 2. We first note that
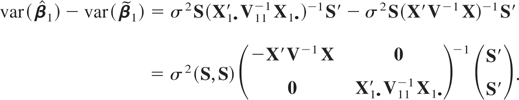
Thus using rk(A) = rk(−A) and Lemma 1(i), we have

using rk(X) = rk(X1[bull ]) = K. Now, substituting the definition of S = (IK1,0) into the block matrix in the first term of (A.1) and simplifying it by elementary block matrix operations, we have

using rk(X12) = K2 and K = K1 + K2. Now, substituting (A.2) into the first term of (A.1), we easily obtain

We now proceed to find the rank of the matrix of the first term on the right-hand side of (A.3). In fact, using the definition of X and V1 = (V11,V12)′ and the formula (9), we have

By substituting it into (A.3), the rank expression given in (11) of Lemma 2 follows immediately. █
References
REFERENCES
Gourieroux, C. &
A. Monfort
(1980)
Sufficient linear structures: Econometric applications.
Econometrica
48,
1083–1097.Google Scholar
Marsaglia, G. &
G.P.H. Styan
(1974)
Equalities and inequalities for ranks of matrices.
Linear and Multilinear Algebra
2,
269–292.Google Scholar
 You have
Access
- 16
- Cited by