





1. Introduction
Linear combinations of random variables play a crucial role in various fields, including statistics, operations research, reliability theory, and actuarial science. The comparison of such linear combinations, particularly in terms of their variability or riskiness, has been a subject of extensive study. Let
 $X_1, \dots, X_n$
be independent and identically distributed (i.i.d.) random variables. Given two non-negative real vectors
 $(\theta_1, \dots, \theta_n)$
and
 $(\eta_1, \dots, \eta_n)$
such that
 $(\theta_1, \dots, \theta_n)$
is smaller than
 $(\eta_1, \dots, \eta_n)$
in majorization order (see Definition 1), a typical problem in this area is to compare
 $\sum_{i=1}^n \theta_i X_i$
and
 $\sum_{i=1}^n \eta_i X_i$
via some notion of stochastic dominance. Generally speaking, a smaller vector in majorization order is more evenly distributed across its coordinates.
An important early contribution is [Reference Proschan26], which showed that for i.i.d. symmetric log-concave random variables
 $X_1, \dots, X_n$
,
 $\sum_{i=1}^n \theta_i X_i$
is more peaked than
 $\sum_{i=1}^n \eta_i X_i$
, i.e.
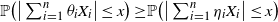 $\mathbb{P}\big(\big|\sum_{i=1}^n {\theta_i X_i\big|\le x\big) \ge} \mathbb{P}\big(\big|\sum_{i=1}^n \eta_i X_i\big|\le x\big)$
for all
 $x>0$
. That is, a more equal distribution of weights leads to a less variable linear combination. This remarkable result was subsequently extended and found applications in economics, statistics, and operations research; see, e.g., [Reference Ibragimov12] and the references therein. For instance, [Reference Ma18] extended Proschan’s result to independent but not necessarily identically distributed random variables. Subsequently, [Reference Ma19] compared linear combinations of random variables using decreasing convex order and Laplace transform order; see [Reference Mao, Pan and Hu20, Reference Xu and Hu30, Reference Zhao, Chan and Ng31] for studies with other notions of stochastic orders.
Of particular note is the extension of [Reference Proschan26] established in [Reference Ibragimov12], which showed that the peakedness property for log-concave distributions continues to hold for stable distributions with finite mean. A closely related result is that for all i.i.d. finite-mean
 $X_1,\dots,X_n$
,
 $\sum_{i=1}^n \theta_i X_i$
is smaller than
 $\sum_{i=1}^n \eta_i X_i$
in convex order (see, e.g., [Reference Shaked and Shanthikumar27, Theorem 3.A.35] and [Reference Denuit, Dhaene, Goovaerts and Kaas8, Property 3.4.48]); a random variable X is said to be smaller than a random variable Y in the convex order if
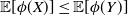 $\mathbb{E} [\phi(X)]\le \mathbb{E} [\phi(Y)]$
for all convex functions
 $\phi\colon\mathbb{R}\to\mathbb{R}$
, provided that both expectations exist. This implies that
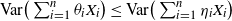 $\mathrm{Var}\big(\sum_{i=1}^n \theta_i X_i\big)\le \mathrm{Var}\big(\sum_{i=1}^n \eta_i X_i\big)$
provided that
 $X_1,\dots,X_n$
have a finite second moment. The above peakedness property and the relation in convex order both suggest that
 $\sum_{i=1}^n \theta_i X_i$
is less spread out than
 $\sum_{i=1}^n \eta_i X_i$
.
One key assumption for the above results to hold is that the random variables have a finite mean. If the mean of the random variables is infinite, the observations can be quite different or even flipped; see [Reference Chen and Wang6] for a survey of infinite-mean models in the realms of finance and insurance. For instance, if
 $X_1,\dots, X_n$
are i.i.d. stable random variables with a tail parameter strictly less than 1 (thus infinite mean), [Reference Ibragimov12] showed that
 $\sum_{i=1}^n \theta_i X_i$
is less peaked than
 $\sum_{i=1}^n \eta_i X_i$
; hence a more balanced weight vector leads to a more dispersed linear combination. If the stable random variables are positive almost surely, this result can be written equivalently as
 \begin{equation} \sum_{i=1}^n \eta_i X_i \leq_\mathrm{st} \sum_{i=1}^n \theta_i X_i \quad \mathrm{for}\, (\theta_1, \dots, \theta_n) \preceq (\eta_1, \dots, \eta_n),\end{equation}
where
 $\leq_\mathrm{st}$
denotes the usual stochastic order and
 $\preceq$
denotes majorization order. For two random variables X and Y, X is said to be smaller than Y in the usual stochastic order if
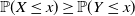 $\mathbb{P}(X\le x)\ge \mathbb{P}(Y\le x)$
for all
 $x\in\mathbb{R}$
; for properties of stochastic orders, we refer to [Reference Müller and Stoyan23, Reference Shaked and Shanthikumar27].
In recent years, a growing body of research has focused on (1) and related stochastic dominance relations for extremely heavy-tailed random variables, i.e. the means of the random variables are infinite or do not exist. [Reference Chen, Hu, Wang and Zou4] extended (1) to extremely heavy-tailed Pareto random variables that are not necessarily identically distributed; the case of two i.i.d. Pareto random variables with tail parameter
 $\frac12$
was previously studied in [Reference Embrechts, McNeil and Straumann10]. Several studies considered an important case of (1):
 \begin{equation} \Bigg(\sum_{i=1}^n \theta_i\Bigg) X_1 \leq_\mathrm{st} \sum_{i=1}^n \theta_i X_i,\end{equation}
where
 $(\theta_1, \dots, \theta_n)$
is a non-negative vector. [Reference Chen, Embrechts and Wang3] established (2) for weakly negatively associated super-Pareto random variables. Later, [Reference Arab, Lando and Oliveira1, Reference Chen and Shneer5, 22] provided other sufficient conditions of
 $X_1,\dots,X_n$
for which (2) holds.
Despite these advances, existing proofs of (1) rely heavily on the specific mathematical structures of the distributions considered. The arguments in [Reference Ibragimov12] rely on the fact that linear combinations of i.i.d. stable random variables remain stable, while those in [Reference Chen, Hu, Wang and Zou4] are tailored to the Pareto family. Consequently, a unifying framework that encompasses a wide range of extremely heavy-tailed distributions has remained elusive. This paper fills the gap by providing a general sufficient condition for the stochastic dominance relation (1). Moreover, we provide, for the first time, necessary conditions within a particular class of distributions.
Inequality (1) provides an intuitive implication in portfolio diversification: a more diversified portfolio of i.i.d. infinite-mean risks is stochastically larger. An early observation of the negative effect of diversification dates back to [Reference Fama and Miller11, p. 271], which showed that diversification can make portfolios more spread out for infinite-mean risks. The superadditivity of the regulatory risk measure value-at-risk (VaR) was noted by [Reference Nešlehová, Embrechts and Chavez-Demoulin24] in the context of operational risks, which can have infinite mean. [Reference Ibragimov13] showed that VaR is superadditive for infinite-mean stable distributions at quantile levels greater than 0.5. The economic analysis in [Reference Ibragimov, Jaffee and Walden14] suggested that diversification is suboptimal for infinite-mean risks from the perspectives of both financial intermediaries and society. An application of (1) to the optimal bundling problems can be found in [Reference Ibragimov and Walden15].
We summarize our contributions below.
-
• With majorization theory, we show that (1) holds for a new class of distributions, referred to as inverted concave distributions (Theorem 1). This class includes many commonly used heavy-tailed distributions, such as the Pareto distributions and the Fréchet distributions, all with infinite mean. Together with some simple closure properties of the inverted concave distributions (Propositions 4 and 5), we demonstrate that the new class is rather rich. As mentioned before, the techniques used in [Reference Chen, Hu, Wang and Zou4, Reference Ibragimov12] are designed specifically for Pareto and stable distributions respectively, and there does not seem to be a way to generalize them to other distributions. We develop and apply different methods to prove our main result in Theorem 1.
-
• Assuming that each of
 $X_1,\dots,X_n$
in (1) follows a compound Poisson distribution, which is a standard model for portfolio claims and aggregate risks in banking and insurance sectors (see, e.g., [Reference Kaas, Goovaerts and Dhaene16]), we show that (1) holds if and only if the distribution of each summand is inverted concave. This, to the best of our knowledge, is the first necessary result for (1) to hold.

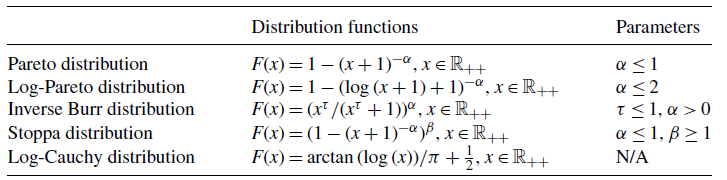
The rest of this paper is organized as follows. Section 2 introduces the class of inverted concave distributions and establishes (1) for this class. Section 3 studies (1) for the compound Poisson distribution. Section 4 presents further discussions of (1) for stable distributions, complementing the findings of [Reference Ibragimov12], which focused on the peakedness property of linear combinations of stable random variables. Section 5 concludes the paper with some open questions. The appendices provide more details for Table 1, which contains further examples of inverted concave distributions, as well as a simulation procedure for stable distributions used in the numerical illustration.
1.1. Notation
We fix some notation here. Denote by
 $\mathbb{N}$
the set of all positive integers,
 $\mathbb{R}_+$
the set of all non-negative real numbers, and
 $\mathbb{R}_{++}$
the set of all positive real numbers. Let
 $\mathbb{N}_0=\mathbb{N}\cup\{0\}$
. For
 $n\in\mathbb{N}$
, let
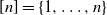 $[n]=\{1,\dots,n\}$
. Throughout, n is assumed to be greater than or equal to 2. We use
 $\overline \theta$
and
 $\overline \eta$
to denote the vectors
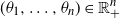 $(\theta_1,\dots,\theta_n)\in\mathbb{R}_+^n$
and
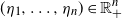 $(\eta_1,\dots,\eta_n)\in\mathbb{R}_+^n$
, respectively. Denote by
 $\varphi_X$
the characteristic function of a random variable X. For a distribution function F, denote its tail function by
 $\overline{F} = 1 - F$
and its essential infimum by
 $\operatorname{ess-inf}F$
. We use
 $\simeq_\mathrm{st}$
for equality in distribution.
2. Stochastic dominance and a class of distributions
2.1. A stochastic dominance relation
We first recall the notion of majorization order. For a vector
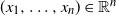 $(x_1,\dots,x_n)\in\mathbb{R}^n$
, denote by
 $x_{(i)}$
the ith-smallest order statistic of
 $(x_1,\dots,x_n)$
.
Definition 1. For two vectors
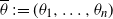 $\overline{\theta} \,:\!= (\theta_1,\dots,\theta_n)$
and
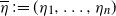 $\overline{\eta} \,:\!= (\eta_1,\dots,\eta_n)$
in
 $\mathbb{R}^n$
, we say that:
-
(i)
$\overline{\theta}$
is dominated by
$\overline{\eta}$
in weak supermajorization order, denoted by
$\overline{\theta} \preceq^\mathrm{w} \overline{\eta}$
, if
$\sum^k_{i=1}\theta_{(i)} \ge \sum^k_{i=1} \eta_{(i)}$
for all
$k\in [n]$
; -
(ii)
$\overline{\theta}$
is dominated by
$\overline{\eta}$
in majorization order, denoted by
$\overline{\theta} \preceq \overline{\eta}$
, if
$\overline{\theta} \preceq^\mathrm{w} \overline{\eta}$
and
$\sum^n_{i=1}\theta_i = \sum^n_{i=1}\eta_i$
.


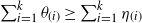


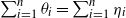
The main focus of the paper is on studying the following stochastic dominance relation:
 \begin{equation} \sum_{i=1}^n\eta_i X_i \le_\mathrm{st} \sum_{i=1}^n\theta_i X_i \quad \text{for all $\overline\theta,\overline\eta\in\mathbb{R}^n_+$ such that $\overline\theta \preceq \overline\eta$}, \end{equation}
where
 $X_1, \dots, X_n$
are i.i.d. random variables. Let X be a copy of
 $X_1, \dots, X_n$
. If
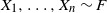 $X_1, \dots, X_n\sim F$
satisfy (SD), we also say X or F satisfies (SD). For some
 $x\in\mathbb{R}$
, let
 \begin{align*}g_x(\theta_1,\dots,\theta_n) = \mathbb{P}\Bigg(\sum_{i=1}^n \theta_i X_i > x\bigg), \quad\overline\theta\in\mathbb{R}^n_+. \end{align*}
Then (SD) holds if and only if
 $g_x$
is Schur-concave on
 $\mathbb{R}^n_+$
for all
 $x \in \mathbb{R}$
; recall that a function f on
 $\mathbb{R}^n$
is Schur-concave if
 $f(\overline\theta) \kern-0.5pt\ge f(\overline\eta)$
whenever
 $\overline\theta \kern-0.5pt\preceq\kern-0.5pt \overline\eta$
.
We now present some elementary properties of (SD).
Proposition 1. The following statements hold.
-
(i) If random variable X satisfies (SD), then either X is a constant or
$\mathbb{E}[|X|]$
is infinite. -
(ii) If two independent random variables X and Y satisfy (SD), then
$X+Y$
satisfies (SD). -
(iii) If random variable X satisfies (SD), then
$(X+a)/b$
satisfies (SD) for all
$a\in\mathbb{R}$
and
$b \in \mathbb{R}_{++}$
. -
(iv) If random variable
$Y_k$
with any
$k \in \mathbb{N}$
satisfies (SD) and
$Y_k\xrightarrow{\mathrm{d}}X$
, then X satisfies (SD).


Proof. If X is a constant, (SD) clearly holds. For a non-degenerate random variable X, since (SD) implies that
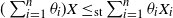 $(\sum_{i=1}^n\theta_i)X \le_\mathrm{st} \sum_{i=1}^n\theta_i X_i$
, by [22, Theorem 2.3(b)],
 $\mathbb{E}[|X|]=\infty$
. Statement (ii) is because the usual stochastic order is preserved under convolution (see, e.g., [Reference Shaked and Shanthikumar27, Theorem 1.A.3(b)]). Statement (iii) is trivial. Statement (iv) holds as the usual stochastic order is preserved under convergence in distribution [Reference Müller and Stoyan23, Theorem 1.2.14].
Remark 1. Property (SD) implies that
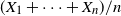 $(X_1+\dots+X_n)/n$
is increasing in the usual stochastic order as n increases, since
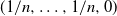 $(1/n,\dots,1/n,0)$
dominates
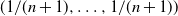 $(1/(n+1),\dots,1/(n+1))$
in majorization order for all n. By Proposition 1, if
 $X_1$
satisfies (SD) and
 $X_1$
is non-degenerate and bounded from below, we have
 $\mathbb{E}[X_1]=\infty$
. Then, by the law of large numbers,
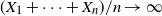 $(X_1+\dots+X_n)/n\rightarrow \infty$
almost surely as n goes to infinity [Reference Durrett9, Theorem 2.4.5].
2.2. Inverted concave distributions
Next, we introduce a class of distributions for non-negative random variables, namely the inverted concave distribution. We will show later that this rather large class of distributions satisfies property (SD) and thus, by Proposition 1, the inverted concave distributions have infinite mean.
Definition 2. Let F be a distribution function with
 $\operatorname{ess-inf} F=0$
. We say that F is inverted concave, denoted by
 $F\in\mathcal{H}$
, if
 $\overline F(1/x)$
is concave in
 $x\in\mathbb{R}_{++}$
. For
 $X\sim F$
where
 $F\in\mathcal{H}$
, we also write
 $X\in\mathcal{H}$
.
For a continuous random variable X, its inverted distribution is defined as
 $\mathbb{P}(1/X \leq x)$
,
 ${x\in\mathbb{R}}$
. If X is inverted concave, for
 $x>0$
,
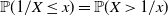 $\mathbb{P}(1/X\le x)=\mathbb{P}(X> 1/x)$
is concave, i.e. the inverted distribution of X is concave; hence the name. The following result for the inverted concave class will be useful later.
Proposition 2. If
 $F\in\mathcal{H}$
, then
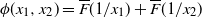 $\phi(x_1,x_2) = \overline{F}({1}/{x_1}) + \overline{F}({1}/{x_2})$
,
 $(x_1,x_2)\in \mathbb{R}_{++}^2$
, is Schur-concave. Conversely, if F is continuous and
 $\phi$
is Schur-concave,
 $F\in \mathcal{H}$
. In addition, if F has density f, then
 $F\in\mathcal{H}$
if and only if
 $x^2\, f(x)$
is increasing in
 $x\in\mathbb{R}_{++}$
.
Proof. By [Reference Marshall, Olkin and Arnold21, Section 3.C.1], if
 $g\colon\mathbb{R}_+\rightarrow \mathbb{R}_+$
is concave, then
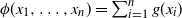 $\phi(x_1,\dots,x_n)=\sum_{i=1}^n g(x_i)$
is Schur-concave in
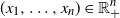 $(x_1,\dots,x_n)\in\mathbb{R}_+^n$
. By [Reference Marshall, Olkin and Arnold21, Section 3.C.1.c], for a continuous function g on an interval I, if
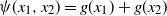 $\psi(x_1,x_2)=g(x_1)+g(x_2)$
is Schur-concave on
 $I^2$
, then g is concave.
Remark 2. If distributions have densities of the form
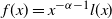 $f(x) = x^{-\alpha-1} l(x)$
, where the function l is increasing and
 $\alpha \in (0,1]$
, the distributions are inverted concave by Proposition 2. In addition, if l is a slowly varying function, by the Karamata representation (see, e.g., [Reference de Haan and Ferreira7, Theorem B.1.6]), it may be written as
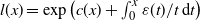 $l(x) = \exp\big(c(x) + \int_0^x{\varepsilon(t)}/{t}\,\mathrm{d}t\big)$
, where
 $c(x) \to c$
as
 $x \to \infty$
and
 $\varepsilon(x) \to 0$
as
 $x \to \infty$
. If c is increasing and
 $\varepsilon$
is non-negative, the distributions are inverted concave.
We can use Proposition 2 together with Remark 2 to show that many commonly used heavy-tailed distributions are inverted concave. We present some examples below. Additional examples are collected in Table 1; see Appendix A for more details of Table 1. Some closure properties of inverted concave distributions are collected in Section 2.4.
Further examples of inverted concave distributions.

Table 1 Long description
Panel A: The table lists the Pareto distribution with the function F of x equals 1 minus open parenthesis x plus 1 close parenthesis raised to the power of negative alpha, where x is in the set of positive real numbers and alpha is less than or equal to 1. Panel B: The Log-Pareto distribution is defined by F of x equals 1 minus open parenthesis the logarithm of open parenthesis x plus 1 close parenthesis plus 1 close parenthesis raised to the power of negative alpha, where x is in the set of positive real numbers and alpha is less than or equal to 2. Panel C: The Inverse Burr distribution is given by F of x equals open parenthesis x raised to the power of tau divided by open parenthesis x raised to the power of tau plus 1 close parenthesis close parenthesis raised to the power of alpha, where x is in the set of positive real numbers, tau is less than or equal to 1, and alpha is greater than 0. Panel D: The Stoppa distribution is defined by F of x equals 1 minus open parenthesis 1 minus open parenthesis x plus 1 close parenthesis raised to the power of negative beta close parenthesis raised to the power of negative alpha, where x is in the set of positive real numbers, alpha is less than or equal to 1, and beta is greater than or equal to 1. Panel E: The Log-Cauchy distribution is given by F of x equals the arctangent of the logarithm of x divided by pi plus one half, where x is in the set of positive real numbers.
Example 1. (Fréchet distribution.) The Fréchet distribution function is
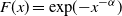 $F(x)=\exp\!({-}x^{-\alpha})$
,
 $x \in \mathbb{R}_{++}$
. As its density function is
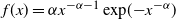 $f(x)=\alpha x^{-\alpha-1}\exp\!({-}x^{-\alpha})$
for
 $x \in \mathbb{R}_{++}$
, by Remark 2,
 $F\in\mathcal{H}$
if
 $\alpha\le 1$
.
Example 2. (Absolute Cauchy distribution.) The absolute Cauchy distribution is defined as
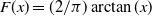 $F(x)=(2/\pi)\arctan(x)$
for
 $x \in \mathbb{R}_{++}$
. As the density function is
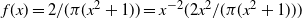 $f(x)=2/(\pi(x^2+1))=x^{-2}(2x^2/(\pi(x^2+1)))$
for
 $x \in \mathbb{R}_{++}$
, by Remark 2, we have
 $F \in \mathcal{H}$
.
Example 3. (Inverse Gamma distribution.) The density function of the inverse Gamma distribution with parameters
 $\alpha,\beta \in \mathbb{R}_{++}$
is
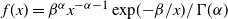 $f(x) = \beta^\alpha x^{-\alpha-1}\exp\!({-}\beta/x)/\Gamma(\alpha)$
,
 $x \in \mathbb{R}_{++}$
. By Remark 2, if
 $\alpha\le 1$
and
 $\beta \in \mathbb{R}_{++}$
, we have
 $F \in \mathcal{H}$
. The inverse Gamma distribution with
 $\alpha=0.5$
is the Lévy distribution, which also belongs to the class of stable distributions.
Example 4. (Feller–Pareto distribution.) The Feller–Pareto distribution with parameters
 ${\mu\in\mathbb{R}}$
and
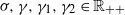 $\sigma,\gamma,\gamma_1, \gamma_2 \in \mathbb{R}_{++}$
, denoted by
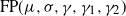 $\operatorname{FP}\!(\mu,\sigma,\gamma,\gamma_1, \gamma_2)$
, has the density function
 \begin{align*} f(x) = \frac{1}{\gamma\sigma B(\gamma_1,\gamma_2)}\bigg(\frac{x-\mu}{\sigma}\bigg)^{(\gamma_2/\gamma)-1} \bigg(1+\left(\frac{x-\mu}{\sigma}\right)^{1/\gamma}\bigg)^{-\gamma_1-\gamma_2}, \quad x>\mu, \end{align*}
where B is the beta function. The class of Feller–Pareto distributions is very general. If
 $\gamma_2=1$
, the Feller–Pareto distribution becomes the Pareto type-IV distribution (
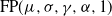 $\operatorname{FP}\!(\mu,\sigma, \gamma,\alpha,1)$
), which includes the Pareto type-III distribution (
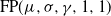 $\operatorname{FP}\!(\mu,\sigma,\gamma,1,1)$
), the Pareto type-II distribution (
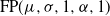 $\operatorname{FP}\!(\mu,\sigma,1,\alpha,1)$
), and the Pareto type-I distribution (
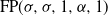 $\operatorname{FP}\!(\sigma,\sigma,1,\alpha,1)$
). Note that the Pareto type-IV distribution is essentially the Burr distribution. See [Reference Arnold2] for the statistical properties of the Feller–Pareto distribution. Assume that
 $\mu=0$
and
 $\sigma=1$
, and let
 $h(x)=x^2f(x)$
for
 $x\in\mathbb{R}_+$
. Taking the derivative of h, we have
 \begin{align*} h'(x) = \frac{x^{\gamma_2/\gamma}((x^{1/\gamma}+1)^{-\gamma_1-\gamma_2-1}((\gamma-\gamma_1)x^{1/\gamma} +\gamma_2+\gamma))} {\gamma^2 B(\gamma_1,\gamma_2)}. \end{align*}
If
 $\gamma\ge \gamma_1$
, i.e. the Feller–Pareto distribution has infinite mean, h is increasing. By Proposition 2, the Feller–Pareto distribution is inverted concave if
 $\gamma\ge\gamma_1$
.
2.3. Main result
Let
 $\overline {\theta}$
and
 $\overline {\eta}$
be two vectors in
 $\mathbb{R}^n$
. Then
 $\overline {\theta}$
is a T-transform of
 $\overline {\eta}$
if, for some
 $\lambda \in [0,1]$
and
 $i,j\in [n]$
with
 $i \neq j$
,
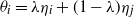 $\theta_i=\lambda \eta_i + (1-\lambda)\eta_j$
,
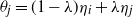 $\theta_j= (1-\lambda)\eta_i+\lambda \eta_j$
, and
 $\theta_k=\eta_k$
for
 $k\in [n]\setminus \{i,j\}$
. The following lemma will be useful in our proof.
Lemma 1. ([Reference Marshall, Olkin and Arnold21, Section 1.A.3].) For
 $\overline \theta, \overline \eta\in \mathbb{R}^n$
,
 $\overline \theta\preceq \overline \eta$
if and only if
 $\overline \theta$
can be obtained from
 $\overline\eta$
by a finite number of T-transforms.
Theorem 1. If
 $F\in \mathcal{H}$
, then F satisfies (SD).
Proof. We first show that it is sufficient to prove the theorem for the case of two random variables. By Lemma 1, it suffices to assume that
 $\overline \theta$
is obtained from
 $\overline \eta$
by a T-transform, i.e. only two components in
 $\overline \theta$
and
 $\overline \eta$
are different. Write
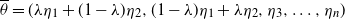 $\overline\theta=(\lambda\eta_1+(1-\lambda)\eta_2,(1-\lambda)\eta_1+\lambda\eta_2,\eta_3,\dots,\eta_n)$
for some
 $\lambda\in[0,1]$
. If the statement of the theorem is correct for two random variables, then
 \begin{align*} \theta_1X_1 + \theta_2X_2 = (\lambda\eta_1 + (1-\lambda)\eta_2)X_1 + ((1-\lambda)\eta_1 + \lambda\eta_2)X_2 \ge_\mathrm{st} \eta_1 X_1 + \eta_2 X_2. \end{align*}
Then, as
 $X_1,\dots,X_n$
are independent and the usual stochastic order is closed under convolution (see, e.g., [Reference Shaked and Shanthikumar27, Theorem 1.A.3(b)]),
 \begin{align*} \sum_{i=1}^n \theta_i X_i & = (\lambda\eta_1 + (1-\lambda)\eta_2)X_1 + ((1-\lambda)\eta_1 + \lambda\eta_2)X_2 + \sum_{i=3}^n\eta_i X_i \\ & \ge_\mathrm{st} \eta_1 X_1 + \eta_2 X_2 + \sum_{i=3}^n \eta_i X_i=\sum_{i=1}^n \eta_i X_i. \end{align*}
It therefore remains to prove the theorem in the case
 $n=2$
. It is clear that we can restrict ourselves to the case
 $\theta_1+\theta_2=1$
. It is also clear that, due to symmetries, it is sufficient to show that
 \begin{equation} \mathbb{P}(\theta X_1 + (1-\theta) X_2 > x) \ge \mathbb{P}(\eta X_1 + (1-\eta) X_2 > x) \end{equation}
holds for all
 $0 \le \eta \le \theta \le \frac12$
and for all
 $x\in\mathbb{R}$
. To this end, for
 $a \in (0,1)$
, write
 \begin{align} & \mathbb{P}(a X_1 + (1-a) X_2 > x) \nonumber \\[3pt] & = \mathbb{P}(X_1 > x,X_2 > x ) + \mathbb{P}(X_1\le x, a X_1 + (1-a) X_2 > x) + \mathbb{P}(X_2\le x, a X_1 + (1-a) X_2 > x) \nonumber \\[3pt] & = \mathbb{P}(X_1 > x,X_2 > x ) + \int_{y=0}^x\overline{F}\bigg(\frac{x-a y}{1-a}\bigg)\,\mathrm{d}F(y) + \int_{y=0}^x\overline{F}\bigg(\frac{x-(1-a) y}{a}\bigg)\,\mathrm{d}F(y). \end{align}
From the above, it is now clear that, in order to show that (3) holds for all
 $0 < \eta \le \theta \le \frac12$
and for all
 $x\in\mathbb{R}$
, it is sufficient to show that
 \begin{equation*} \overline{F}\bigg(\frac{x-\theta y}{1-\theta}\bigg) + \overline{F}\bigg(\frac{x-(1-\theta) y}{\theta}\bigg) \ge \overline{F}\bigg(\frac{x-\eta y}{1-\eta}\bigg) + \overline{F}\bigg(\frac{x-(1-\eta) y}{\eta}\bigg) \end{equation*}
for all
 $y \le x$
and for all
 $0 < \eta \le \theta \le \frac12$
. This can be rewritten as
 \begin{equation} \overline{F}\bigg(y + \frac{x-y}{1-\theta}\bigg) + \overline{F}\bigg(y+\frac{x-y}{\theta}\bigg) \ge \overline{F}\bigg(y+\frac{x-y}{1-\eta}\bigg) + \overline{F}\bigg(y+\frac{x-y}{\eta}\bigg) \end{equation}
and, with conditions above, (5) can also be stated as
 \begin{equation} \overline{F}\bigg(y + \frac{z}{1-\theta}\bigg) + \overline{F}\bigg(y+\frac{z}{\theta}\bigg) \ge \overline{F}\bigg(y+\frac{z}{1-\eta}\bigg) + \overline{F}\bigg(y+\frac{z}{\eta}\bigg) \end{equation}
for all
 $y,z \in \mathbb{R}_+$
and for all
 $0 < \eta \le \theta \le \frac12$
. The above holds if
 $z=0$
and thus we only need to consider the case
 $ z\in \mathbb{R}_{++}$
. Let
 $h(x)=\overline F(1/x)$
for
 $x\in\mathbb{R}_{++}$
and
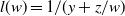 $l(w)=1/(y+z/w)$
for
 $w\in \mathbb{R}_{++}$
, where
 $y\in \mathbb{R}_{+}$
and
 $z\in \mathbb{R}_{++}$
. Since
 $F\in\mathcal{H}$
, h is concave. It is easy to check that l is also concave. By Lemma 1, there exists some
 $\lambda\in[0,1]$
such that
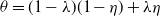 $\theta=(1-\lambda) (1-\eta) + \lambda \eta$
and
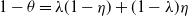 $1-\theta=\lambda (1-\eta) + (1-\lambda) \eta$
. Therefore, we have
 \begin{align*} \overline{F}\bigg(y + \frac{z}{1-\theta}\bigg) + \overline{F}\bigg(y+\frac{z}{\theta}\bigg) & = h(l(1-\theta))+h(l(\theta)) \\[3pt] & = h(l(\lambda (1-\eta) + (1-\lambda) \eta))+h(l((1-\lambda) (1-\eta) + \lambda \eta)) \\[3pt] & \ge h(\lambda l(1-\eta)+ (1-\lambda) l (\eta))+h((1-\lambda) l (1-\eta)+ \lambda l(\eta)) \\[3pt] & \ge h(l(1-\eta))+h(l(\eta)) = \overline{F}\bigg(y+\frac{z}{1-\eta}\bigg) + \overline{F}\bigg(y+\frac{z}{\eta}\bigg). \end{align*}
Hence, (3) holds for
 $0 < \eta \le \theta \le \frac12$
. Moreover, for any
 $a\in(0,1)$
,
 \begin{align} & \mathbb{P}(a X_1 + (1-a) X_2 > x) \nonumber \\[3pt] & = \mathbb{P}(X_1 > x,X_2 > x) + \int_{y=0}^x\overline{F}\bigg(\frac{x-a y}{1-a}\bigg)\,\mathrm{d}F(y) + \int_{y=0}^x\overline{F}\bigg(\frac{x-(1-a) y}{a}\bigg)\,\mathrm{d}F(y) \nonumber \\[3pt] & \ge \mathbb{P}(X_1 > x, X_2 > x) + \int_{y=0}^x\overline{F}\bigg(\frac{x}{1-a}\bigg)\,\mathrm{d}F(y) + \int_{y=0}^x\overline{F}\bigg(\frac{x}{a}\bigg)\,\mathrm{d}F(y) \\ & \ge \mathbb{P}(X_1 > x,X_2 > x ) + \int_{y=0}^x\overline{F}(x)\,\mathrm{d}F(y) \\[3pt] & = \mathbb{P}(X_1 > x,X_2 > x) + \mathbb{P}(X_1 > x,X_2\le x) = \mathbb{P}(X_1 > x). \nonumber \end{align}
Inequality (7) is due to Proposition 2 and the right-continuity of
 $\overline F$
. Hence, (3) holds for
 $\eta=0$
. The proof is complete.
Remark 3. The proof of Theorem 1 is significantly different from [Reference Ibragimov12] and [Reference Chen, Hu, Wang and Zou4], which established (SD) for some infinite-mean stable distributions and all infinite-mean Pareto distributions, respectively. [Reference Ibragimov12] mainly used the fact that a linear combination of i.i.d. stable random variables follows the stable distribution; see Section 4. The techniques in [Reference Chen, Hu, Wang and Zou4] depend on the assumption of Pareto distributions and have been used to derive a more general version of (SD) for non-identically distributed Pareto random variables. On the other hand, our proof utilizes the symmetry property of functions and thus does not seem to work for non-identical distributions.
Remark 4. We note that (SD) can also hold for random variables that are not bounded from below. A classic example is the standard Cauchy distribution, with the distribution function given by
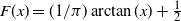 $F(x)=({1}/{\pi})\arctan(x) + \frac{1}{2}$
,
 $x\in\mathbb{R}$
. It is well known that for i.i.d. standard Cauchy random variables
 $X_1,\dots,X_n$
and for any
 $\overline\theta\in\mathbb{R}_+^n$
,
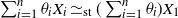 $\sum_{i=1}^n\theta_iX_i \simeq_\mathrm{st} (\sum_{i=1}^n\theta_i)X_1$
and thus (SD) holds. A question is whether the proof of Theorem 1 can be generalized to incorporate distributions like the standard Cauchy distribution. This does not seem to be easy as (6) may flip for some negative y. Indeed, from (4), we can see that to let (SD) hold for an arbitrary distribution F, a sufficient and necessary condition is that
 \begin{align*} \int_{y=\operatorname{ess-inf} F}^x\overline{F}\bigg(\frac{x-a y}{1-a}\bigg)\,\mathrm{d}F(y) + \int_{y=\operatorname{ess-inf} F}^x\overline{F}\bigg(\frac{x-(1-a) y}{a}\bigg)\,\mathrm{d}F(y) \end{align*}
is increasing in
 $a\in\big[0,\frac12\big]$
for all
 $x\in\mathbb{R}$
. This condition can still hold if (6) does not hold for some values of y.
Theorem 1 can be easily generalized to the case where the associated weight vectors of (SD) are ordered in weak supermajorization order.
Proposition 3. Let
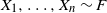 $X_1,\dots,X_n\sim F$
be i.i.d., where
 $F\in\mathcal H$
. For vectors
 $(\theta_1,\ldots,\theta_n)$
and
 $(\eta_1,\ldots,\eta_n)$
in
 $\mathbb{R}^n_+$
such that
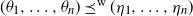 $(\theta_1,\ldots,\theta_n) \preceq^\mathrm{w} (\eta_1,\ldots,\eta_n)$
,
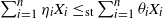 $\sum_{i=1}^n \eta_i X_i \leq_\mathrm{st} \sum_{i=1}^n \theta_i X_i$
.
Proof. If
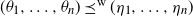 $(\theta_1,\ldots,\theta_n) \preceq^\mathrm{w} (\eta_1,\ldots,\eta_n)$
, by [Reference Marshall, Olkin and Arnold21, Section 5.A.9a] there exist
 $(\lambda_1,\ldots,\lambda_n)$
such that
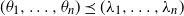 $(\theta_1, \ldots, \theta_n) \preceq (\lambda_1, \ldots, \lambda_n)$
and
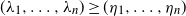 $(\lambda_1, \ldots, \lambda_n) \geq (\eta_1, \ldots, \eta_n)$
. Therefore, by Theorem 1, for all
 $x>0$
,
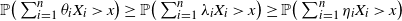 $\mathbb{P}\big(\sum_{i=1}^n \theta_i X_i > x\big) \geq \mathbb{P}\big(\sum_{i=1}^n \lambda_i X_i > x\big) \geq \mathbb{P}\big(\sum_{i=1}^n \eta_i X_i > x\big)$
. The proof is complete.
A particularly interesting case of (SD) relevant to risk sharing is
 \begin{equation} \Bigg(\sum_{i=1}^n \theta_i\Bigg) X_1 \le_\mathrm{st} \sum_{i=1}^n \theta_i X_i \quad \mbox{for all } \ \overline\theta\in\mathbb{R}_+^n, \end{equation}
where
 $X_1,\dots,X_n$
are i.i.d. random variables. Inequality (SD*) implies that any rational decision maker will not share infinite-mean losses; we say a decision maker is rational if they prefer loss X to loss Y for
 $X\le_\mathrm{st}Y$
. [Reference Chen, Embrechts and Wang3] recently showed that (SD*) holds if
 $X_1,\dots,X_n$
can be obtained via increasing and convex transformations of i.i.d. Pareto random variables with tail parameter 1; such random variables are called super-Pareto. Subsequently, this result was studied with broader classes of infinite-mean distributions in [Reference Arab, Lando and Oliveira1, Reference Chen and Shneer5, 22].
Definition 3. Let F be a distribution function with
 $\operatorname{ess-inf} F=0$
. We say F is inverted subadditive, denoted by
 $F\in \mathcal{H}^*$
, if
 \begin{equation*} \overline{F}\bigg(\frac{1}{x_1}\bigg) + \overline{F}\bigg(\frac{1}{x_2}\bigg) \ge \overline{F}\bigg(\frac{1}{x_1+x_2}\bigg) \quad \mbox{for all} \ (x_1,x_2)\in \mathbb{R}_{++}^2. \end{equation*}
The class of inverted subadditive distributions, introduced by [Reference Arab, Lando and Oliveira1], is clearly larger than the class of inverted concave distributions and contains the class of super-Pareto distributions. A random variable
 $X\in\mathcal{H}^*$
is called inverted subadditive because the inverted distribution of X is subadditive. [Reference Arab, Lando and Oliveira1, Theorem 3.1] established (SD*) for inverted subadditive distributions. This result is also implied by the last part of the proof of Theorem 1 (i.e. the inequality chain containing (7)).
Theorem 2. If
 $F\in \mathcal{H}^*$
, then F satisfies (SD*).
We refer to [Reference Arab, Lando and Oliveira1, Reference Chen and Shneer5, 22] for detailed discussions of (SD*). Variations of (SD*) were studied in [Reference Chen, Embrechts and Wang3, Reference Chen and Shneer5] for random variables that are possibly negatively dependent or non-identically distributed.
2.4. Some closure properties of
$\mathcal{H}$

This section presents some closure properties of
 $\mathcal{H}$
, which can be used to construct more distributions satisfying (SD). We first define some useful notions of stochastic orders.
Definition 4. For two random variables X and Y,
-
(i) X is less than Y in convex transform order, denoted
$X \leq_\mathrm{c} Y$
, if
$G^{-1}(F(x))$
is convex in x, where F and G are the distribution functions of X and Y, respectively; -
(ii) X is smaller than Y in likelihood ratio order, denoted by
$X\le_\mathrm{lr}Y$
, if
$g(x)/f(x)$
is increasing in x, where f and g are the densities of X and Y, respectively.


For continuous random variables X and Y, if
 $Y\simeq_\mathrm{st}\phi(X)$
for some increasing and convex function
 $\phi$
, then
 $X\le_\mathrm{c} Y$
; see [Reference Zwet32] for further discussion of convex transform order. Let U be uniformly distributed on (0, 1). Note that for continuous random variable X,
 $X\in\mathcal{H}$
if and only if
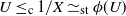 $U\le_\mathrm{c} 1/X\simeq_\mathrm{st}\phi(U)$
, where
 $\phi$
is convex satisfying
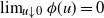 $\lim_{u\downarrow 0}\phi(u)=0$
and
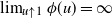 $\lim_{u\uparrow 1}\phi(u)=\infty$
.
Proposition 4. Let
 $X\sim F$
, where
 $F\in \mathcal{H}$
. Then:
-
(i)
$F^\beta\in \mathcal{H}$
, where
$\beta\ge 1$
; -
(ii)
$\phi(X)\in\mathcal{H}$
, where
$\phi$
is strictly increasing,
$\phi(0)=0$
, and
$1/\phi^{-1}(1/x)$
is concave in
$x\in\mathbb{R}_+$
; -
(iii) if
$Y\sim G$
is independent of X, where
$G\in\mathcal{H}$
, then
$\max\!\{X,Y\}\in\mathcal{H}$
; -
(iv) if, in addition, X and another random variable Y have densities and
$X\le_\mathrm{lr}Y$
, then
$Y\in\mathcal{H}$
.


Proof.
-
(i) Let
$G=F^\beta$
. Then
$\overline G(1/x)=1-(1-\overline F(1/x))^\beta$
,
$x \in \mathbb{R}_{++}$
. As
$\beta\ge 1$
,
$1-(1-x)^\beta$
is increasing and concave in
$x\in(0,1)$
. Since
$F\in\mathcal{H}$
,
$\overline G(1/x)$
is concave. -
(ii) Note that
$1/\phi(X)=g(1/X)$
, where
$g(x)=1/\phi(1/x)$
,
$x>0$
. Since
$1/\phi^{-1}(1/x)$
is strictly increasing and concave, g is strictly increasing and convex. Thus
$U\le_\mathrm{c}1/X\le_\mathrm{c}1/\phi(X)$
and
$\phi(X)\in\mathcal{H}$
. -
(iii) It suffices to show that
$U\le_\mathrm{c}1/\max\!(X,Y)$
. Let strictly increasing and convex functions f, g be such that
$1/X\simeq_\mathrm{st}f(U)$
and
$1/Y\simeq_\mathrm{st}g(U)$
. For
$x>0$
,
$\mathbb{P}(1/\max\!(X,Y)\le x)=1-(1-f^{-1}(x))(1-g^{-1}(x))$
. As
$1-f^{-1}(x)$
and
$1-g^{-1}(x)$
are positive, decreasing, and convex, the quantile function of
$1/\max\!(X,Y)$
is convex. Thus
$U\le_\mathrm{c}1/\max\!(X,Y)$
. -
(iv) Let Y have density g. We have
$x^2g(x)=x^2f(x)(g(x)/f(x))$
. As
$x^2f(x)$
and
$g(x)/f(x)$
are both increasing in x and are positive,
$x^2g(x)$
is increasing in x. By Proposition 2, we have the desired result.

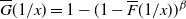


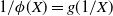
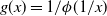


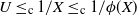

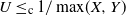


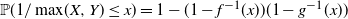


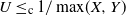
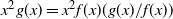


Thus, we complete the proof of this proposition.
Proposition 4(ii) implies that some increasing and convex transforms on random variables preserve property
 $\mathcal{H}$
. For instance, the conditions of Proposition 4(ii) can be satisfied by the commonly used convex functions
 $\phi(x)=x^p$
with
 $p\ge 1$
and
 $\phi(x)={\mathrm{e}}^x-1$
for
 $x>0$
. Intuitively, such convex transforms make random variables more ‘heavy-tailed’. Direct calculations give the following result.
Proposition 5. The following statements hold.
-
(i) For
$w_1,\dots,w_n\in \mathbb{R}_+$
such that
$\sum_{i=1}^n w_i=1$
, if distribution functions
$F_1,\dots,F_n\in\mathcal{H}$
, then
$\sum_{i=1}^n w_iF_i\in\mathcal{H}$
. -
(ii) If
$X\in \mathcal{H}$
, then
$\max\!(X-c,0)\in\mathcal{H}$
, where
$c\in \mathbb{R}_{++}$
.
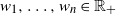

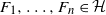
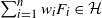

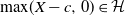

Proposition 5(i) says that
 $\mathcal{H}$
is closed under distribution mixture. Proposition 5(ii) is relevant in an insurance context: X is the actual claim amount and c is the deductible, i.e.
 $\max\!(X-c,0)$
is the payout by the insurer.
3. Compound Poisson distributions
In this section, we assume each random variable in (SD) is a compound sum of random losses. More precisely, for each
 $i\in[n]$
, let
 $X_i=\sum_{j=1}^{N_i}Y_{i,j}$
, where
 $\{Y_{i,j}\}_{j\in\mathbb{N}}$
are i.i.d. random losses and
 $N_i$
is the number of losses, which is independent of
 $\{Y_{i,j}\}_{j\in\mathbb{N}}$
. The distribution of
 $X_i$
is referred to as a compound distribution. One classic example of compound distributions is the compound Poisson distribution.
Definition 5. Let random variables
 $Y_1,Y_2,\dots$
be i.i.d. with distribution F, and N follow a Poisson distribution with mean
 $\lambda\in \mathbb{R}_{++}$
, i.e.
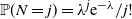 $\mathbb{P}(N=j)=\lambda^j{\mathrm{e}}^{-\lambda}/j!$
,
 $j\in\mathbb{N}_0$
. We say that
 $X=\sum_{i=1}^NY_i$
follows a compound Poisson distribution with Poisson parameter
 $\lambda$
and distribution F, denoted by
 $\mathrm{CP}(\lambda,F)$
.
We first note that if a distribution F satisfies (SD), (SD) may not hold for
 $\mathrm{CP}(\lambda,F)$
. For instance, if F is a degenerate distribution at 1, then
 $\mathrm{CP}(\lambda,F)$
becomes a Poisson distribution, which clearly does not satisfy (SD) by Proposition 1. We now give a sufficient and necessary condition for (SD) to hold for
 $\mathrm{CP}(\lambda,F)$
.
Theorem 3. Let F be a continuous distribution function with
 $\operatorname{ess-inf} F=0$
. Then
 $\mathrm{CP}(\lambda,F)$
satisfies (SD) for all
 $\lambda\in \mathbb{R}_{++}$
if and only if
 $F\in\mathcal{H}$
.
Proof. We first show the ‘
 $\Longleftarrow$
’ direction. Using an argument similar to the proof of Theorem 1, it is sufficient to establish the result for the case of two random variables. Let
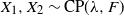 $X_1,X_2\sim \mathrm{CP}(\lambda,F)$
be independent and
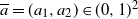 $\overline a=(a_1,a_2)\in(0,1)^2$
be such that
 $a_1+a_2=1$
. It is well known that
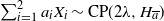 $\sum_{i=1}^2a_iX_i\sim \mathrm{CP}(2\lambda,H_{\overline a})$
, where
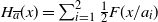 $H_{\overline a}(x)=\sum_{i=1}^2\frac{1}{2}F(x/a_i)$
. We give a proof for this result here for completeness. Let
 $Y\sim F$
. The characteristic function of
 $\sum_{i=1}^2a_iX_i$
is
 \begin{equation*} \varphi_{\sum_{i=1}^2a_i X_i}(t) = \exp\Bigg\{\lambda\Bigg(\sum_{i=1}^2\varphi_{Y}(a_it)-2\Bigg)\Bigg\} = \exp\Bigg\{2\lambda\Bigg(\frac{1}{2}\sum_{i=1}^2\varphi_{Y}(a_it)-1\Bigg)\Bigg\}. \end{equation*}
As
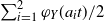 $\sum_{i=1}^2\varphi_{Y}(a_it)/2$
is the characteristic function of
 $H_{\overline a}$
,
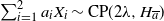 $\sum_{i=1}^2a_iX_i\sim \mathrm{CP}(2\lambda,H_{\overline a})$
.
Let
 $\overline\theta \preceq \overline\eta$
such that
 $\overline\theta,\overline\eta\in(0,1)^2$
and
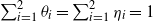 $\sum_{i=1}^2\theta_i = \sum_{i=1}^2\eta_i = 1$
. We need to show that
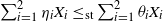 $\sum_{i=1}^2\eta_iX_i\le_\mathrm{st}\sum_{i=1}^2\theta_iX_i$
. Since
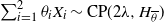 $\sum_{i=1}^2\theta_iX_i \sim \mathrm{CP}(2\lambda,H_{\overline \theta})$
and
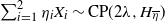 $\sum_{i=1}^2\eta_iX_i \sim \mathrm{CP}(2\lambda,H_{\overline \eta})$
, it suffices to show that
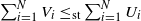 $\sum_{i=1}^NV_i\le_\mathrm{st}\sum_{i=1}^NU_i$
, where
 $N \sim \mathrm{Poi}(2\lambda)$
,
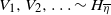 $V_1,V_2,\ldots \sim H_{\overline \eta}$
, and
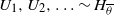 $U_1,U_2,\ldots \sim H_{\overline \theta}$
are mutually independent. As
 $F\in\mathcal{H}$
, by Proposition 2 we have
 $H_{\overline \theta}(x)\le H_{\overline \eta}(x)$
for all
 $x\in \mathbb{R}_+$
, i.e.
 $V_1\le_\mathrm{st}U_1$
. Moreover, as the usual stochastic order is preserved under convolution, for
 $x\in \mathbb{R}_+$
,
 \begin{align*} \mathbb{P}\Bigg(\sum_{i=1}^NV_i\le x\Bigg) & = \sum_{m=0}^\infty \mathbb{P}\Bigg(\sum_{i=1}^mV_i\le x\Bigg)\mathbb{P}(N=m) \\[3pt] & \ge \sum_{m=0}^\infty \mathbb{P}\Bigg(\sum_{i=1}^mU_i\le x\Bigg)\mathbb{P}(N=m) = \mathbb{P}\Bigg(\sum_{i=1}^NU_i\le x\Bigg). \end{align*}
Hence,
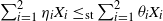 $\sum_{i=1}^2\eta_iX_i\le_\mathrm{st}\sum_{i=1}^2\theta_iX_i$
holds for
 $\overline \theta, \overline \eta\in (0,1)^2$
. Moreover, if
 $\overline \eta=(0,1)$
,
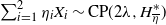 $\sum_{i=1}^2\eta_iX_i\sim \mathrm{CP}(2\lambda,H^*_{\overline \eta})$
, where
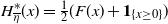 $H^*_{\overline \eta}(x)=\frac{1}{2}(F(x)+\mathbf{1}_{\{x\ge 0\}})$
. Clearly, we have
 $H^*_{\overline \eta}(x)\ge H_{\overline \theta}(x)$
for all
 $x\in\mathbb{R}$
. The ‘
 $\Longleftarrow$
’ direction is done.
Next, we show the ‘
 $\Longrightarrow$
’ direction. We have that if
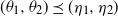 $(\theta_1,\theta_2) \preceq (\eta_1,\eta_2)$
, where
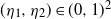 $(\eta_1,\eta_2)\in(0,1)^2$
, then, for all
 $x\in \mathbb{R}$
and for any
 $\lambda\in\mathbb{R}_{++}$
,
 \begin{equation*} \mathbb{P}(\theta_1 X_1 + \theta_2 X_2 > x) \ge \mathbb{P}(\eta_1 X_1 + \eta_2 X_2 > x), \end{equation*}
where
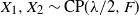 $X_1,X_2\sim \mathrm{CP}(\lambda/2,F)$
are independent. Thus, by the previous arguments, this inequality may be rewritten as
 \begin{equation} 0 \le \lambda{\mathrm{e}}^{-\lambda}[\mathbb{P}(U_1 > x) - \mathbb{P}(V_1 > x)] + \sum_{k=2}^{\infty}\mathbb{P}(N=k)\Bigg[\mathbb{P}\Bigg(\sum_{i=1}^k U_i > x\Bigg) - \mathbb{P}\Bigg(\sum_{i=1}^k V_i > x\Bigg)\Bigg], \end{equation}
where
 $N\sim \mathrm{Poi}(\lambda)$
,
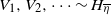 $V_1,V_2,\dots\sim H_{\overline \eta}$
, and
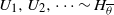 $U_1,U_2,\dots\sim H_{\overline \theta}$
are mutually independent. Assume now that F is not in
 $\mathcal{H}$
, i.e., by Proposition 2, there exist vectors
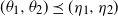 $(\theta_1,\theta_2) \preceq (\eta_1,\eta_2)$
and a value x such that
 \begin{align*} \bigg[\overline{F}\bigg(\frac{x}{\theta_1}\bigg) + \overline{F}\bigg(\frac{x}{\theta_2}\bigg)\bigg] - \bigg[\overline{F}\bigg(\frac{x}{\eta_1}\bigg) + \overline{F}\bigg(\frac{x}{\eta_2}\bigg)\bigg] = -\varepsilon, \end{align*}
where
 $\varepsilon \in \mathbb{R}_{++}$
. Let us now turn our attention back to (8). The second term on the right-hand side may be bounded by
 \begin{align*} \Bigg|\sum_{k=2}^\infty\mathbb{P}(N=k)\Bigg[\mathbb{P}\Bigg(\sum_{i=1}^k U_i > x\Bigg) - \mathbb{P}\Bigg(\sum_{i=1}^k V_i > x\Bigg)\Bigg]\Bigg| \le \mathbb{P}(N\ge 2) \le \lambda^2, \end{align*}
while the first term is
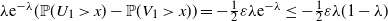 $\lambda{\mathrm{e}}^{-\lambda}(\mathbb{P}(U_1 > x) - \mathbb{P}(V_1 > x)) = -\frac{1}{2}\varepsilon\lambda{\mathrm{e}}^{-\lambda} \le -\frac{1}{2}\varepsilon\lambda(1-\lambda)$
. We have from (8) that, for all
 $\lambda\in \mathbb{R}_{++}$
,
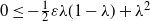 $0 \le -\frac12\varepsilon \lambda(1-\lambda) + \lambda^2$
, which is clearly false for sufficiently small values of
 $\lambda$
. Therefore, we have a contradiction and the proof is complete.
Remark 5. By Theorem 3, if
 $F\in \mathcal{H}$
, CP
 $(\lambda, F)$
satisfies (SD) for any
 $\lambda\in \mathbb{R}_{++}$
. As the usual stochastic order is preserved under mixtures (see, e.g., [Reference Shaked and Shanthikumar27, Theorem 1.A.3(d)]), if
 $F\in\mathcal{H}$
, (SD) holds for the compound mixed Poisson distribution CP
 $(\Lambda,F)$
, where
 $\Lambda$
is a random variable.
In the following, we give a sufficient and necessary condition for (SD*) to hold for
 $\mathrm{CP}(\lambda,F)$
. As this result can be shown by a slight modification to the proof of Theorem 3, its proof is omitted.
Theorem 4. Let F be a continuous distribution function with
 $\operatorname{ess-inf} F=0$
. Then
 $\mathrm{CP}(\lambda,F)$
satisfies (SD*) for all
 $\lambda\in \mathbb{R}_{++}$
if and only if
 $F\in\mathcal{H}^*$
.
4. Stable distributions
In this section, we present a discussion of (SD) for stable random variables to complement the findings of [Reference Ibragimov12], which focused on the peakedness property of linear combinations of stable random variables. Denote by
 $S_\alpha(\sigma,\beta,\mu)$
the stable distributions with stability parameter
 $\alpha \in (0,2]$
, skewness parameter
 $\beta\in[{-}1,1]$
, scale parameter
 $\sigma\in \mathbb{R}_{++}$
, and shift parameter
 $\mu\in\mathbb{R}$
. We say that
 $S_\alpha(1,\beta,0)$
is a standard stable distribution. The characteristic function of
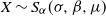 $ X\sim S_\alpha(\sigma,\beta,\mu)$
is given, for
 $x \in \mathbb{R}$
, by
 \begin{align*} \mathbb{E}[\!\exp\{\mathrm{i}x\,X\}] = \begin{cases} \exp\bigg\{\mathrm{i}\mu x - \sigma^\alpha|x|^\alpha\bigg(1 - \mathrm{i}\beta\operatorname{sgn}\!(x)\tan\dfrac{\pi\alpha}{2}\bigg)\bigg\} & \mbox{if $\alpha\ne 1$}, \\[8pt] \exp\bigg\{\mathrm{i}\mu x - \sigma|x|\bigg(1+\mathrm{i}\dfrac{2\beta}{\pi}\operatorname{sgn}\!(x) \log\!|x|\bigg)\bigg\} & \mbox{if $\alpha= 1$}, \end{cases}\end{align*}
where
 $\operatorname{sgn}\!(\! \cdot \!)$
is the sign function. Stable random variables do not have a finite mean if
 ${\alpha\le 1}$
. Stable distributions with
 $\alpha\in(0,1)$
and
 $\beta=\pm1$
are one-sided, and the support is
 $[\mu,\infty)$
for
 $\beta=1$
(resp.
 $({-}\infty,\mu]$
for
 $\beta=-1$
). All other cases of stable distributions have both left and right tails. Stable distributions include normal distributions (
 $\alpha=2$
), Cauchy distributions (
 ${\alpha=1}$
and
 $\beta=0$
), Landau distributions (
 $\alpha=1$
and
 $\beta=1$
), and Lévy distributions (
 $\alpha=\frac12$
and
 $\beta=1$
). See [Reference Nolan25] for further properties of stable distributions.
For non-degenerate i.i.d. random variables
 $X_1,\dots,X_n$
, stable distributions are the limiting distributions of
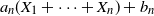 $a_n(X_1+\dots+X_n)+b_n$
for some
 $a_n\in \mathbb{R}_{++}$
and
 $b_n\in\mathbb{R}$
. If
 $\mathbb{E}[X_1^2]<\infty$
, the limiting distribution is the normal distribution, otherwise the limiting distribution is the stable distribution with
 $\alpha<2$
. By Proposition 1, we have the following result.
Proposition 6. If
 $X_1,\dots,X_n$
are i.i.d., satisfy (SD), and
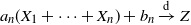 $a_n(X_1+\dots+X_n)+b_n\xrightarrow{\mathrm{d}}Z$
for some stable random variable Z, where
 $a_n\in \mathbb{R}_{++}$
and
 $b_n\in\mathbb{R}$
, then Z satisfies (SD).
Indeed, we can use the nice properties of stable distributions to give the following results of (SD) for stable distributions. We assume that the stable distributions in the following result are standard for simplicity, since the usual stochastic order is preserved under location–scale transforms. Theorem 5(ii) has appeared in [Reference Ibragimov12, Theorem 1.2.4] in a different form; we provide a proof here for completeness.
Theorem 5. The stable distribution
 $S_\alpha(1,\beta,0)$
satisfies (SD) if and only if one of the following conditions holds.
-
(i)
$\alpha=1$
and
$\beta\in \mathbb{R}_+$
; -
(ii)
$\alpha< 1$
and
$\beta=1$
.


Proof. Let
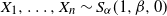 $X_1,\dots,X_n\sim S_\alpha(1,\beta,0)$
be independent and
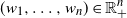 $(w_1,\dots,w_n)\in\mathbb{R}_+^n$
be such that
 $\sum_{i=1}^nw_i=1$
. We first show the ‘
 $\Longleftarrow$
’ direction. If
 $\alpha=1$
, it can be seen from [Reference Nolan25, (1.7)] that
 \begin{equation} \sum^n_{i=1} w_i X_i \simeq_\mathrm{st} X_1-\frac{2\beta}{\pi}\sum_{i=1}^nw_i\log w_i. \end{equation}
As
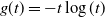 $g(t) =-t\log(t)$
is concave in
 $t\in (0,1)$
,
 $\sum_{i=1}^ng(t_i)$
is Schur-concave in
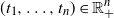 $(t_1,\dots, t_n)\in \mathbb{R}_+^n$
(see [Reference Marshall, Olkin and Arnold21, Proposition 3.C.1]). Hence, we have (i).
Similarly, to show (ii), we have from [Reference Nolan25, (1.7)] that if
 $\alpha\neq 1$
,
 \begin{equation} \sum^n_{i=1} w_i X_i \simeq_\mathrm{st} \left(\sum_{i=1}^nw_i^\alpha\right)^{1/\alpha}X_1. \end{equation}
If
 $\alpha< 1$
and
 $\beta=1$
,
 $X_1$
is positive almost surely and
 $\sum^n_{i=1} c_i^\alpha$
is Schur-concave in
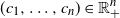 $(c_1, \dots, c_n) \in \mathbb{R}^n_+$
. Thus, we have the desired result.
For the ‘
 $\Longrightarrow$
’ direction, we first note that if
 $S_\alpha(1,\beta,0)$
satisfies (SD), then
 $\alpha\le 1$
; this is due to Proposition 1(i). By (9), if
 $\alpha=1$
, we must have
 $\beta\in \mathbb{R}_+$
. If
 $\alpha<1$
, assume that
 $\beta<1$
. Then, for
 $u\le0$
, by (10) we have
 \begin{equation*} \mathbb{P}\Bigg(\sum^n_{i=1} w_i X_i \le u\Bigg) = \mathbb{P}\bigg(X_1 \le \frac{u}{\big(\sum^n_{i=1} w_i^\alpha\big)^{1/\alpha}}\bigg). \end{equation*}
Thus,
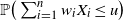 $\mathbb{P}\big(\sum^n_{i=1} w_i X_i \le u\big)$
is Schur-concave in
 $(w_1,\dots,w_n)$
and we have a contradiction. Therefore, if
 $\alpha<1$
,
 $\beta=1$
.
Theorem 5(i) suggests that for a random variable to satisfy (SD), the random variable is not necessarily bounded from below, which is a key assumption of Theorem 1; see also Remark 4.
As the absolute Cauchy distribution satisfies (SD), a natural question is whether absolute stable distributions with parameter
 $\alpha\le 1$
also satisfy (SD). We conjecture that the answer is yes but do not have a proof. We use the stochastic representation of stable random variables in [Reference Weron28] to simulate 10 000 random samples of two independent stable random variables
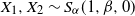 $X_1,X_2\sim S_\alpha(1,\beta,0)$
; see Appendix B for the stochastic representation. Let
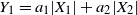 $Y_1= a_1|X_1|+a_2|X_2|$
and
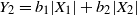 $Y_2= b_1|X_1|+b_2|X_2|$
. We consider three cases of the weight vector
 $(a_1, a_2, b_1, b_2)$
: (1, 4, 2, 3), (2, 6, 3, 5), and (3, 8, 5, 6). Figure 1 plots the empirical distribution functions of
 $Y_1$
and
 $Y_2$
with
 $\alpha=0.10$
and
 $\beta=0$
or
 $-0.40$
, respectively. Figure 2 plots the empirical distribution functions of
 $Y_1$
and
 $Y_2$
with
 $\alpha=0.90$
and
 $\beta=0$
or
 $0.30$
, respectively. From Figures 1 and 2, we find that the empirical distributions
 $\widehat{F}_1$
and
 $\widehat{F}_2$
of
 $Y_1$
and
 $Y_2$
seem to satisfy
 $\widehat{F}_1(x) \ge \widehat{F}_2(x)$
for all x.
Empirical distribution functions of
 $Y_1$
and
 $Y_2$
with
 $\alpha=0.1$
,
 $\beta=0$
(left) and
 $\alpha=0.1$
,
 $\beta=-0.4$
(right).

5. Concluding remarks
We have studied sufficient and necessary conditions for the stochastic dominance relation (SD) across different classes of distributions. While previous studies have established (SD) for a limited set of distributions (stable distributions with tail parameter strictly less than 1 and Pareto distributions with infinite mean), we broadened the scope by proving that (SD) holds for a much richer class of distributions, called the inverted concave distribution. Moreover, if each random variable in (SD) is a compound Poisson sum, then (SD) holds if and only if the summand of the compound Poisson sum is inverted concave. We conclude with some open questions.
Empirical distribution functions of
 $Y_1$
and
 $Y_2$
with
 $\alpha=0.9$
,
 $\beta=0$
(left) and
 $\alpha=0.9$
,
 $\beta=0.3$
(right).

Theorem 1 provides a sufficient condition for (SD) with the assumption that the random variables are bounded from below. How far is this condition from being necessary? Moreover, as (SD) can also hold for random variables taking values on the whole real line, such as the Cauchy distribution, what is the sufficient condition of (SD) without the assumption that the random variables are bounded from below?
Examples 2 and 3 show that the absolute Cauchy and Lévy distributions are inverted concave. A natural question is whether absolute stable random variables with tail parameters less than or equal to 1 and positive stable random variables are also inverted concave. The absence of closed-form expressions for distribution functions in most stable distributions creates a methodological challenge in directly verifying conditions for inverted concave distributions, necessitating alternative analytical techniques.
Another relevant question is whether all absolute stable random variables with tail parameters less than or equal to 1 satisfy property (SD). The answer seems to be yes based on some simulation results.
It was shown in [Reference Chen, Hu, Wang and Zou4] that (SD) holds for infinite-mean Pareto random variables that are positively dependent via some Clayton copula. The last question is whether such a result can be generalized for more general classes of distributions and for more general dependence structures of random variables.
Appendix A. Examples of inverted concave distributions
In this section, we show that many infinite-mean distributions are in
 $\mathcal{H}$
. For a distribution function F, we use f to denote its density and let
 $h(x)=x^2f(x)$
,
 $x\in \mathbb{R}_+$
.
Example 5. (Pareto distribution.) For
 $\alpha\in \mathbb{R}_{++}$
, the Pareto distribution function is
 \begin{align*}F(x)=1-\frac{1}{(x+1)^\alpha}, \quad x\in \mathbb{R}_{++}. \end{align*}
If
 $\alpha\le 1$
, then F has infinite mean. Let
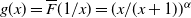 $g(x)=\overline F(1/x)=(x/(x+1))^\alpha$
,
 $x\in \mathbb{R}_+$
. Taking the second-order derivative of g, we have
 \begin{align*}g''(x)=\frac{\alpha (\alpha-2x-1)}{x^{2-\alpha}(x+1)^{2+\alpha}}. \end{align*}
If
 $\alpha\le 1$
, then g
″ is negative. Thus, by Proposition 2, we have
 $F\in \mathcal{H}$
if
 $\alpha\le 1$
.
Example 6. (Log-Pareto distribution.) The log-Pareto distribution [Reference Arnold2, p. 39] has distribution function
 \begin{align*}F(x)=1-\frac{1}{(\!\log\!(x+1)+1)^\alpha}, \quad x\in \mathbb{R}_{++}. \end{align*}
The derivative of h is
 \begin{align*}h'(x)=-\frac{\alpha x}{(x+1)^2 (\!\log\!(x+1)+1)^{\alpha+2}}[\alpha x-(x+2)\log(x+1)-2]. \end{align*}
Let
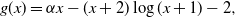 $g(x)=\alpha x-(x+2)\log(x+1)-2,$
 $x\in \mathbb{R}_+$
. By Proposition 2, we need
 $h'(x)\ge 0$
, or equivalently,
 $g(x)\le 0$
, such that
 $F\in\mathcal{H}$
. As
 $g(0)=-2$
, it is sufficient to choose
 $\alpha$
such that g is decreasing. We have
 \begin{align*}g'(x)=\alpha-\frac{x+2}{x+1}-\log\!(x+1). \end{align*}
Thus if
 $\alpha\le 2$
, then
 $F\in\mathcal{H}$
.
Example 7. (Inverse Burr distribution.) The inverse Burr distribution is defined as
 \begin{equation*} F(x)=\bigg(\frac{x^\tau}{x^\tau+1}\bigg)^\alpha, \quad x\in \mathbb{R}_{++}, \end{equation*}
where
 $\alpha,\tau\in \mathbb{R}_{++}$
. For
 $x\in\mathbb{R}_+$
,
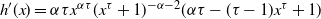 $h'(x)=\alpha\tau x^{\alpha\tau}(x^\tau+1)^{-\alpha-2}(\alpha\tau-(\tau-1)x^\tau+1)$
. Hence, if
 $\tau\le 1$
then
 $h'(x) \geq 0$
. By Proposition 2, we have
 $F\in \mathcal{H}$
.
Example 8. (Stoppa distribution.) For
 $\alpha, \beta\in \mathbb{R}_{++}$
, a (location-shifted) Stoppa distribution can be defined as
 \begin{equation*} F(x)=\bigg(1-\frac{1}{(x+1)^\alpha}\bigg)^\beta, \quad x\in \mathbb{R}_{++}. \end{equation*}
Since a Stoppa distribution is a power transform of a Pareto distribution, by Proposition 4(i), if
 $\alpha\le 1$
and
 $\beta\ge 1$
,
 $F\in\mathcal{H}$
. Power transforms have also been used to generalize Burr distributions [Reference Kleiber and Kotz17, p. 211].
Example 9. (Log-Cauchy distribution.) The log-Cauchy distribution function is
 \begin{align*}F(x)=\frac{1}{\pi}\arctan\!(\!\log\!(x))+\frac{1}{2}, \quad x\in \mathbb{R}_{++}. \end{align*}
We have
 \begin{align*}f(x)=\frac{1}{x^2\pi}\frac{x}{(\!\log\!(x))^2+1}. \end{align*}
As
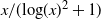 $x/(\!\log\!(x)^2+1)$
is increasing in x,
 $F\in\mathcal{H}$
by Remark 2.
Appendix B. Simulation of stable distributions
We recall here the simulation procedure of standard stable distributions
 $S_\alpha(1,\beta,0)$
in [Reference Weron28].
-
(i) Let two random variables
$V \sim U({-}\pi/2, \pi/2)$
and
$W \sim \mathrm{Exp}(1)$
be independent. -
(ii) For
$\alpha \neq 1$
, let where
\begin{align*} X = M_{\alpha, \beta}\frac{\sin\!(\alpha(V-N_{\alpha, \beta}))}{(\!\cos\!(V))^{1/\alpha}} \bigg(\frac{1}{W}\cos\!(V-\alpha(V-N_{\alpha,\beta}))\bigg)^{(1-\alpha)/\alpha}, \end{align*}
\begin{align*} M_{\alpha, \beta} = \bigg[1 + \beta^2\tan^2\bigg(\frac{\pi\alpha}{2}\bigg)\bigg]^{1/(2\alpha)}, \qquad N_{\alpha, \beta} = -\frac{1}{\alpha}\arctan\bigg(\beta\tan\frac{\pi\alpha}{2}\bigg). \end{align*}
-
(iii) For
$\alpha = 1$
, following the correction in [Reference Weron29], let
\begin{align*} X = \frac{2}{\pi}\bigg[\bigg(\frac{\pi}{2}+\beta V\bigg)\tan(V) - \beta\log\bigg(\frac{(\pi/2)W\cos\!(V)}{\pi/2+\beta V}\bigg)\bigg]. \end{align*}
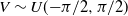


As
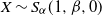 $X \sim S_\alpha(1, \beta, 0)$
, we can generate samples of X by first generating samples of V and W and then plugging the samples into the above stochastic representations of X.
Acknowledgements
The authors would like to thank an associate editor and two anonymous referees for their helpful comments on an earlier version of this paper.
Funding information
Y. Chen is supported by the 2025 Early Career Researcher Grant from the University of Melbourne. T. Hu would like to acknowledge financial support from the National Natural Science Foundation of China (Nos. 72332007, 12371476). Z. Zou is supported by the National Natural Science Foundation of China (No. 12401625), the China Postdoctoral Science Foundation (No. 2024M753074), and the Postdoctoral Fellowship Program of CPSF (GZC20232556).
Competing interests
There were no competing interests to declare which arose during the preparation or publication process of this article.

 Y1
 Y2
 α=0.1
 β=0
 α=0.1
 β=−0.4

 Y1
 Y2
 α=0.9
 β=0
 α=0.9
 β=0.3

 Open access

