1. INTRODUCTION
In economics and finance many stochastic processes can be seen as integrated stochastic processes in the sense that the current observation behaves as the cumulation of all past perturbations. In a discrete-time framework the concept of integration and differentiation of a stochastic process plays an essential role in modern econometric analysis. For instance, the stochastic process {yt; t = 0,1,2,…} where yt = α + yt−1 + εt (εt ∼ i.i.d. N(0,1)) is an example of an integrated process. Notice that y can be written as

, or

where xt = α + εt. One way to deal with such processes is to use a differenced-data model (e.g., Δyt = α + εt, in the previous example). Differencing has been used mostly to solve nonstationary problems viewed as unit roots, although historically differenced-data models arose early in econometrics as a procedure to remove common trends between dependent and independent variables.
Integrated and differentiated diffusion processes in the same sense as integrated and differentiated discrete-time processes are almost absent in applied econometric analysis. One of the reasons continuous-time differentiated processes have not been considered in applied econometrics is perhaps related to the difficulties in interpreting the “differentiated” process. In fact, if Z is a diffusion process driven by a Brownian motion, then all sample functions are of unbounded variation and nowhere differentiable; i.e., dZt /dt does not exist with probability one (unless some smoothing effect of the measurement instrument is introduced, such as described in Arnold, 1974).
One way to model integrated and differentiated diffusion processes and overcome the difficulties associated with the nondifferentiability of the Brownian motion is through the representation

where a and b are the infinitesimal coefficients (respectively, the drift and the diffusion coefficient), W is a (standard) Wiener process (or Brownian motion), and X is (by hypothesis) a stationary process. In this model, Y is a differentiable process, by construction. It represents the integrated process

(note the analogy with the corresponding expression in a discrete-time setting,

, eqn. (1)), and Xt = dYt /dt is the stationary differentiated process (which can be considered the equivalent concept to the first differences sequence in discrete-time analysis). If X represents the continuously compounded return or log return of an asset, the first equation in system (2) should be rewritten as d log Yt = Xt dt.
We think that (2) can be a useful model in empirical finance for at least two reasons. First, the model accommodates nonstationary integrated stochastic processes (Y) that can be made stationary by differencing. Such transformation cannot be undertaken in common univariate diffusion processes used in finance (because all sample paths from univariate diffusion processes are nowhere differentiable with probability one). Yet, many processes in economics and finance (e.g., stock prices and nominal exchange rates) behave as the cumulation of all past perturbations (basically in the same sense as unit root processes in a discrete framework). Second, in the context of stock prices or exchange rates, the model suggests directly modeling the (instantaneous) returns, in contrast to the usual continuous-time models in finance, which directly model the prices. General properties for returns (stylized facts) are well known and documented (e.g., returns are generally stationary in mean, the distribution is not normal, the autocorrelations are weak, and the correlations between the magnitude of returns are positive and statistically significant, etc.). One advantage of directly modeling the returns (X) is that these general properties are easier to specify in a model like (2) than in a diffusion univariate process for the prices. In fact, several interesting models can be obtained by selecting a(x) and b2(x) appropriately. For example, the choice a(x) = β(τ − x) and

leads to an integrated process Y whose returns, X, have an asymmetric leptokurtic stationary distribution (see the example that follows). This specification can be appropriated in financial time series data. Bibby and Sørensen (1997) have already noticed that a process similar to (2) could be a good model for stock prices.
We observe that the model defined in equation (2) can be written as a second-order stochastic differential equation, d(dYt /dt) = a(Xt) dt + b(Xt) dWt. Integrated diffusions like Y in equation (3) arise naturally when only observations of a running integral of the process are available. For instance, this can occur when a realization of the process is observed after passage through an electronic filter. Another example is provided by ice-core data on oxygen isotopes used to investigate paleotemperatures (see Ditlevsen and Sørensen, 2004).
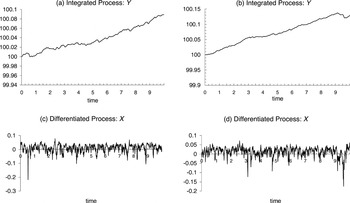
To illustrate continuous-time integrated processes, Figure 1 presents two simulated independent paths of

where X is governed by the stochastic differential equation

(X is also represented in Figure 1). All paths are composed of 1,000 observations defined in the interval t ∈ [0,10]. In Section 4 we give more details on how we generate these observations. It is interesting to observe that Y displays all the features of an integrated process (with a positive drift because E[Xt] = 0.01): There is an absence of mean reversion; shocks are persistent; mean and variance depend on time, etc. On the other hand, the unconditional distribution of X (return) is asymmetric and leptokurtic.

Simulation of two independent paths of the process where X is governed by the stochastic differential equation .
Estimation of second-order stochastic differential equations raises new challenges for two main reasons. On the one hand, only the integrated process Y is observable at instants {ti; i = 1,2,…}, and thus X in model (2) is a latent nonobservable process. In fact, for a fixed sampling interval, it is impossible to obtain the value of X at time ti from the observation Yti that represents the integral

. On the other hand, the estimation of model (2) cannot in principle be based on the observations {Yti; i = 1,2,…} because the conditional distribution of Y is generally unknown, even if that of X is known. An exception is the case where X follows an Ornstein–Uhlenbeck process, which is analyzed in Gloter (2001).
However, with discrete-time observations {YiΔ; i = 1,2,…} (to simplify we use the notation ti = iΔ, where Δ = ti − ti−1), and given that

we can obtain a measure of X at instant ti = iΔ using the formula

Naturally, the accuracy of (4) as a proxy for XiΔ depends on the magnitude of Δ. Regardless of the magnitude of Δ we have in our sample, we should base our estimation procedures on the sample

because X is not observable.
Parametric and semiparametric estimation of integrated diffusions are analyzed in Gloter (2001, 2006) and Ditlevsen and Sørensen (2004).
We suppose that both infinitesimal coefficients a and b, defined in model (2) are unknown, and our aim is their nonparametric functional estimation. We propose nonparametric estimators for the infinitesimal coefficients a and b. Our analysis reveals that the standard estimators based on the sample

are inconsistent, even if we allow the step of discretization Δ to go to zero asymptotically. Introducing slight modifications to these estimators we provide consistent estimators. For a review of nonparametric estimation of (first-order) stochastic differential equations see, e.g., Rao (1983), Florens-Zmirou (1993), Jiang and Knight (1997), Bandi and Phillips (2003), Nicolau (2003), and Gobet, Hoffmann, and Reiß (2004). For a review of parametric and semiparametric estimation see, e.g., Aït-Sahalia (2002) and Kessler (1997) and the references therein.
The rest of the paper is organized as follows. In Section 2 we formulate the main hypotheses concerning the X process, and we identify our estimators. In Section 3 we establish the main results. We show that under appropriate conditions, the proposed estimators are consistent and asymptotically normal. In Section 4 we perform a Monte Carlo experiment in which we assess the response of the nonparametric estimator with respect to the step of discretization Δ. Section 5 concludes. Appendix A presents some auxiliary results. All proofs appear in Appendix B.
2. ESTIMATORS AND ASSUMPTIONS
The aim of this paper is to study the following estimators:

for, respectively, p(x), a(x), and b2(x), based on the observations

, where


Consider the process (Y,X) governed by the system (2). Let

be the scale density function (z0 is an arbitrary point inside I) and m(u) = (b2(u)s(u))−1 the speed density function. Let

and

where l < x1 < x < x2 < r. We now present a set of eight assumptions that are used throughout the paper.
A1. S(l,x] = S[x,r) = ∞ for x ∈ I.
A2.

m(x) dx < ∞.
The A1 and A2 conditions assure that X is ergodic and the invariant distribution P0 has desity

with respect to the Lebesgue measure (Skorokhod, 1989, Thm. 16). The expression p(x) is usually referred to as the stationary density.
A3. X0 = x has distribution P0.
Assumption A3 together with A1 and A2 implies that X is stationary (Arnold, 1974). The hypothesis that X is a stationary process is obviously a plausible assumption because for major integrated time series data a simple differentiation generally assures stationarity.
A4. limx→r sup((a(x)/b(x)) − (b′(x)/2)) < 0, limx→l sup((a(x)/b(x)) − (b′(x)/2)) > 0.
These conditions are discussed in Chen, Hansen, and Carrasco (1999) and are similar to conditions proposed by Hansen and Scheinkman (1995). Under Assumption A4 the process is ρ-mixing and α-mixing (see Chen et al., 1999). Technically, for a Markov process, the notion of ρ-mixing requires the conditional expectations operator for any interval of time to be a strong contraction on the linear space L20 = {f : ∫f (x)p(x) dx = 0,∫f2(x)p(x) dx < ∞}. As a consequence, the jth autocovariance of f (Xt) tends to zero at an exponential rate as j → ∞, for all f ∈ L20 (see Hansen and Scheinkman, 1995, Prop. 8; Florens-Zmirou, 1989).
We notice that the discretized diffusion {XiΔ} := {XiΔ; i = 0,1,2,…} with fixed Δ is an ergodic process because X = {Xt; t ≥ 0} is ergodic under Assumptions A1–A4 (see Dacunha-Castelle and Florens-Zmirou, 1986). The process

inherits some properties from {XiΔ}. As Ditlevsen and Sørensen (2004) point out, because X is stationary, the distribution of Xt is the same for all intervals {[(i − 1)Δ,iΔ]; i ≥ 1}, and thus

is a stationary process. Also if E [X] < ∞, we have by Chebyshev integral inequality and stationarity

On the other hand,

is α-mixing (ρ-mixing) because measurable functions of mixing processes are mixing and of the same size.
The kernel function K satisfies the following assumption.
A5. K(.) is positive, symmetric, and continuously differentiable, and

,

,

.
A6(α). limh→0 E[(1/h)|K′(ξn,i)|α] < ∞ where α = 2 or α = 4 and

, 0 ≤ θ ≤ 1.
Assumption A6(α) is generally satisfied under very weak conditions. For instance, with a Gaussian kernel and a Cauchy stationary density (which has heavy tails) we still have limh→0 E[(1/h)|K′(X/h)|4] < ∞. Notice that the expectation with respect to the distribution of ξn,i depends on the stationary densities of X and

because ξn,i is a convex linear combination of X and

.
A7.
(i) The infinitesimal coefficients a and b have continuous derivatives of order 4 and satisfy |a(x)| ≤ C(1 + |x|)λ and |b(x)| ≤ C(1 + |x|)λ for some λ > 0.
(ii) E [X0r] < ∞ where r = max{4λ,1 + 3λ,−1 + 5λ,−2 + 6λ}.
This assumption is related to the application of Lemma 4 (Appendix A). See the general discussion in Remark 1.
A8.

Assumptions A1–A5 and A8 assure consistency and asymptotic normality of the standard estimators for p(x), a(x), b2(x), based on the observations {XiΔn}, respectively,

where

In fact, it can be proved (see, e.g., Bandi and Phillips, 2003) that

3. MAIN RESULTS
We assume conditions A1–A7 in all theorems.
THEOREM 1. Assume A6(α = 2) and A8(a). Then

It is well known that the standard

estimator (i.e., built from the observations {XiΔ}) does not require that the step of discretization Δ goes to zero as n → ∞ (if Δ is fixed it is necessary that nΔ → ∞). However, as one would expect, the convergence of the density estimator based on the observations

requires Δn → 0.
THEOREM 2.
(i) Assume A6(α = 2) and A8(a) and (b1). Then

(ii) If additionally A8(b2) and hn nΔn3 → 0 then

Standard conditions for consistency of

still assure

. It is implicit in the conditions of the theorem that nΔn → ∞, and this condition should also hold in the standard case.
The “natural” estimator for a(x), based on the observations

, is

It can be proved, however, that this estimator is inconsistent. When Δ is fixed the advantages of the

over the

are not clear. To shed light on this issue, we perform some Monte Carlo experiments in Section 4. One of the main conclusions is that the

estimator may present a smaller mean squared error than the

estimator when the step of discretization is not small enough. On the contrary, when Δn → 0 the mean squared error of the

estimator converges to the mean squared error of the drift estimator based on the observations {XiΔ}.
THEOREM 3.
(i) Assume A6(α = 4) and A8(a) and (c1). Then

(ii) If additionally A8(c2) and hn nΔn2 → 0 then

The most important difference between this theorem and the standard counterpart result is that our estimator

involves a multiplicative factor of

. Gloter (2006), using different arguments and working in a semiparametric framework, has already foreseen the need for this correction. For more details see the proof of Theorem 3. Therefore, the “natural” estimator for b2(x), based on the observations

,

has an asymptotic bias of −b2(x)/3 (when Δn → 0). This bias is confirmed through Monte Carlo simulations (Section 4).
4. MONTE CARLO SIMULATION
In this section we perform a Monte Carlo experiment aimed at assessing the response of the nonparametric estimators with respect to the step of discretization Δ. Our Monte Carlo experiment is based on the simulation of

for t ∈ [0,T] = [0,1,000] where X is an ergodic process governed by the stochastic differential equation

. To simulate Y and X we consider a time discretization 0 < δ < 2δ < ··· < nδ = T of the interval [0,T] and the Euler–Maruyama approximation. We found that the value δ = 0.001 is reliable in the sense that the approximations

and

are sufficiently close to the respective sample path of the Itô process. As such, we simplify the notation, and we write

and

. We generate 5,000 replicas of X and Y. We have thus in each replica a sequence of n = 1,000,000 values of X and Y (note that T/δ = 1,000/0.001 = 1,000,000) from which we estimate the infinitesimal coefficients assuming different values for the step of discretization. Specifically, we consider the following samples: {Yi×0.01; i = 0,1,…,100,000}, {Yi×0.02; i = 0,1,…,50,000},…,{Yi×0.2; i = 0,1,…,5,000}; i.e., step of discretization ranges from Δ = 0.01 to Δ = 0.2 with a step of 0.01. In each sample (and for each replica) we estimate the infinitesimal coefficients a(x) = −10x and b2(x) = 0.1 + 0.1x2. The values of x are from the set A = {q0.20,q0.30,…,q0.70, q0.80} where qα is the quantile of order α of the stationary distribution of X, i.e., p(x) = 1.80656(1 + x2)−11.
A measure of error is based on the Monte Carlo average of the “integrated” squared error (ISE) obtained in each replica. We denote this statistic as AISE. For example, the AISE of

, based on a certain value for Δ, is given by

where

is the “integrated” squared error over the set A of the estimator

, obtained in the jth replica, i.e.,

(#A: number of elements of the set A; in our case, #A = 7). Although the

is only a rough approximation to the standard ISE measure,

, it can provide valuable information on the error of approximation of the nonparametric estimator.
We study the drift estimators

and

(see (5) and (9), respectively) and the diffusion estimators

and

(see (5) and (10), respectively). For comparison purposes we also analyze the drift and the diffusion estimators based on the observations {XiΔ},

and

(see eqn. (8)). In all cases we consider a Gaussian kernel and the common bandwidth

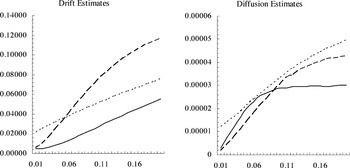
, with h = 1.06. The results are shown in Figure 2. The main conclusions are as follows. First, as expected, the estimators based on the observations {XiΔ},

and

, generally present smaller AISE when the step of discretization is moderate or high. These differences are, however, negligible when Δ is small. Second, as expected, the AISEs of the estimators

and

(dashed line) converge to zero as Δ → 0. Third, the

estimator (dotted line) seems inconsistent because the AISE does not converge to zero as Δ shrinks. However, for moderate/high values of Δ, the

estimator performs reasonably well, and better than the

estimator. Consequently, in practical applications the

estimator should be used with some caution, especially when the step of discretization is not small. In these cases, the

estimator may be better. Fourth, the

estimator, as predicted in Section 3, has the worst performance when compared with the other estimators. Finally, the AISEs associated with the diffusion estimators are much smaller for all values of Δ > 0. This may be related to the data generating process selected and/or to the fact that the estimation of a is harder than that of b. This is a point emphasized, e.g., by Gobet et al. (2004) and Bandi and Phillips (2003).

Drift and diffusion estimators: Monte Carlo average of ISE. Solid line: and ; dashed line: and ; dotted line: and .
5. CONCLUSIONS AND OTHER EXTENSIONS
In this paper we showed that standard nonparametric estimators of the infinitesimal coefficients of second-order stochastic differential equations, based on the observations

, are not appropriate, because they are inconsistent, even when Δn → 0. However, as shown, slight modifications to the standard estimators allow us to define consistent estimators.
There are some extensions that can be considered, such as nonequidistant observations, optimal bandwidth choice, data-driven estimation, and minimax rates. More general assumptions on the data generating process as in Bandi and Phillips (2003) can also be applied.
APPENDIX A: Auxiliary Results
In the following lemma we generalize a formula of Florens-Zmirou (1989) to multivariate diffusions. Lemma 4 is essential in the proofs of all the theorems presented in this paper.
LEMMA 4. Z be a d-dimensional diffusion process governed by the stochastic integral equation

where a(z) = [ai(z)]d×1 is a d × 1 vector, [bij(z)]d×d is a d × d diagonal matrix, and Wt is a d × 1 vector of independent Brownian motions. One assumes that a and b have continuous partial derivatives of order 2s. Let f (z) denote a continuous function defined on Rd with values in Rd and with continuous partial derivatives of order 2s + 2. Then

where L is a second-order differential operator defined as

and R is a stochastic function of order Δs+1 (see Remark 1 in Appendix B for details on the R function).
A particularly important case is d = 2 with

In this case, the second-order differential operator is L = x(∂/∂y) + a(x)(∂/∂x) + ½b2(x)(∂2/∂x2). Lemma 4 allows us to calculate a variety of mathematical expectations involving the

process. For example, using Lemma 4 one can conclude that

and

.
LEMMA 5. Consider

Assume

, A1–A3, and A5.
(i) If A6(α = 4) and

or
(ii) if A6(α = 2) and

then

.
This result simplifies the proofs of Theorems 1–3. With this lemma, we can obtain the limit in probability of ε1,n by calculating the limit in probability of ε2,n (which is easier to obtain).
APPENDIX B: Proofs
Proof of Lemma 4. By Itô's formula we have

Applying Itô's formula several times to Lf (Zu1) we can conclude, given the properties of the Wiener process, that

where

. █
Remark 1. Consider the jth row of the vector R:

Given stationarity, it is obvious that E[Ls+1fj(Z0)] < ∞ implies E[Rj] < ∞. Assumption A7 guarantees that the expression E[Ls+1fj(Z0)] is finite in all applications of Lemma 4 in this paper. For example, in the proof of Lemma 5 we consider

and E[R] is of order Δn3. Using Assumption A7, simple but tedious calculations enable us to find that

is bounded by a polynomial degree of order r = max{4λ,1 + 3λ,−1 + 5λ,−2 + 6λ}, where λ is such that |a(x)| ≤ C(1 + |x|)λ and |b(x)| ≤ C(1 + |x|)λ. Thus, E[X0r] < ∞ guarantees that the expansion (B.1) is well defined. In this paper all expressions involving the application of Lemma 4 (in these cases s is equal to or lower than 2) are bounded by a polynomial degree of order r. Therefore, Assumption A7 assures that Lemma 4 is used properly throughout the paper.
Proof of Lemma 5. By Taylor's formula

where

, stationarity, and Hölder's inequality, we have

where 1/α + 1/β + 1/γ = 1. Selecting α = 4, β = 4, and γ = 2 we have by hypothesis

and by Lemma 4

Thus E[|ε1,n − ε2,n|] → 0. Part (ii) is immediate from Cauchy–Schwarz inequality (in this case it is sufficient to consider limh→0 E[(1/h)|K′(ξn,i)|2] < ∞). █
Proof of Theorem 1. Let

It is well known that under the conditions of the theorem one has

(see, e.g., Bandi and Phillips, 2003). It remains to show that

. This follows immediately from Lemma 5(ii) with g ≡ 1. Therefore, the right-hand side of the inequality

goes to zero (under the conditions of the theorem). Thus, we have

and, by Chebyshev's inequality,

. █
Proof of Theorem 2. (i) From the proof of Theorem 1 we know that

. Thus, to prove

it is sufficient to verify that

. Let us consider

Under the conditions of the theorem it is known that

(see Bandi and Phillips, 2003). The idea is to prove that

, which implies that

and consequently

. By Lemma 5(ii) An(x) − An0(x) has the same limit in probability as

We now show that

. By Lemma 4, A7, and stationarity, we have

On the other hand,

We have

where γn represents the sum of

terms involving the autocovariances. Under stationarity and Assumption A4 (X and

are ρ-mixing and α-mixing), the jth autocovariance of gi tends to zero at exponential rate as j → ∞, for all functions g such that E[gi2] < ∞. Therefore, if E[gi2] < ∞, the series γ∞ is absolutely convergent, and one has

. Because ∫K2(u) du < ∞ and X has stationary density, one can conclude that

is finite because, by Lemma 4,

In conclusion,

as nΔn hn → ∞.
(ii) By hypothesis (see Bandi and Phillips, 2003)

where

. By the asymptotic equivalence theorem, it suffices to prove that

where

. From part (i) we know that

and

. Thus, under the assumption hn nΔn3 → 0, the result holds. █
Proof of Theorem 3. (i) From the proof of Theorem 1 we know that

. Thus, to prove

it is sufficient to verify that

. Let us consider

Under the conditions of the theorem it is known that

(see Bandi and Phillips, 2003). The idea is to prove that

, which implies that

and consequently

. By Lemma 5(i) Bn(x) − Bn0(x) has the same limit in probability as

We now prove that

. Let us consider

where

. Because by Lemma 4

one has

On the other hand,

Using the same arguments as in the proof of Theorem 2(i), it is easy to conclude that the condition

assures Var[δ2,n(x)] → 0.
(ii) By hypothesis (see Bandi and Phillips, 2003)

where

. By the asymptotic equivalence theorem it is sufficient to prove that

where

. From part (i) we know that

and δ3,n(x) = Op(Δn). Thus, under the assumption hn nΔn2 → 0 the result holds. █