




No CrossRef data available.
SEMIPARAMETRIC ESTIMATION OF A HETEROSKEDASTIC SAMPLE SELECTION MODEL
Published online by Cambridge University Press: 24 September 2003
Abstract
This paper considers estimation of a sample selection model subject to conditional heteroskedasticity in both the selection and outcome equations. The form of heteroskedasticity allowed for in each equation is multiplicative, and each of the two scale functions is left unspecified. A three-step estimator for the parameters of interest in the outcome equation is proposed. The first two stages involve nonparametric estimation of the “propensity score” and the conditional interquartile range of the outcome equation, respectively. The third stage reweights the data so that the conditional expectation of the reweighted dependent variable is of a partially linear form, and the parameters of interest are estimated by an approach analogous to that adopted in Ahn and Powell (1993, Journal of Econometrics 58, 3–29). Under standard regularity conditions the proposed estimator is shown to be  -consistent and asymptotically normal, and the form of its limiting covariance matrix is derived.We are grateful to B. Honoré, R. Klein, E. Kyriazidou, L.-F. Lee, J. Powell, two anonymous referees, and the co-editor D. Andrews and also to seminar participants at Princeton, Queens, UCLA, and the University of Toronto for helpful comments. Chen's research was supported by RGC grant HKUST 6070/01H from the Research Grants Council of Hong Kong.
Information
- Type
- Research Article
- Information
- Copyright
- © 2003 Cambridge University Press
1. INTRODUCTION AND MOTIVATION
Estimation of economic models is often confronted with the problem of sample selectivity, which is well known to lead to specification bias if not properly accounted for. Sample selectivity arises from nonrandomly drawn samples, which can be due to either self-selection by the economic agents under investigation or to the selection rules established by the econometrician. In labor economics, the most studied example of sample selectivity is the estimation of the labor supply curve, where hours worked are only observed for agents who decide to participate in the labor force. Examples include the seminal works of Gronau (1974) and Heckman (1976, 1979). It is well known that the failure to account for the presence of sample selection in the data may lead to inconsistent estimation of the parameters aimed at capturing the behavioral relation between the variables of interest.
Econometricians typically account for the presence of sample selectivity by estimating a bivariate equation model known as the sample selection model (or, using the terminology of Amemiya, 1985, the type 2 Tobit model). The first equation, typically referred to as the “selection” equation, relates the binary selection rule to a set of regressors. The second equation, referred to as the “outcome” equation, relates a continuous dependent variable, which is only observed when the selection variable is 1, to a set of possibly different regressors.
Parametric approaches to estimating this model require the specification of the joint distribution of the bivariate disturbance term. The resulting model is then estimated by maximum likelihood or parametric “two-step” methods. This approach yields inconsistent estimators if the distribution of the disturbance vector is parametrically misspecified and/or conditional heteroskedasticity is present. This negative result has motivated estimation procedures that are robust to either distributional misspecification or the presence of conditional heteroskedasticity. Powell (1989), Choi (1990), and Ahn and Powell (1993) propose two-step estimators that impose no distributional assumptions on the disturbance vector, but none of these are robust to the presence of conditional heteroskedasticity in the outcome equation. Alternatively, Donald (1995) proposes a two-step estimator that allows for general forms of conditional heteroskedasticity but requires the disturbance vector to have a bivariate normal distribution. Chen (1999) recently relaxed the normality assumption but still requires joint symmetry of the error distribution.1
Kyriazidou (1997) considers estimation of a sample selection model for longitudinal data. Her approach allows for cross-sectional heteroskedasticity and also for individual specific effects. The purpose of our paper is to estimate the parameters of interest when only a cross-sectional data set is available to the econometrician.
Given the observed characteristics of some types of microeconomic data, such as differing variability across agents with differing characteristics, and also empirical distributions exhibiting asymmetry and/or tails thicker than would be consistent with a Gaussian distribution,2
For example, in his empirical analysis of female labor supply, Mroz (1987) finds the disturbance term in the labor force participation equation to have skewness and kurtotis levels that are inconsistent with the normality assumption.
The idea of modeling conditional heteroskedasticity through a multiplicative structure is quite common in the econometrics and statistics literature, in both applied and theoretical work. See Chen and Khan (2000, 2003) and references therein for a list of examples.
In this paper we show that

-consistent estimation of the parameters in the outcome equation is still possible with the presence of nonparametric multiplicative heteroskedasticity. Our estimation approach involves three stages. The first stage concentrates on the selection equation, estimating the “propensity scores” introduced in Rosenbaum and Rubin (1983). In the second stage, nonparametric quantile regression methods are used to estimate the conditional interquartile range of the outcome equation dependent variable for the selected observations. It will be shown that the conditional interquartile range is a product of the outcome equation scale function and an unknown function of the propensity score. This fact implies that when the dependent variable and regressors are reweighted by dividing by the conditional interquartile range, the conditional expectation of the reweighted outcome equation is of the partially linear form that arises in homoskedastic sample selection models. Since the nonparametric component of the partially linear model is a function of the propensity score, the first-stage estimated values can be used in combination with the reweighted values to estimate the parameters of interest in a fashion analogous to the approaches used in Ahn and Powell (1993), Donald (1995), and Kyriazidou (1997).
The rest of the paper is organized as follows. The next section describes the model in detail and further details the estimation procedure. Sections 3 and 4 detail the regularity conditions imposed and establish the asymptotic properties of the estimator, respectively. Section 5 concludes and suggests topics for future research. The Appendix collects the proofs of the asymptotic arguments.
2. HETEROSKEDASTIC MODEL AND ESTIMATION PROCEDURE
We consider estimation of the following model:


where

are the unknown parameters of interest, xi,wi are observed vectors of explanatory variables (with possibly common elements), μ(wi), σ1(wi),σ2(xi) are unknown functions of the explanatory variables, and νi,εi are unobserved disturbances, which are independent of the regressors but not necessarily independent of each other. The observed dependent variable di in the selection equation is binary, with I [·] denoting the usual indicator function, and the dependent variable of the outcome equation, yi*, is only observed when the di = 1.
Of interest is to estimate β0 from n observations of a random sample of the quadruple (di,yi,wi′,xi′)′, where ′ denotes the transpose of a vector. We show in this paper that

-consistent estimation of β0 is possible, and we propose a three-step estimator that achieves this rate of convergence. The following three sections discuss each of the stages in detail.
2.1. First Stage: Kernel Estimation of the Propensity Score
The first stage estimates the probability of selection conditional on the selection equation regressors. Following frequently used terminology, we refer to these conditional probabilities as “propensity scores.” We denote the propensity score as

where Fν(·) denotes the cumulative distribution function (c.d.f.) of the random variable νi and is assumed to be strictly monotonic. Noting that the propensity score is merely a conditional expectation, it can be estimated using nonparametric methods for estimating the conditional mean. Denoting the estimated value by

, we consider the Nadaraya–Watson kernel estimator:

where K(·) is a kernel function and h1n is a “bandwidth” converging to 0 as the sample size increases to infinity. Additional conditions imposed on K(·) and h1n are discussed in the section detailing regularity conditions.
2.2. Second Stage: Nonparametric Estimation of the Conditional Interquartile Range
In the second stage, we turn attention to the outcome equation. Specifically, we estimate two conditional quantile functions. Let zi denote the vector of distinct elements of the vector (wi′,xi′)′. For a fixed number α ∈ (0,1), we denote the α conditional quantile function as

where Qα(·) denotes the α quantile of the distribution of yi conditional on di = 1 and xi. This quantile function can be estimated using nonparametric methods on the subsample of observations for which di = 1. Although there exist various nonparametric estimation procedures in the literature, we adopt the local polynomial estimator introduced in Chaudhuri (1991a, 1991b), which is also used as a preliminary estimator in Chaudhuri, Doksum, and Samarov (1997), Chen and Khan (2000, 2001), Khan (2001), and Khan and Powell (2001). We first introduce some new notation that will help facilitate a description of the local polynomial procedure.
First, we assume that the regressor vector zi, whose distribution function we denote by FZ(·), can be partitioned as (zi(ds),zi(c)), where the kds-dimensional vector zi(ds) is discretely distributed and the kc-dimensional vector zi(c) is continuously distributed.
We let Cn(zi) denote the cell of observation zi and let h2n denote the sequence of bandwidths that govern the size of the cell. For some observation zj, j ≠ i, we let zj ∈ Cn(zi) denote that zj(ds) = zi(ds) and zj(c) lies in the kc-dimensional cube centered at zi(c) with side length h2n.4
Here we have required an observation's discrete component to match up exactly for it to fall in a given cell. However, it is often the case that the finite-sample performance of nonparametric procedures can be improved by smoothing across discrete components also (see Li and Racine, 2000).
Next, we let [ell ] denote the assumed order of differentiability of the quantile functions with respect to zi(c), and we let A denote the set of all kc-dimensional vectors of nonnegative integers bl, where the sum of the components of each bl, which we denote by [bl] , is less than or equal to

. We order the elements of the set A such that its first element corresponds to [bl] = 0, and we let s(A) denote the number of elements in A.
For any s(A)-dimensional vector Ξ, we let Ξ(l) denote its lth component, and for any two s(A)-dimensional vectors a,b, we let ab denote the product of each component of a raised to the corresponding component of b. Finally, we let I [·] be an indicator function, taking the value 1 if its argument is true and 0 otherwise. The local polynomial estimator of the conditional αth quantile function at an observation zi involves α-quantile regression (see Koenker and Bassett, 1978) on observations that lie in the defined cells of zi. Specifically, let the vector

minimize the objective function

where we recall that ρα(·) ≡ α|·| + (2α − 1)(·)I [· < 0] . The conditional quantile estimator that will be used in the first stage will be the value

.
A computational advantage of using this estimator is that its evaluation can be carried out by linear programming techniques, whereby a solution can be reached in a finite number of simplex iterations. Since the objective function is globally convex, the solution found is guaranteed to be a global minimizer.
The second stage of the estimation procedure involves this local polynomial estimation procedure of the conditional quantile function, at two particular quantiles, 0 < α1 < α2 < 1.5
We note that any two quantiles may be used in this stage. One natural choice would be α1 = 0.25, α2 = 0.75 because the interquartile range is typically used as a quantile-based measure of dispersion in practice.

We let

denote the second-stage estimator.
2.3. Third Stage: Reweighting and Estimation of a Partially Linear Model
The third-stage estimator is based on the relationship between the propensity score estimated in the first stage and the conditional interquartile range estimated in the second stage. This relationship arises from the result that the conditional distribution function of the outcome equation, given the selection variable is 1 and the regressors, can be expressed as a function of the propensity score.6
This result is based on the assumption of strict monotonicity of the c.d.f. of the random variable νi, the disturbance in the selection equation.


where

is the unknown conditional distribution function of εi given the event involving νi, p = P(νi ≤ μ(w)/σ1(w)) ≡ Fνi(μ(w)/σ1(w)), and the last equality is based on μ(w)/σ1(w) = Fνi−1(p).
7This result was first used in the work of Ahn and Powell (1993), where the authors assumed that the selection equation disturbance term was additively separable and distributed independently of the regressors. Although we relax their homoskedasticity assumption, we require additive separability and multiplicative heteroskedasticity to express the distribution function as a function of the propensity score.
The third-stage estimator is based on three such functionals. First, we note that


where the second equality results from the established result that the conditional quantile of εi depends on wi only through the propensity score pi, with λα2(·) denoting the unknown selection correction function. Similarly we have

Letting Δλ(pi) = λα2(pi) − λα1(pi), we now have

This result will prove very useful when combined with the more conventional selection correction equation

where λ(pi) = E [εi|di = 1,zi] . We notice that (2.15) has a similar form to the conditional expectation in Donald (1995). Following a similar approach, we now combine (2.14) and (2.15). Define the transformed variables


and define

Then we have the following relationship:

This now looks like the partially linear form of the conditional expectation function in the homoskedastic sample selection model. Assuming the values

were observed for the selected observations, we could estimate β0 by the same procedure used in Ahn and Powell (1993).
8We note that any of the existing estimators for the partially linear model, such as in Robinson (1988) and Andrews (1991, 1994), could be used in this stage.

where

. As pointed out in Powell (1989) and Ahn and Powell (1993), if pi is continuously distributed, such ties where pi = pj will occur with probability 0, making it impossible to translate the condition in (2.20) into a feasible estimator of β0. Nonetheless, if the function

is smooth, then first differencing can be applied to pairs where pi is close to pj, resulting in (2.20) holding approximately.
This suggests an estimator based on weighting across pairs, assigning relatively large weight to pairs of observations for which the propensity scores are close and relatively low weight to pairs of observations for which the propensity scores are far apart. If

were observed, one could follow Ahn and Powell (1993) and assign kernel weights to pairs of observations based on the distance between their estimated propensity scores. This would lead to an infeasible weighted least squares estimator of the form

where k(·) is a kernel function assigning weights to pairs and h3n is a bandwidth converging to 0 as the sample size increases, ensuring that in the limit, only pairs with identical propensity score values are assigned positive weight.
This estimator is infeasible because the values

are not observed. However, a feasible estimator is immediately suggested, since the second stage of the estimation procedure can be used to construct estimators of

as follows:
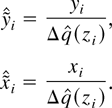
So we can define the third-stage estimator as

where the trimming functions τi ≡ τ(zi) are incorporated in the estimator. These functions trim away observations for which zi lies outside

, a compact subset of

, to ensure that only precise estimators of the conditional interquartile range are used.
We conclude this section by commenting on some important issues regarding implementing our procedure in practice.
Remark 2.1. Our procedure requires the choice of multiple smoothing parameters by the econometrician. Although rate conditions on these parameters are given in the following section, they give no indication on how to select values for a given sample. However, the semiparametric literature provides many guidelines for smoothing parameter selection when estimating nonparametric components of the model. For example, h2n may be selected by adopting data driven approaches that accommodate prespecified rate conditions, such as proposed in Chen and Khan (2000) and Khan (2001). Also, the parameters h1n and h3n may be selected by the cross validation procedures mentioned in Ahn and Powell (1993) and Chen and Khan (2003).
Other parameters that are at the discretion of the econometrician are the quantile pair α1,α2 and the trimming function. For the quantile pair, it was mentioned that one natural choice would be α1 = 0.25, α2 = 0.75. However, as detailed in the next section, the asymptotic variance of our estimator depends on the choice of quantile pair. The expression for this asymptotic variance can provide some insight on pair selection for maximizing asymptotic efficiency, which would involve a trade-off between having the quantiles as spread out as possible and having them away from the extremes, where they are estimated imprecisely. Expanding on this point, efficiency can be further improved by combining various estimators of β0 that are based on various quantile pairs, perhaps by extending the generalized method of moments (GMM) framework suggested in Buchinsky (1998). Finally, we feel the choice of trimming function is not as important as the other smoothing parameters. Trimming functions are included primarily for technical reasons, to help alleviate the common problem of imprecise nonparametric estimation in low density areas. In practice they can simply be indicator functions that throw away observations where the regressors take extreme values.
Remark 2.2. Focusing on equation (2.20), we consider the situation where β0 includes an intercept term, in which case the first component of xi, denoted by xi(0), equals 1. Therefore, we have

We note that under homoskedasticity the preceding difference is 0 whenever pi = pj, implying that our kernel-weighted regressor matrix will be singular in the limit. However, homoskedasticity is a testable restriction, and if it cannot be rejected Ahn and Powell (1993) can be used to estimate the slope coefficients. In this situation, the intercept term, which is of interest in the treatment effects literature, can be estimated separately by exploiting its “identification at infinity” (Heckman, 1990) as is done in Andrews and Schafgans (1998). On the other hand, from standard results involving the estimability of a subset of regression parameters (see, e.g., Amemiya, 1985), our estimator of the slope coefficients will still be consistent under homoskedasticity, and if heteroskedasticity is indeed present, our procedure will simultaneously estimate the intercept term and slope coefficients at the parametric (root-n) rate.
Remark 2.3. It is worth noting the similarities and differences our approach has with the estimation procedure introduced in Carroll (1982) and Robinson (1987) for the heteroskedastic linear model and in Andrews (1994) for the heteroskedastic partially linear model.9
This type of procedure is also used to estimate a heteroskedastic nonlinear regression model in Delgado (1992) and Hildago (1992).
The following sections discuss the asymptotic properties of this three-stage procedure.
3. REGULARITY CONDITIONS
The conditions we need for developing the limiting distribution of the estimator are similar to but more detailed than those required in Ahn and Powell (1993).10
In this section we assume that β0 does include an intercept term to be estimated. As discussed in Remark 2.2, the intercept cannot be consistently estimated under conditional homoskedasticity, though the slope coefficients can be. Thus we are implicitly assuming that either conditional heteroskedasticity is present or that the parameter of interest is the last k components of β0.
Assumption I (Identification). The distribution of the propensity score pi has a density with respect to Lebesgue measure, with density function denoted by fp(·). Defining the following functions of pi:

we require that the matrix

have full rank.
We next impose the following conditions on the third-stage kernel function used to match propensity score values and on its bandwidth sequence.
Assumption K3 (Third-Stage Kernel Function). The kernel function k(·) used in the third stage is assumed to have the following properties.
K3.1. k(·) is twice continuously differentiable with bounded second derivative and has compact support.
K3.2. k(·) is symmetric about 0.
K3.3. k(·) is a fourth-order kernel:

Assumption H3 (Third-Stage Bandwidth Sequence). The bandwidth sequence h3n used in the third stage is of the form

where c3 is some constant and

.
The following assumption characterizes the order of smoothness of density and conditional expectation functions.
Assumption S1 (Order of Smoothness of Functions of the Propensity Score).
S1.1. The functions fp(·), E [τi|pi = ·], and

have order of differentiability of 4, with fourth-order derivatives that are bounded. The function

is fifth-order differentiable, with bounded fifth derivative.
We next impose conditions associated with estimation of the interquartile range. This involves smoothness assumptions on the conditional quantile functions and on the distributions of zi and the residuals associated with the quantile functions.
Assumption RD1 (Regressor Distribution). The regressor vector can be decomposed as zi = (zi(c)′,zi(ds)′)′ where the kc-dimensional vector zi(c) is continuously distributed and the kds-dimensional vector zi(ds) is discretely distributed. Letting fZ(c)|Z(ds)(·|z(ds)) denote the conditional density function of zi(c) given zi(ds) = z(ds), we assume it is bounded, bounded away from 0, and Lipschitz continuous on

.
Letting fZ(ds)(·) denote the mass function of zi(ds), we assume a finite number of mass points on

. Finally, we let fZ(·) denote fZ(c)|Z(ds)(·|·) fZ(ds)(·).
Assumption S2 (Order of Smoothness of Conditional Quantile Functions).
S2.1. For all values of zi(ds), the functions qα2(·),qα1(·) are bounded and M2 times continuously differentiable with bounded M2th derivatives, with respect to zi(c) on

.
S2.2. The polynomial used for the second-stage quantile function estimators is of order M2.
Assumption CED (Outcome Equation Conditional Error Distribution). The homoskedastic component of the outcome equation error term, conditional on selection and zi, denoted by εi|di = 1,zi, has a continuous distribution with density function that is bounded, positive, and continuous, for all

.
Assumption H2 (Second-Stage Bandwidth Sequence for Interquartile Range Estimation). The bandwidth sequence used to estimate the conditional interquartile range is of the form

where c2 is a constant and γ2 ∈ ((δ + ½)/M2, (1 − 4δ)/3kc).
The final set of assumptions involve restrictions for the first-stage kernel estimator of the propensity score. This involves smoothness conditions on both the propensity scores pi and the distribution of the regressors in the selection equation and the rate at which the first-stage bandwidth sequence decreases to 0.
Assumption RD2 (Distribution of Selection Equation Regressors). The regressor vector in the selection equation can be decomposed as wi = (wi(c)′,wi(ds)′)′ where the wc-dimensional vector wi(c) is continuously distributed and the wd-dimensional vector wi(ds) is discretely distributed.
Letting fW(c)|W(d)(·|w(ds)) denote the conditional density function of wi(c) given wi(ds) = w(ds), we assume it is bounded away from 0 and ∞ on

, a predetermined compact subset of the support of wi. Following Ahn and Powell (1993), we redefine di to take the value 0 if

.
Letting fW(ds)(·) denote the mass function of wi(ds), we assume a finite number of mass points on

. Finally, we let fW(·) denote fW(c)|W(ds)(·|·) fW(ds)(·).
Assumption PS (Order of Smoothness of Functions Involving the Selection Regressors). For each w(d) in the support of wi(d), pi and fW(·) are bounded and continuously differentiable of order M1 functions of wi(c), where M1 is an even integer satisfying M1 > wc /(1/3 − 2δ).
Assumption K1 (First-Stage Kernel Function Condition). The kernel function K(·) used in the first stage is of bounded variation, has bounded support, integrates to 1, and is of order M1, where the order of a kernel function was defined in Assumption K3.
Assumption H1 (Rate Condition on First-Stage Bandwidth Sequence). The bandwidth sequence h1n of the first-stage kernel estimator of the propensity score is of the form

where c1 is some constant and γ satisfies

where δ is regulated by Assumption H3.
Remark 3.1. These regularity conditions are quite standard when compared to other estimators in the semiparametric literature. They are very similar to those required in Ahn and Powell (1993), and we state the important similarities and differences here.
(i) The identification in Assumption I is analogous to Assumption 3.4 in Ahn and Powell (1993). As discussed in that paper, with the assumption of a linear index in the selection equation, an exclusion restriction is required for identification of β0. Specifically, it is required that a component included in wi be excluded from xi. We impose this exclusion restriction for the results in this paper as the special case where σ2(·) ≡ 1 corresponds to the homoskedastic model. Although it may be possible to identify the parameter β0 without an exclusion restriction by the “nonlinearity” induced by the presence of the scale functions, we are not comfortable with requiring heteroskedasticity for identification without exclusion.
(ii) Assumptions RD1, S2, and CED, which impose conditions on the regressors and error term in the outcome equation, are generally not required for the homoskedastic model considered in Ahn and Powell (1993). They are imposed here to ensure uniform rates of convergence for the conditional quantile estimator used in the second stage of our procedure.
4. ASYMPTOTIC PROPERTIES
Here we briefly discuss the asymptotic properties of the proposed three-stage estimation procedure. The first result, illustrated in the following lemma, establishes the asymptotic difference between the proposed estimator and the infeasible estimator that assumes

are observed for observations with di = 1.
11We note that this result is in contrast to the results found in Carroll (1982) and Robinson (1987) for the heteroskedastic linear regression model and in Andrews (1994) for the (partially) heteroskedastic partially linear model, where asymptotic equivalence is established for their GLS-type procedures.
LEMMA 4.1. Let

be defined as in equation (2.21), with the trimming functions τi,τj included. Then under the regularity conditions detailed in the previous section,

with

where q1i,q2i denote qα1(zi) and qα2(zi), respectively, and fU2|Z,fU1|Z denote the conditional density functions of the residuals associated with the conditional quantile functions.
An immediate implication of this lemma is that the arguments developed in Powell (1989) and Ahn and Powell (1993) can be used to derive the limiting distribution of the feasible estimator

. The limiting distribution is characterized in the following theorem.
THEOREM 4.1. The feasible estimator is

-consistent and asymptotically normal; specifically, we have

where Ωxx is the covariance matrix of the k-dimensional vector ψi ≡ ψ1i + ψ2i with

with

denoting the derivative of

is the “residual”

For the purpose of conducting inference we propose a consistent estimator of the asymptotic variance matrix. To estimate the component Σxx we propose a standard “plug-in” estimator that replaces unknown values and expectations with estimated values and sample averages, respectively:

Estimation of Ωxx is more involved, because it involves the unknown selection correction function and its derivative. We propose the following estimator, which is analogous to those found in Powell (1989) and Ahn and Powell (1993):

where

with

with

and where

with

where k′(·) denotes the derivative of the third-stage kernel function.
Finally, to estimate ψ2i we require an estimator of the conditional density of the quantile residuals. Letting

denote the estimated residual of the higher quantile, we propose a kernel estimator of its conditional density function:

where

is a nonnegative kernel function with bounded support that integrates to 1 and is continuously differentiable with bounded derivative. The sequence νn satisfies the constraints

A similar estimator can be constructed for the density of the lower quantile residual. With these in hand we can construct the following estimator of

:

The following theorem, whose proof is left to the Appendix, establishes the consistency of the estimator

.
THEOREM 4.2. Under the conditions used to establish Theorem (4.1),

5. CONCLUSIONS
This paper introduces a new estimator for a semiparametric sample selection model that is consistent in the presence of multiplicative heteroskedasticity of unknown form. The estimation procedure involves three stages, two of which are analogous to the steps taken in the estimators introduced in Powell (1989), Ahn and Powell (1993), Donald (1995), and Kyriazidou (1997). The new estimator is shown to converge at the parametric rate and has an asymptotic normal distribution.
The work here suggests areas for future research. As was suggested, it would be useful to formally construct a pretest for conditional heteroskedasticity to see if the slope coefficients and the intercept term could be estimated simultaneously. The effect of this pretesting procedure on the limiting distribution theory developed here is also worth exploring. Also, one could consider imposing the multiplicative structure to model heteroskedasticity in other bivariate models, such as the type 3 Tobit model, where the selection equation now involves a censored, instead of binary, variable.
APPENDIX
To keep expressions notationally simple, in this section we let q1i,q2i denote qα1(zi) and qα2(zi), respectively. We denote estimated values by

. For the second-stage nonparametric procedure, we let Cni denote Cn(zi). Also, for any matrix A with elements aij, we let ∥A∥ denote ([sum ]i,j aij2)1/2.
We begin by stating two uniform convergence results, one for each of the nonparametric estimators used in the first two stages of the estimation procedure. These uniform rates can be found in Ahn and Powell (1993) and Chaudhuri et al. (1997), respectively.
LEMMA A.1. (From Ahn and Powell, 1993, Lemma A.1). Under Assumptions RD2, PS, K1, H1, and H3

LEMMA A.2. (From Chaudhuri et al., 1997, Lemma 4.1). Under Assumptions RD1, S2, H2, and CED,

Before proceeding to the arguments used in the proof, we first state rates of convergence for various terms that will arise in the proof. These rates arise directly from the preceding two lemmas and also from Assumptions H1–H3. We adopt the notation that ∥·∥∞ denotes the supremum over the set in question.


The proof of Theorem 4.1 is based on an asymptotically linear representation for

. By (2.22), we have

where

and

The following lemma establishes the probability limit of A.9.
LEMMA A.3. Under Assumptions I, K3.1, K3.2, H3, RD1, S2, H2, CED, RD2, PS, K1, and H1,

Proof. Define

We first show that

Let

and Δrnij = rnj − rni. We thus have

We note that Δqi is bounded away from 0 on the support of τi. Noting that

we have by the bounds on k(·) and the support of τi and Assumption H2 that

It thus follows by the bound on k(·) that

where the second equality follows by (A.7). This establishes (A.12). By the same arguments of Lemma 3.1 and Theorem 3.1 in Ahn and Powell (1993) it follows that

which concludes the proof. █
We next derive a linear representation for

. The following lemma establishes the difference between

and the analogous expression involving the true values of the conditional interquartile range.
LEMMA A.4. Under Assumptions K3.1, K3.2, H3, H2, RD1, S2, and CED,

Proof. We replace the first

in (A.10) with

and derive a linear representation for

We note the preceding expression can be expressed as


We next linearize

as

It follows that the quadratic terms in this expansion are op(n−1/2) by (A.7). Plugging the linear term of the expansion into (A.14) and (A.15) yields the expression


Writing Δqi as q2i − q1i, we have that (A.16) and (A.17) can be expressed as


plus analogous terms involving

. We focus our attention on (A.18).
By a mean value expansion of

around h3n−1k((pi − pj)/h3n) and the bound on the second moments of

it follows that

can be replaced with h3n−1k((pi − pj)/h3n) in (A.18) with a resulting remainder term that is

where the equality follows from (A.3). Noting that we can replace

with

in (A.18), where we recall that the

is a mean 0 residual term, we will first show that

and we will then derive a linear representation for

To show (A.20), we use the local Bahadur representations for the local polynomial estimator established in Chaudhuri (1991a) and Chaudhuri et al. (1997). In our context this can be expressed as

where q2(k,i)* denotes the Taylor polynomial approximation of q2k for zk close to zi, fU2,Z(·,·) denotes the joint density function of the quantile residual and zk; Rni is a remainder term converging to 0 at a rate depending on the bandwidth h2n. Using the same arguments as in Chen and Khan (2000, 2001), it can be shown that under Assumptions RD1, S2, H2, and H3 that

where the second equality follows from (A.4). Thus to show (A.20), it will suffice to show the asymptotic negligibility of the following third-order U-statistic:

We next replace q2(k,i)* with q2k. By Assumption S2.1, this replacement results in a remainder term that is Op(h3n−1h2nM2), which is op(n−1/2) by (A.6). Let χi = (yi,zi′,q2i,pi,u2i,ũi,τi,di)′. Let

denote the expression in the preceding triple summation after this replacement. It follows after a change of variables that

where the second equality follows from (A.5). We can thus apply the projection theorem for U-statistics in Ahn and Powell (1993). We note that

where the last three terms denote expectations conditional on first, second, and third arguments, respectively, and the last term is 0 because of the presence of

. We thus have by Lemma A.3 in Ahn and Powell (1993) that

establishing (A.20).
It thus remains to derive a linear representation for (A.21). To do so we again plug in the linear representation for the conditional quantile estimator; this yields another mean 0 third-order U-statistic after showing that the bias term is asymptotically negligible. We will let

denote the term in the triple summation of this U-statistic. As before, we have

, and will derive a linear representation for

Once again, we ignore the bias component of the nonparametric estimator, as it converges to 0 at the parametric rate. We will thus derive a linear representation for

where

To derive an expression for (A.25), we will again use Chebyshev's inequality. Since each term in the summation has mean 0, we will show that

To do so, we make a change of variables in the definition of Ξ1n(zk). Using the change of variables ui = (zk(c) − zi(c))/h2n and vi = (pi − pj)/h3n, by the dominated convergence theorem,

Expression (A.26) follows by noting that pi is a function of zi. Thus we have shown that (A.21) has the following linear representation:

and identical arguments can be used to show that double summations involving

have analogous linear representations. Combining these results, we get that (A.13) has the following linear representation:

The remaining step involves showing that

This can be done by using similar arguments as before, so we only sketch the details. First, we note that we can replace

with h3n−1k((pi − pj)/h3n), and the remainder term is asymptotically negligible as shown previously. We can also replace

, and the remainder terms are of order

, which are (uniformly) of order op(n−1/2). Thus we will show

Note that we can replace

. We also note that we need only show negligibility of the term involving

because the same argument can be used for

. We can write

and as before linearize the difference and plug in the linear representation of the conditional quantile estimator, yielding a centered third-order U-statistic plus a remainder term that is op(n−1/2). The term in the U-statistic involving

is negligible by the same arguments as used in showing (A.23). The term in the U-statistic involving

is also negligible, as a result of presence of h3n−1k((pi − pj)/h3n), the smoothness assumption on

(Assumption S1.1), and the rate condition on h3n (Assumption H3). This shows (A.30) and hence (A.29).
This proves the lemma and establishes the asymptotic difference between the feasible and infeasible estimators, as stated in Lemma 4.1. █
The final step in deriving the limiting distribution of the estimator is to establish a linear representation for Sxy. This is done in the following lemma, whose proof is omitted because it follows from identical arguments used in the proof of Theorem 3.1(ii) of Ahn and Powell (1993).
LEMMA A.5. Under Assumptions K3, H3, S1, RD2, PS, K1, and H1,

The limiting distribution in Theorem 4.1 now easily follows.
Proof of Theorem 4.2. We note that the consistency of

follows easily from Lemma A.3. To show consistency of

we first define

as

We show the following lemma.
LEMMA A.6. Under the assumptions,

Proof. First we note that by standard results from kernel estimation (e.g., Bierens, 1987) the expression

converges uniformly (in wi) in probability to the density of wi, fW(wi), so we focus on the expression

We decompose

as

and decompose

accordingly. Concentrating on the first term after this decomposition, we note that by the bounds on k′(·),K(·), the trimming functions, and xl,xj in the support of the trimming functions, and also by the moment conditions on yl,yj, we can replace

, and the resulting remainder term (uniformly in i) is

, which by (A.3) and Assumptions H1 and H3, is op(1). Similarly, exploiting the result that

the second term (involving

can be replaced with

with a resulting remainder term that is uniformly op(1). We can thus turn our attention to the expression

We replace

with pl − pj. Again exploiting boundedness (this time involving the second derivative of k(·)) and moment conditions, this time the remainder term is uniformly

, which also is op(1) by Assumptions H1 and H3, and Lemma A.1. We are thus left with the expression

We treat wi as fixed and multiply the preceding expression by n/(n − 1); we have a second-order U-statistic. We note that the expectation of the squared norm of this U-statistic is O(h3n−3h1n−wc), which is o(n) by Assumptions H1 and H3. Thus by Lemma A.3(i) in Ahn and Powell (1993), the U-statistic converges in probability to the expected value of the term in the double summation divided by h3n2h1nwc. Working with this sequence of expected values, the usual change of variables, and the bounded convergence theorem, the sequence of expected values converges to

. Furthermore, it follows by uniform laws of large numbers for U-statistics (see, e.g., Sherman, 1994) that this convergence is uniform in wi. This establishes the lemma. █
Next we define

and

An immediate consequence of the lemma, using the uniform convergence of

, is that

converges uniformly in i to ψ12i. We note that similar, though simpler, arguments used in Lemma A.6 can be used to establish the uniform convergence of

. As a final step we show uniform convergence of

. We first show uniform convergence of

. A mean value expansion of

around

yields a remainder term of order

, which is op(1) by the conditions on νn and Lemma A.2.
Also, similar, though simpler, arguments than used in Lemma A.6 can be used to establish uniform convergence of

to

. The uniform convergence of

then follows from the uniform convergence of

, respectively.
It immediately follows that

Thus by the law of large numbers, we have

. Slutsky's theorem then implies Theorem 4.2. █
References
REFERENCES
Ahn, H. &
J.L. Powell
(1993)
Semiparametric estimation of censored selection models with a
nonparametric selection mechanism.
Journal of Econometrics
58,
3–29.Google Scholar
Amemiya, T.
(1985)
Advanced Econometrics.
Cambridge:
Harvard University Press.
Andrews, D.W.K.
(1991)
Asymptotic normality for nonparametric and semiparametric
regression models.
Econometrica
59,
307–345.Google Scholar
Andrews, D.W.K.
(1994)
Asymptotics for semiparametric econometric models via stochastic
equicontinuity.
Econometrica
62,
43–72.Google Scholar
Andrews, D.W.K. &
M.M.A. Schafgans
(1998)
Semiparametric estimation of the intercept of a sample selection
model.
Review of Economic Studies
65,
497–517.Google Scholar
Bierens, H.J.
(1987)
Kernel estimators of regression functions. In
T.F. Bewley (ed.),
Advances in Econometrics, Fifth World Congress,
vol. 1, pp.
99–144.
Cambridge:
Cambridge University Press.
Buchinsky, M.
(1998)
Recent advances in quantile regression models: A practical
guideline for empirical research.
Journal of Human Resources
33,
88–126.Google Scholar
Carroll, R.J.
(1982)
Adapting for heteroskedasticity in linear models.
Annals of Statistics
10,
1224–1233.Google Scholar
Chaudhuri, P.
(1991a)
Nonparametric estimates of regression quantiles and their local
Bahadur representation.
Annals of Statistics
19,
760–777.Google Scholar
Chaudhuri, P.
(1991b)
Global nonparametric estimation of conditional quantiles and their
derivatives.
Journal of Multivariate Analysis
39,
246–269.Google Scholar
Chaudhuri, P.,
K. Doksum, &
A. Samarov
(1997)
On average derivative quantile regression.
Annals of Statistics
25,
715–744.Google Scholar
Chen, S.
(1999)
Semiparametric estimation of heteroskedastic binary choice sample
selection models under symmetry.
Manuscript,
Hong Kong University of Science and Technology.
Chen, S. &
S. Khan
(2000)
Estimating censored regression models in the presence of
nonparametric multiplicative heteroskedasticity.
Journal of Econometrics
98,
283–316.Google Scholar
Chen, S. &
S. Khan
(2001)
Semiparametric estimation of a partially linear censored regression
model.
Econometric Theory
17,
567–590.Google Scholar
Chen, S. &
S. Khan
(2003)
Rates of convergence for estimating regression coefficients in
heteroskedastic discrete response models.
Journal of Econometrics,
in press.Google Scholar
Choi, K.
(1990)
Semiparametric Estimation of the Sample Selection Model Using Series
Expansion and the Propensity Score.
Manuscript,
University of Chicago.
Delgado, M.
(1992)
Semiparametric generalized least squares in the multivariate
nonlinear regression model.
Econometric Theory
8,
203–222.Google Scholar
Donald, S.G.
(1995)
Two-step estimation of heteroscedastic sample selection models.
Journal of Econometrics
65,
347–380.Google Scholar
Gronau, R.
(1974)
Wage comparisons: A selectivity bias.
Journal of Political Economy
82,
1119–1144.Google Scholar
Heckman, J.J.
(1976)
The common structure of statistical models of truncation, sample
selection, and limited dependent variables and a simple estimator of
such models.
Annals of Economic and Social Measurement
15,
475–492.Google Scholar
Heckman, J.J.
(1979)
Sample selection bias as a specification error.
Econometrica
47,
153–161.Google Scholar
Heckman, J.J.
(1990)
Varieties of selection bias.
American Economic Review
80,
313–318.Google Scholar
Hildago, J.
(1992)
Adaptive estimation in time series models with heteroskedasticity
of unknown form.
Econometric Theory
8,
161–187.Google Scholar
Horowitz, J.L.
(1992)
A smoothed maximum score estimator for the binary response model.
Econometrica
60,
505–531.Google Scholar
Khan, S.
(2001)
Two stage rank estimation of quantile index models.
Journal of Econometrics
100,
319–355.Google Scholar
Khan, S. &
J.L. Powell
(2001)
Two-step quantile estimation of semiparametric censored regression
models.
Journal of Econometrics
103,
73–110.Google Scholar
Kyriazidou, E.
(1997)
Estimation of a panel data sample selection model.
Econometrica
65,
1335–1364.Google Scholar
Li, Q. &
J. Racine
(2000)
Nonparametric Estimation of Regression Functions with Both Categorical
and Continuous Data.
Manuscript,
Texas A&M University.
Mroz, T.A.
(1987)
The sensitivity of an empirical model of married women's hours
of work to economic and statistical assumptions.
Econometrica
55,
765–799.Google Scholar
Powell, J.L.
(1989)
Semiparametric Estimation of Censored Selection Models.
Manuscript,
University of Wisconsin.
Robinson, P.M.
(1987)
Asymptotically efficient estimation in the presence of
heteroskedasticity of unknown form.
Econometrica
56,
875–891.Google Scholar
Robinson, P.M.
(1988)
Root-N-consistent semiparametric regression.
Econometrica
56,
931–954.Google Scholar
Rosenbaum, P.R. &
D.B. Rubin
(1983)
The central role of the propensity score in observational studies
for causal effects.
Biometrika
70,
41–55.Google Scholar
Sherman, R.P.
(1994)
Maximal inequalities for degenerate U-processes with applications
to optimization estimators.
Annals of Statistics
22,
439–459.Google Scholar
 You have
Access
- 27
- Cited by