Refine search
Actions for selected content:
2 results
Investigation of Galactic Populations and Merger Process Using Machine Learning Methods
-
- Journal:
- Proceedings of the International Astronomical Union / Volume 21 / Issue S397 / August 2025
- Published online by Cambridge University Press:
- 05 October 2026, pp. 115-122
- Print publication:
- August 2025
-
- Article
-
- You have access
- Open access
- HTML
- Export citation
-
We combine APOGEE DR17 spectroscopy with Gaia DR3 astrometry to investigate the chemo-dynamical structure of the Milky Way using unsupervised machine learning. After applying strict quality cuts, we selected a high-quality sample of 135,080 giant stars and derived their orbital parameters in the McMillan potential. To mitigate disk dominance, a cut of
 $e_{p}$
 $>$ 0.25 was applied. Dimensionality reduction with PCA and clustering with K-means were tested across three input spaces: chemical abundances, kinematic parameters, and their combination. The most robust separation of stellar populations is obtained when using chemical abundances alone. The resulting clusters correspond to the thin disk, thick disk, halo, and an accreted component, as revealed in chemical-abundance and Lindbland diagrams. Our results highlight the effectiveness of abundance-driven clustering in disentangling Galactic stellar populations and tracing ex-situ stars, providing a data-driven framework for future studies of Galactic archeology.


Tracing Galactic Mergers: A Data-Driven Search for Enceladus Stars in the Solar Neighborhood
-
- Journal:
- Proceedings of the International Astronomical Union / Volume 21 / Issue S397 / August 2025
- Published online by Cambridge University Press:
- 05 October 2026, pp. 102-106
- Print publication:
- August 2025
-
- Article
-
- You have access
- Open access
- HTML
- Export citation
-
We investigate the impact of machine learning algorithm combinations on the identification of Gaia–Enceladus (GSE) stellar populations in the solar neighborhood. Using high-quality chemical abundances from APOGEE DR17 and precise astrometry from Gaia, we apply unsupervised learning pipelines combining PCA or t-SNE for dimensionality reduction with K-means, GMM, or HDBSCAN clustering algorithms. Our aim is to assess consistency and performance in selecting the GSE component. The optimal cluster is then used to estimate the initial gas mass of GSE through a one-zone chemical evolution model. We find that the t-SNE + HDBSCAN pipeline yields the most chemically and dynamically coherent identification, and our best-fit chemical evolution model predicts an initial gas mass of
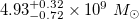 $4.93^{+0.32}_{-0.72} \times 10^9~M_\odot$ for the progenitor.
