To save content items to your account,
please confirm that you agree to abide by our usage policies.
If this is the first time you use this feature, you will be asked to authorise Cambridge Core to connect with your account.
Find out more about saving content to .
To save content items to your Kindle, first ensure no-reply@cambridge.org
is added to your Approved Personal Document E-mail List under your Personal Document Settings
on the Manage Your Content and Devices page of your Amazon account. Then enter the ‘name’ part
of your Kindle email address below.
Find out more about saving to your Kindle.
Note you can select to save to either the @free.kindle.com or @kindle.com variations.
‘@free.kindle.com’ emails are free but can only be saved to your device when it is connected to wi-fi.
‘@kindle.com’ emails can be delivered even when you are not connected to wi-fi, but note that service fees apply.
This chapter examines the foundations and limits of computation and their implications for artificial intelligence. It begins with the Entscheidungsproblem and Alan Turing’s formulation of the universal Turing machine, introducing the idea that computation itself can be studied independently of any physical machine. The chapter explains the halting problem and related undecidability results, showing that some well-defined questions cannot be answered by any algorithm, even in principle. It then turns to computational complexity, distinguishing between problems that are solvable in theory and those that are solvable efficiently, and introduces the P versus NP problem as a central open question. The chapter explores how computational hardness can function not only as a limitation but also as a resource, underpinning modern cryptography through one-way functions and key-exchange protocols. Finally, the discussion turns to artificial intelligence, contrasting early rule-based approaches with modern machine learning and neural networks. Recent advances in deep learning and large language models are presented as the culmination of decades of theoretical insight, highlighting both their remarkable capabilities and the enduring structural limits imposed by computation itself.
While deep learning (DL) methods have expanded the approach to solving state estimation problems in data assimilation (DA), a robust approach requires extending them for uncertainty quantification. In this work, we propose a method to represent location-based uncertainty through random, spatiotemporally coherent displacements in physical space, which are used to sample states in the vicinity of a given reference state. We integrate this strategy into an end-to-end variational DA framework, termed 4DVarNet-LU, and compare its performance with a UNet baseline, demonstrating improved reconstruction skill through the explicit use of prior state information. Trained deterministically in output and stochastically in input, we demonstrate that at inference, we see improvement in skill when using information from initial conditions. Using observation system simulation experiments based on a single-layer quasi-geostrophic model with sparse pseudo-nadir altimetry observations, we evaluate reconstruction mean and ensemble skill. Results show that 4DVarNet-LU consistently outperforms the UNet baseline in terms of root mean square error (RMSE) and continuous ranked probability score (CRPS), with increased robustness to initial condition bias and improved temporal stability. While the method does not propose to account for all different uncertainty sources in DA, it provides a structured way for modeling and training DL models for dealing with location-based uncertainty. Future work may extend this approach to account for additional sources of uncertainty and end-to-end ensemble generation.
Modeling feature interactions in tabular data remains a key challenge in predictive modeling, for example, as used for insurance pricing. This paper proposes the tree-like pairwise interaction network (PIN), a novel neural network architecture that explicitly captures pairwise feature interactions through a shared feed-forward neural network architecture that mimics the structure of decision trees. PIN enables intrinsic interpretability by design, allowing for direct inspection of interaction effects. Moreover, it allows for efficient SHapley’s Additive exPlanation computations because it only involves pairwise interactions. We highlight connections between PIN and established models such as GA$^{2}$Ms, gradient boosting machines, and graph neural networks. Empirical results on the popular French motor insurance dataset show that PIN outperforms both traditional and modern neural network benchmarks in predictive accuracy, while also providing insight into how features interact with each another and how they contribute to the predictions.
Shie Mannor, Technion - Israel Institute of Technology, Haifa,Yishay Mansour, Tel-Aviv University,Aviv Tamar, Technion - Israel Institute of Technology, Haifa
This chapter addresses the curse of dimensionality through value function approximation. Parameterized function approximators represent value functions compactly and generalize across states. The chapter frames approximate policy evaluation as supervised learning. Key theoretical objects include the projection operator and projected Bellman equation. Least squares temporal difference (LSTD) provides a batch solution for linear approximation. Deep Q-networks combining neural networks with experience replay are introduced as the foundation for deep RL successes.
This chapter explores the optimization behind machine learning. Machine learning uses optimization to tune the parameters of a model to fit data, by minimizing the objective function. Fundamentally, this is an inverse problem solved with optimization. We begin with automatic differentiation and backpropagation, as they are the core algorithmic infrastructure needed to obtain gradients to optimize large-scale machine learning models. Automatic differentiation applies the chain rule to the computational graph of a function to compute its derivative with the same computational complexity and the same order accuracy as evaluating the function itself. This is the idea behind backpropagation in neural network training, although automatic differentiation is used more broadly in inverse problems and control. Next, we show how to train neural networks with optimization. This involves learning rate scheduling, batch normalization, hyperparameter optimization, and vanishing and exploding gradients. We also revisit reinforcement learning from the perspective of deep learning. Finally, we explore how to incorporate physics into machine learning algorithms using techniques from optimization.
In recent years, deep learning has transformed data processing, justifying its use in the current study. These models consist of multiple layers that calibrate weights to optimize accuracy. By mimicking neural processes, these networks facilitate high-performance predictive modeling. This study focused on the application of convolutional neural networks for forecasting Sargassum seaweed arrivals in Guadeloupe, using varied climatic data such as winds, surface currents, satellite images, and observations of seaweed arrivals on the Guadeloupe coast. We tested two different approaches: classification models for forecasting up to 14 days and zone regression models for forecasting up to 14 days, also indicating a probability of algae arrival. The results showed that the classification models achieved a mean accuracy of 94.75%, a mean specificity of 97.42%, and a mean sensitivity of 98.78%. Zone regression models achieved a mean accuracy of around 90%, a mean specificity of around 97%, and a mean sensitivity of around 85%, with a mean MAE of 0.13 and a mean RMSE of 0.18. These models perform better than the decision tree proposed in the state of the art for the same problem.
The cost of high-quality aerodynamics simulations for realistic automotive configurations makes comprehensive design studies unfeasible. Data-driven surrogates (learning from data) are an appealing alternative, and there is no shortage of approaches that target shape-to-aerodynamics predictions. However, there is a fundamental limitation (data insufficiency problem) in this context: owing to the proprietary nature of commercial automotive designs, training datasets are limited to a few freely-available geometries. In a previous work the authors, a strategy to construct datasets for training surrogates was introduced. It enables controlled generation of an arbitrary number of samples, by convex interpolation between a small number of basis geometries. In this work, we extend this strategy by introducing three features, namely size, density, and diversity that characterize more general datasets. These are important to assess how useful is a dataset for a specific prediction task (data for learning). A formal measure of diversity is developed and then, datasets of successively increasing diversity but constant size are constructed. We show that the dataset diversity has an impact on the predictive accuracy of machine learning surrogates. A power-law scaling, $ \varepsilon \hskip0.5em \propto \hskip0.5em {M}^{1/2}\hskip0.1em {m}^{-1/6} $, where $ \varepsilon $ is the prediction error, $ M $ is the diversity, and $ m $ the dataset size, collapses 23 controlled experiments onto a single curve, revealing that diversity dominates size in determining prediction error. The proposed framework allows for more rigorous a priori evaluation of models than is currently possible and can be applied readily to other shape optimization problems.
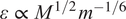
Research that assesses individual judges’ ability to shape decisions typically focuses on courts that publish separate votes and opinions. Yet, many courts issue per curiam judgments that do not permit public dissent. To overcome this limitation, we use a convolutional neural network (CNN) to model the variation in judges’ expressed preferences from language in aggregated judgments. Specifically, we construct a CNN to analyze the written judgments of judge-rapporteurs and opinions of advocates-general from the Court of Justice of the European Union. Along a pro-/anti-EU dimension, we estimate how judgments differ within (1) each case relative to the advocate-general’s opinion, and (2) each judge-rapporteur, which captures how judges alter their writing across cases. Our results provide novel empirical support for theoretical models of European judicial decision-making: more pro-EU opinions driven by the Court, not the advocate-general or the judge-rapporteur, are associated with larger chambers and stronger external signals of compliance.
Accurate short-term precipitation forecasts predominantly rely on dense weather-radar networks, limiting operational value in places most exposed to climate extremes. We present TUPANN (Transferable and Universal Physics-Aligned Nowcasting Network), a satellite-only model trained on GOES-16 RRQPE. Unlike most deep learning models for nowcasting, TUPANN decomposes the forecast into physically meaningful components: a variational encoder–decoder infers motion and intensity fields from recent imagery under optical-flow supervision, a lead-time-conditioned MaxViT evolves the latent state, and a differentiable advection operator reconstructs future frames. We evaluate TUPANN on both GOES-16 and IMERG data, in up to four distinct climates (Rio de Janeiro, Manaus, Miami, La Paz) at 10–180-min lead times using the CSI and HSS metrics over 4–64 mm/h thresholds. Comparisons against optical-flow, deep learning, and hybrid baselines show that TUPANN achieves the best or second-best skill in most settings, with pronounced gains at higher thresholds. Training in multiple cities further improves performance, while cross-city experiments show modest degradation and occasional gains for rare heavy-rain regimes. The model produces smooth, interpretable motion fields aligned with numerical optical flow and runs in near real time due to the low latency of GOES-16. These results indicate that physically aligned learning can provide nowcasts that are skillful, transferable, and global.
This chapter critically reviews the success of existing algorithms in explaining and predicting human behaviour. While traditional statistical methods have limitations in this area, algorithmic approaches have gained popularity. The chapter covers a range of algorithms, including decision trees, neural networks and clustering algorithms, evaluating their strengths and limitations in various applications. It also considers ethical concerns, such as bias and privacy violations and the need for transparency and explainability. The chapter emphasises the importance of interdisciplinary collaboration between computer science, statistics and behavioural science, and the need for ongoing development and refinement of these methods. By evaluating the effectiveness of algorithmic approaches to human behaviour, this chapter is a valuable resource for researchers and practitioners in the field.
Individuals have a surprisingly high capacity for making decisions quickly and still considering a multitude of information. This capability – often referred to as intuition – relies on automatic processes that can be described with neural networks. Particularly parallel constraint satisfaction (PCS) networks – a specific type of interactive activation networks – have been successful in capturing multiple aspects of choice behaviour. PCS models include restrictions to neural networks that capture specific features of cognition. This chapter will describe how PCS and other content models of decision-making can be evaluated and potentially improved by using artificial intelligence, specifically generic multi-layer (deep learning) neural network models. It will exemplify how choice behaviour can be modelled and predicted with PCS. The predictive performance of PCS will be contrasted with that of a generic neural network model. Possibilities and implications for the improvement of content models for choice behaviour using artificial intelligence are discussed.
This chapter explores human cognition as a set of interconnected processes – perception, memory, attention, learning, reasoning, and executive function that allow us to adapt flexibly to complex environments. It contrasts human cognition with artificial intelligence, showing how neural networks and transformers borrow inspiration from the brain but lack intuition, context sensitivity, and self-awareness. Through examples from neuroscience and AI, the chapter highlights how both systems process information, learn, and make decisions. It argues that the future lies not in replacing human cognition but in building augmented cognition – partnerships where AI amplifies human thought and creativity rather than substituting for it.
Part II of the book presents the theorizations of learning for each learning goal (skills, concepts, cultural practices), and the associated genres of teaching. Chapter 4, addressing skills, begins with Information Processing psychology and Behaviorist theory, noting that each of these theories presumes that skills can be rationally analyzed – as a set of rules or as a sequence of steps, respectively. But such shallow skills form a limited subset of skills to be taught. We turn to neural networks as grounding for deep skills that are not reducible to procedural rules.
The James Webb Space Telescope (JWST) hosts a non-redundant Aperture Masking Interferometer (AMI) in its Near Infrared Imager and Slitless Spectrograph (NIRISS) instrument, providing the only dedicated interferometric facility aboard – magnitudes more precise than any interferometric experiment previously flown. However, the performance of AMI (and other high resolution approaches such as kernel phase) in recovery of structure at high contrasts has not met design expectations. A major contributing factor has been the presence of uncorrected detector systematics, notably charge migration effects in the H2RG sensor, and insufficiently accurate mask metrology. Here we present Amigo, a data-driven calibration framework and analysis pipeline that forward-models the full JWST AMI system – including its optics, detector physics, and readout electronics – using an end-to-end differentiable architecture implemented in the Jax framework and in particular exploiting the $\partial$Lux optical modelling package. Amigo directly models the generation of up-the-ramp detector reads, using an embedded neural sub-module to capture non-linear charge redistribution effects, enabling the optimal extraction of robust observables, for example kernel amplitudes and phases, while mitigating systematics such as the brighter-fatter effect. We demonstrate Amigo’s capabilities by recovering the AB Dor AC binary from commissioning data with high-precision astrometry, and detecting both HD 206893 B and the inner substellar companion HD 206893 c: a benchmark requiring contrasts approaching 10 mag at separations of only 100 mas. These results exceed outcomes from all published pipelines and re-establish AMI as a viable competitor for imaging at high contrast at the diffraction limit. Amigo is publicly available as open-source software community resource .
Annual bluegrass (Poa annua L.) is an extremely problematic weed in turfgrass, posing a significant challenge for turfgrass management. Injudicious use of herbicides for controlling this weed has led to resistance issues and environmental concerns. Site-specific weed control offers an opportunity to achieve effective weed control with less herbicide use, but it requires the development of a pipeline for weed detection and localization, as well as a path planning algorithm (PPA). To achieve this, unmanned aerial system (UAS)-based RGB imagery of P. annua plants in bermudagrass [Cynodon dactylon (L.) Pers.] turf was collected at different weed growth stages at two locations in Texas: Deer Park and College Station. A convolutional neural network (CNN) You Only Look Once (YOLO11) and a real-time detection transformer (RT-DETR) model were evaluated for weed detection. The results showed that the YOLO11n model achieved the highest F1 score (0.64) and mean average precision (mAP)@0.50 (0.68), while the RT-DETR-x model achieved the lowest F1 score (0.52) and mAP@0.50 (0.51). The GeoTransform function transforms image coordinates into a world coordinate system with centimeter-level accuracy (mean error = 1.5 cm). However, the precision of the transformation depends on the quality of the orthophoto georeferencing. Additionally, the PPA showed a significant reduction (37.7%) in travel distance compared with the original weed model–derived distance. The research highlighted the potential of UAS-based imagery for weed detection and localization in turfgrass. Further improvements are needed to enhance model performance by modifying the model architecture (e.g., input image size, hyperparameters) and evaluating its robustness across different weed growth stages and turfgrass species.
Chapter 1 introduces basic terminology. Terms such as artificial intelligence, data, algorithm, machine learning, neural networks, deep learning, large language models, generative AI and symbolic AI are presented to develop a sense of what AI is, how it has evolved, and what it does. This chapter also introduces some of the major conceptual disagreements in the field. Different ideas about how to develop AI in the best way drive disagreements, as well as philosophical differences over what intelligence means and whether machines can develop human-like intelligence.
Emphasizing how and why machine learning algorithms work, this introductory textbook bridges the gap between the theoretical foundations of machine learning and its practical algorithmic and code-level implementation. Over 85 thorough worked examples, in both Matlab and Python, demonstrate how algorithms are implemented and applied whilst illustrating the end result. Over 75 end-of-chapter problems empower students to develop their own code to implement these algorithms, equipping them with hands-on experience. Matlab coding examples demonstrate how a mathematical idea is converted from equations to code, and provide a jumping off point for students, supported by in-depth coverage of essential mathematics including multivariable calculus, linear algebra, probability and statistics, numerical methods, and optimization. Accompanied online by instructor lecture slides, downloadable Python code and additional appendices, this is an excellent introduction to machine learning for senior undergraduate and graduate students in Engineering and Computer Science.
The chapter introduces fundamental principles of deep learning. We discuss supervised learning of feedforward neural networks by considering a binary classification problem. Gradient descent techniques and backpropagation learning algorithms are introduced as means of training neural networks. The impact of neuron activations and convolutional and residual network architectures on the learning performance are discussed. Finally, regularization techniques such as batch normalization and dropout are introduced for improving the accuracy of trained models. The chapter is essential to connect advances in conventional deep learning algorithms to neuromorphic concepts.
Pater's (2019) target article proposes that neural networks will provide theories of learning that generative grammar lacks. We argue that his enthusiasm is premature since the biases of neural networks are largely unknown, and he disregards decades of work on machine learning and learnability. Learning biases form a two-way street: all learners have biases, and those biases constrain the space of learnable grammars in mathematically measurable ways. Analytical methods from the related fields of computational learning theory and grammatical inference allow one to study language learning, neural networks, and linguistics at an appropriate level of abstraction. The only way to satisfy our hunger and to make progress on the science of language learning is to confront these core issues directly.
The target article (Pater 2019) proposes to use neural networks to model learning within existing grammatical frameworks. This is easier said than done. There is a fundamental gap to be bridged that does not receive attention in the article: how can we use neural networks to examine whether it is possible to learn some linguistic representation (a tree, for example) when, after learning is finished, we cannot even tell if this is the type of representation that has been learned (all we see is a sequence of numbers)? Drawing a correspondence between an abstract linguistic representational system and an opaque parameter vector that can (or perhaps cannot) be seen as an instance of such a representation is an implementational mapping problem. Rather than relying on existing frameworks that propose partial solutions to this problem, such as harmonic grammar, I suggest that fusional research of the kind proposed needs to directly address how to ‘find’ linguistic representations in neural network representations.