Refine search
Actions for selected content:
288 results
Continuous-time Mallows processes
- Part of
-
- Journal:
- Combinatorics, Probability and Computing , First View
- Published online by Cambridge University Press:
- 26 October 2026, pp. 1-32
-
- Article
-
- You have access
- Open access
- HTML
- Export citation
-
In this article, we introduce Mallows processes, defined to be continuous-time cadlag processes with Mallows distributed marginals. We show that such processes exist and that they can be restricted to have certain natural properties. In particular, we prove that there exist regular Mallows processes, defined to have their inversion numbers
 ${\mathrm{Inv}}_j(\sigma )=|\{i\in [j-1] \, : \, \sigma (i)\gt \sigma (\,j)\}|$ be independent increasing stochastic processes with jumps of size
 $1$. We further show that there exists a unique Markov process which is a regular Mallows process. Finally, we study properties of regular Mallows processes and show various results on the structure of these objects. Among others, we prove that the graph structure related to regular Mallows processes looks like an expanded hypercube where we stacked
 $k$ hypercubes on the dimension
 $k\in [n]$; we also prove that the first jumping times of regular Mallows processes converge to a Poisson point process; we eventually provide results regarding the Markov property of the discrete jumping chain corresponding to a Mallows process.


Longest increasing subsequences for distributions with atoms, and an inhomogeneous Hammersley process
- Part of
-
- Journal:
- Combinatorics, Probability and Computing , First View
- Published online by Cambridge University Press:
- 26 October 2026, pp. 1-28
-
- Article
-
- You have access
- Open access
- HTML
- Export citation
-
We investigate the asymptotic behaviour of the longest increasing subsequence
 $L_n$ in a sequence of i.i.d. random variables, for an arbitrary distribution. If the common distribution is atomless then a famous result by Hammersley and Veršik-Kerov states that
 $L_n$ grows like
 $2\sqrt {n}$. For any discrete distribution, we characterize the asymptotic order of
 $L_n$ through a variational problem and provide explicit estimates for classical distributions. The proofs rely on a coupling with an inhomogeneous version of the discrete-time continuous-space Hammersley process. This reveals that, in contrast to the continuous case, the discrete setting exhibits a wide range of growth rates between
 $\mathcal{O}(1)$ and
 $o(\sqrt {n})$, depending on the tail behaviour of the distribution. We can then easily deduce the asymptotics of
 $L_n$ for a completely arbitrary distribution.


Rare event probabilities in random geometric graphs
- Part of
-
- Journal:
- Advances in Applied Probability , First View
- Published online by Cambridge University Press:
- 14 September 2026, pp. 1-27
-
- Article
-
- You have access
- HTML
- Export citation
-
We study rare events in spherical and Gaussian random geometric graphs in high dimensions. In these models, the vertices correspond to points sampled uniformly at random on the d-dimensional unit sphere or correspond to d-dimensional standard Gaussian vectors, and edges are added between two vertices if the inner product between their corresponding points is greater than a threshold
 $t_{p}$, chosen such that the probability of having an edge is equal to p. We focus on two problems: (a) the probability that the random geometric graph is a complete graph and (b) the probability of observing an atypically large number of edges. We obtain asymptotically exponential decay rates depending on n and d of the probabilities of these rare events through a combination of geometric and probabilistic arguments.

Computing volume of a polytope and integrals in high dimensions deterministically
- Part of
-
- Journal:
- Combinatorics, Probability and Computing , First View
- Published online by Cambridge University Press:
- 14 September 2026, pp. 1-33
-
- Article
-
- You have access
- HTML
- Export citation
-
We design a Correlation-Decay based quasi-polynomial time deterministic approximation algorithm for computing high dimensional integrals, applied in two settings. The first is computing the volume of an independent set polytope with restrictions. Randomized polynomial time approximation algorithms for computing the volume of a convex body have been known now for several decades, but the corresponding deterministic counterparts are not available, and our algorithm is the first of this kind. The class of polytopes for which our algorithm applies arises as linear programming relaxation of the independent set problem with the additional restriction that each variable takes value in the interval
 $[0,1-\alpha ]$ for some
 $\alpha \lt 1/2$. (We note that the
 $\alpha \ge 1/2$ case is trivial). The method works provided
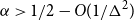 $\alpha \gt 1/2-O(1/\Delta ^2)$, where
 $\Delta$ is the maximum degree of the graph. When
 $\Delta =3$ (the sparsest non-trivial case), our method works provided
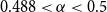 $0.488\lt \alpha \lt 0.5$. Our second setting is to compute the integral of a multi-dimensional separable function, supported by some underlying hyper-graph structure, appropriately defined. Equivalently, our integral is the partition function of a graphical model with continuous potentials. For our method to work, we require that the domain is bounded and the hyper-edge potentials are positive and bounded on the domain. We further assume that the potentials have upper and lower bounds separated by a multiplicative factor of
 $1 + O(1/\Delta ^2)$, where
 $\Delta$ is the maximum degree of the graph.


The k-window statistic in a random permutation
- Part of
-
- Journal:
- Journal of Applied Probability , First View
- Published online by Cambridge University Press:
- 03 September 2026, pp. 1-20
-
- Article
-
- You have access
- HTML
- Export citation
-
We introduce a new permutation statistic, which we call the k-window statistic, for permutations of
 $\{1,2,\ldots, n\}$. The aim is to add to the repertoire of potentially useful tools in the design of efficient algorithms. The k-window statistic counts the number of elements that are at a displacement at most k from their natural positions in the ascendingly sorted permutation. We find the exact mean and exact variance of the k-window statistic, revealing phases in the mean and variance in the different regimes of k. We find a weak (or even strong) law of large numbers in the regime where
 $k=k_n$ is growing but remains
 ${\mathrm{o}} (n)$. Via a representation of the statistic into dependent heterogeneous weakly correlated indicators, we establish the complete spectrum of distributions as
 $k_n$ spans its entire range using an appropriate method for each regime.


The feasibility of multi-graph alignment: A Bayesian approach
- Part of
-
- Journal:
- Advances in Applied Probability , First View
- Published online by Cambridge University Press:
- 21 July 2026, pp. 1-40
-
- Article
-
- You have access
- Open access
- HTML
- Export citation
Optimal thresholds for monotone non-Boolean functions
- Part of
-
- Journal:
- Combinatorics, Probability and Computing / Volume 35 / Issue 5 / September 2026
- Published online by Cambridge University Press:
- 21 July 2026, pp. 734-746
-
- Article
-
- You have access
- HTML
- Export citation
-
Let
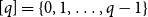 $[q] = \{0,1,\ldots ,q-1\}$, let
 $\Delta [q]$ denote the simplex of probability measures on
 $[q]$, and let
 $\gamma$ denote the Lebesgue measure normalized on
 $\Delta [q]$. We prove that for any symmetric monotone function
 ${\kern1pt}f \colon{\kern-1pt} [q]^n \to [q]$ and any
 $a \in [q]$, we have
 \begin{equation*} \gamma (\{\mu \in \Delta [q]\;\vert \;\mathbb{P}_{x\sim \mu ^{\otimes n}}[\,f(x)=a] \in (\varepsilon ,1-\varepsilon )\}) = O(1/\log n)\text{.} \end{equation*}
We also show that this bound is tight. This improves Kalai and Mossel's previous bound of
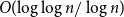 $O(\!\log \log n/\log n)$ and answers their question completely.


Computing the probability of intersection
- Part of
-
- Journal:
- Combinatorics, Probability and Computing / Volume 35 / Issue 5 / September 2026
- Published online by Cambridge University Press:
- 19 June 2026, pp. 714-733
-
- Article
-
- You have access
- Open access
- HTML
- Export citation
-
Let
 $\Omega _1, \ldots , \Omega _m$ be probability spaces, let
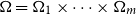 ${\mathbf \Omega }=\Omega _1 \times \cdots \times \Omega _m$ be their product and let
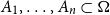 $A_1, \ldots , A_n \subset {\mathbf \Omega }$ be events. Suppose that each event
 $A_i$ depends on
 $r_i$ coordinates of a point
 $x \in {\mathbf \Omega }$,
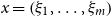 $x=\left (\xi _1, \ldots , \xi _m\right )$, and that for each event
 $A_i$ there are
 $\Delta _i$ other events
 $A_j$ that depend on some of the coordinates that
 $A_i$ depends on. Let
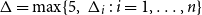 $\Delta =\max \{5,\ \Delta _i\,:\, i=1, \ldots , n\}$ and let
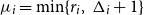 $\mu _i=\min \{r_i,\ \Delta _i+1\}$ for
 $i=1, \ldots , n$. We prove that if
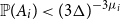 ${\mathbb P}(A_i) \lt (3\Delta )^{-3\mu _i}$ for all
 $i$, then for any
 $0 \lt \epsilon \lt 1$, the probability
 ${\mathbb P}\left ( \bigcap _{i=1}^n \overline {A}_i\right )$ of the intersection of the complements of all
 $A_i$ can be computed within relative error
 $\epsilon$ in polynomial time from the probabilities
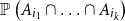 ${\mathbb P}\left (A_{i_1} \cap \ldots \cap A_{i_k}\right )$ of
 $k$-wise intersections of the events
 $A_i$ for
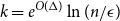 $k = e^{O(\Delta )} \ln (n/\epsilon )$.


The number of connected components in sub-critical random graph processes
- Part of
-
- Journal:
- Journal of Applied Probability , First View
- Published online by Cambridge University Press:
- 16 June 2026, pp. 1-13
-
- Article
-
- You have access
- HTML
- Export citation
Diffusion limited aggregation in the layers model
- Part of
-
- Journal:
- Journal of Applied Probability , First View
- Published online by Cambridge University Press:
- 28 April 2026, pp. 1-29
-
- Article
-
- You have access
- Open access
- HTML
- Export citation
Brochette first-passage percolation
- Part of
-
- Journal:
- Journal of Applied Probability / Volume 63 / Issue 3 / September 2026
- Published online by Cambridge University Press:
- 14 April 2026, pp. 1281-1301
- Print publication:
- September 2026
-
- Article
-
- You have access
- HTML
- Export citation
-
We investigate a novel first-passage percolation model, referred to as the Brochette first-passage percolation model, where the passage times associated with edges lying on the same line are equal. First, we establish a point-to-point convergence theorem, identifying the time constant. In particular, we explore the case where the time constant vanishes and demonstrate the existence of a wide range of possible behaviours. Next, we prove a shape theorem, showing that the limiting shape is the
 $L^1$ diamond. Finally, we extend the analysis by proving a point-to-point convergence theorem in the setting where passage times are allowed to be infinite.

Perfect partitions of a random set of integers
- Part of
-
- Journal:
- Journal of Applied Probability , First View
- Published online by Cambridge University Press:
- 06 April 2026, pp. 1-30
-
- Article
-
- You have access
- Open access
- HTML
- Export citation
-
Let
 $X_1,\ldots, X_n$ be independent integers distributed uniformly on [M],
 $M\ge 2$. A partition S of [n] into
 $\nu$ non-empty subsets
 $S_1,\ldots, S_{\nu}$ is called perfect if all
 $\nu$ values
 $\sum_{j\in S_{\alpha}}X_j$ are equal. For a perfect partition to exist,
 $\sum_j X_j$ has to be divisible by
 $\nu$. In 2001, for
 $\nu=2$, Christian Borgs, Jennifer Chayes, and the author proved that, conditioned on
 $\sum_j X_j$ being even, with high probability a perfect partition exists if
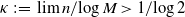 $\kappa\;:\!=\; \lim {{n}/{\log M}}>{{1}/{\log 2}}$, and that with high probability no perfect partition exists if
 $\kappa<{{1}/{\log 2}}$. Responding to a question by George Varghese, we prove that for
 $\nu\ge 3$ with high probability no perfect partition exists if
 $\kappa<{{2}/{\log \nu}}$, which is twice as large as the naive threshold
 $1/\log 3$ for
 $\nu=3$. We identify the range of
 $\kappa$ where the expected number of perfect partitions is exponentially high. We show that for
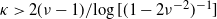 $\kappa> {{2(\nu-1)}/{\log[(1-2\nu^{-2})^{-1}]}}$ the total number of perfect partitions is exponentially high with probability
 $\gtrsim (1+\nu^2)^{-1}$, i.e. below
 $1/\nu$, the limiting probability that
 $\sum_j X_j$ is divisible by
 $\nu$.


Record-biased permutations and their permuton limit
- Part of
-
- Journal:
- Combinatorics, Probability and Computing / Volume 35 / Issue 3 / May 2026
- Published online by Cambridge University Press:
- 27 March 2026, pp. 375-413
-
- Article
-
- You have access
- HTML
- Export citation
The random
 $\textit{k}$-SAT Gibbs uniqueness threshold revisited
- Part of
-
- Journal:
- Combinatorics, Probability and Computing / Volume 35 / Issue 4 / July 2026
- Published online by Cambridge University Press:
- 27 March 2026, pp. 433-485
-
- Article
-
- You have access
- Open access
- HTML
- Export citation
-
We prove that for any
 $k\geq 3$ for clause/variable ratios up to the Gibbs uniqueness threshold of the corresponding Galton-Watson tree, the number of satisfying assignments of random
 $k$-SAT formulas is given by the ‘replica symmetric solution’ predicted by physics methods [Monasson, Zecchina: Phys. Rev. Lett. 76 (1996)]. Furthermore, while the Gibbs uniqueness threshold is still not known precisely for any
 $k\geq 3$, we derive new lower bounds on this threshold that improve over prior work [Montanari and Shah: SODA (2007)]. The improvement is significant particularly for small
 $k$.


Trace reconstruction of matrices and hypermatrices
- Part of
-
- Journal:
- Combinatorics, Probability and Computing / Volume 35 / Issue 3 / May 2026
- Published online by Cambridge University Press:
- 10 March 2026, pp. 356-374
-
- Article
-
- You have access
- HTML
- Export citation
-
A trace of a sequence is generated by deleting each bit of the sequence independently with a fixed probability. The well-studied trace reconstruction problem asks how many traces are required to reconstruct an unknown binary sequence with high probability. In this paper, we study the multidimensional version of this problem for matrices and hypermatrices, where a trace is generated by deleting each row/column of the matrix or each slice of the hypermatrix independently with a constant probability. Previously, Krishnamurthy, Mazumdar, McGregor and Pal showed that
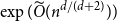 $\exp (\widetilde {O}(n^{d/(d+2)}))$ traces suffice to reconstruct any unknown
 $n\times n$ matrix (for
 $d=2$) and any unknown
 $n^{\times d}$ hypermatrix. By developing a dimension reduction procedure and establishing a multivariate version of the Littlewood-type result that lower bounds sparse complex polynomials around
 $1$, we improve this upper bound by showing that
 $\exp (\widetilde {O}(n^{3/7}))$ traces suffice to reconstruct any unknown
 $n\times n$ matrix, and
 $\exp (\widetilde {O}(n^{3/5}))$ traces suffice to reconstruct any unknown
 $n^{\times d}$ hypermatrix. In contrast to the earlier bound, our new exponent is bounded away from
 $1$ even as
 $d$ becomes very large.


Analysis of clustering and degree index in random graphs and complex networks
- Part of
-
- Journal:
- Journal of Applied Probability / Volume 63 / Issue 3 / September 2026
- Published online by Cambridge University Press:
- 05 March 2026, pp. 919-949
- Print publication:
- September 2026
-
- Article
-
- You have access
- Open access
- HTML
- Export citation
Monochromatic subgraphs in randomly colored dense multiplex networks
- Part of
-
- Journal:
- Advances in Applied Probability , First View
- Published online by Cambridge University Press:
- 05 March 2026, pp. 1-36
-
- Article
-
- You have access
- HTML
- Export citation
-
Given a sequence of graphs
 $G_n$ and a fixed graph H, denote by
 $T(H, G_n)$ the number of monochromatic copies of the graph H in a uniformly random c-coloring of the vertices of
 $G_n$. In this paper we study the joint distribution of a finite collection of monochromatic graph counts in networks with multiple layers (multiplex networks). Specifically, given a finite collection of graphs
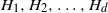 $H_1, H_2, \ldots, H_d$ we derive the joint distribution of
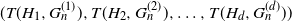 $(T(H_1, G_n^{(1)}), T(H_2, G_n^{(2)}), \ldots, T(H_d, G_n^{(d)}))$, where
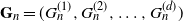 $\mathbf{G}_n = (G_n^{(1)}, G_n^{(2)}, \ldots, G_n^{(d)})$ is a collection of dense graphs on the same vertex set converging in the multiplex cut-metric. The limiting distribution is the sum of two independent components: a multivariate Gaussian and a sum of independent bivariate stochastic integrals. This extends previous results on the marginal convergence of monochromatic subgraphs in a sequence of graphs to the joint convergence of a finite collection of monochromatic subgraphs in a sequence of multiplex networks. Several applications and examples are discussed.


The largest subcritical component in inhomogeneous random graphs of preferential attachment type
- Part of
-
- Journal:
- Combinatorics, Probability and Computing / Volume 35 / Issue 3 / May 2026
- Published online by Cambridge University Press:
- 04 March 2026, pp. 414-432
-
- Article
-
- You have access
- Open access
- HTML
- Export citation
Differential transcendence and walks on self-similar graphs
- Part of
-
- Journal:
- Canadian Mathematical Bulletin , First View
- Published online by Cambridge University Press:
- 30 January 2026, pp. 1-21
-
- Article
-
- You have access
- Open access
- HTML
- Export citation
-
Symmetrically self-similar graphs are an important type of fractal graph. Their Green’s functions satisfy order one iterative functional equations. We show that when the branching number of a generating cell is two, either the graph is a star consisting of finitely many one-sided lines meeting at an origin vertex, in which case the Green’s function is algebraic, or the Green’s function is differentially transcendental over
 $\mathbb {C}(z)$. The proof strategy relies on a result in a recent preprint of Di Vizio, Fernandes, and Mishna. The result adds evidence to a conjecture of Krön and Teufl about the spectra of the difference Laplacian of this family of graphs.

Random Fibonacci Words via Clone Schur Functions
- Part of
-
- Journal:
- Forum of Mathematics, Sigma / Volume 14 / 2026
- Published online by Cambridge University Press:
- 23 January 2026, e15
-
- Article
-
- You have access
- Open access
- HTML
- Export citation
-
We investigate positivity and probabilistic properties arising from the Young–Fibonacci lattice
 $\mathbb {YF}$, a 1-differential poset on words composed of 1’s and 2’s (Fibonacci words) and graded by the sum of the digits. Building on Okada’s theory of clone Schur functions, we introduce clone coherent measures on
 $\mathbb {YF}$ which give rise to random Fibonacci words of increasing length. Unlike coherent systems associated to classical Schur functions on the Young lattice of integer partitions, clone coherent measures are generally not extremal on
 $\mathbb {YF}$. Our first main result is a complete characterization of Fibonacci positive specializations – parameter sequences which yield positive clone Schur functions on
 $\mathbb {YF}$. Second, we establish a broad array of correspondences that connect Fibonacci positivity with: (i) the total positivity of tridiagonal matrices; (ii) Stieltjes moment sequences; (iii) the combinatorics of set partitions; and (iv) families of univariate orthogonal polynomials from the (q-)Askey scheme. We further link the moment sequences of broad classes of orthogonal polynomials to combinatorial structures on Fibonacci words, a connection that may be of independent interest. Our third family of results concerns the asymptotic behavior of random Fibonacci words derived from various Fibonacci positive specializations. We analyze several limiting regimes for specific examples, revealing stick-breaking-like processes (connected to GEM distributions), dependent stick-breaking processes of a new type, or limits supported on the discrete component of the Martin boundary of the Young–Fibonacci lattice. Our stick-breaking-like scaling limits significantly extend the result of Gnedin–Kerov on asymptotics of the Plancherel measure on
 $\mathbb {YF}$. We also establish Cauchy-like identities for clone Schur functions whose right-hand side is presented as a quadridiagonal determinant rather than a product, as in the case of classical Schur functions. We construct and analyze models of random permutations and involutions based on Fibonacci positive specializations along with a version of the Robinson–Schensted correspondence for
 $\mathbb {YF}$.


